Zero-Shot Segmentation in Manufacturing: What It Can and Cannot Do

Table of Contents

Summarize and analyze this article with

Segmentation has long been one of the most labor-intensive steps in a vision project. Every defect, component edge, or region of interest had to be outlined by hand, pixel by pixel, often across thousands of images.
Promptable foundation models changed that cost structure, at least in principle. An object can now be pointed at, or described, and a mask returned without task-specific training.
The question for quality and engineering teams is how much of that holds up on a real line. While zero-shot segmentation in manufacturing is useful for a defined set of jobs, it is unsuitable for others. This guide separates the two, explains why, and sets out a practical way to test it before anyone commits budget.

Key Takeaways

What zero-shot segmentation means in industrial inspection

Segmentation assigns each pixel in an image to a region: this area is the part, that area is a scratch, the rest is background. Traditional segmentation models learn those regions from hand-drawn masks on the exact task they will perform.
Zero-shot segmentation skips that task-specific training. A foundation model pretrained on a very large, general dataset is prompted at runtime with a point, a bounding box, or, in some setups, a text description, and returns a mask. The best-known example is Meta AI Research’s Segment Anything Model (SAM). Its authors assembled a dataset of over 1 billion masks on 11 million licensed images and trained the model to be promptable so that it transfers zero-shot to new image distributions and tasks.
That scale is the reason the approach generalizes. It is also the reason for caution. None of those images were taken on your line, under your lighting, of your product parts.

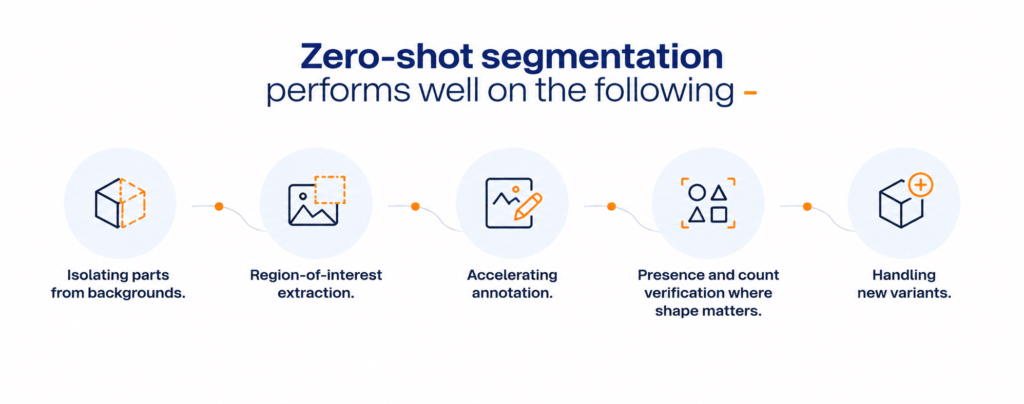
Where zero-shot segmentation performs well

The strongest fits share one trait: the region being segmented is visually distinct from its surroundings.
In each case, the model performs localization. It reports where something is. A separate step decides whether that something is acceptable.

Where zero-shot segmentation is unreliable
The limitations map closely onto the defect types manufacturers care about most.

Fine and low-contrast defects

Hairline cracks, micro-scratches, faint discoloration, and subtle porosity often lack clear edges. The SAM authors state that the model can miss fine structures, sometimes generates small disconnected components, and does not produce boundaries as crisply as more computationally intensive methods.[1] On a production line, a missed hairline crack is not a small error to be overlooked.

Acceptance criteria

A mask is not a verdict. The model can outline a mark on a surface without any sense of whether that mark is cosmetic, within tolerance, or cause for rejection. Acceptance criteria live in your quality system, not in a general-purpose model.

Consistency across imaging conditions

Glare, reflective metal, transparent packaging, and shifting ambient light can change results from one frame to the next. The absence of task-specific training does not reduce a model’s sensitivity to imaging conditions.

Speed at line rate

Large foundation models are computationally heavy. Where a decision must be made inside a single machine cycle, the full model may not keep pace without dedicated hardware or a lighter distilled version.

Zero-shot detection vs. segmentation: which does your inspection need?

The two terms are often blended, and the difference affects system design. Zero-shot detection in industrial inspection draws a box around a candidate and assigns a label. Zero-shot segmentation draws the outline. Detection is usually sufficient for presence, position, and counting, and it costs less to run. Segmentation earns its additional compute when shape, area, or boundary precision matters, such as measuring a coating gap or the extent of a surface defect.
Aspect Zero-shot detection Zero-shot segmentation
Output A box and a label A pixel-level outline (mask)
Best for Presence, position, and counting Shape, area, and boundary precision
Compute cost Lower Higher
Example Confirming a part is present Measuring a coating gap or defect extent
Teams often chain the two. An open-vocabulary detection model locates candidate regions from a text prompt in production, and a segmentation model outlines what sits inside each box.

Where does the Segment Anything Model (SAM) fit in manufacturing workflows?

The roles above differ mainly in how much human judgment sits between the mask and the decision, and that is what should order a SAM manufacturing rollout. Exploratory analysis of archived images carries no line risk, because nothing reaches production. Annotation assistance comes next, because an engineer approves every mask before it becomes training data. Preprocessing follows, since a trained classifier still makes the call on the cropped region.
A fourth role, treating the model as the final accept-or-reject authority, is where most disappointment occurs. It is rarely the right starting point.

How do vision-language models and segmentation models work together?

Foundation models for visual inspection increasingly work as a set rather than alone. A vision-language model can be asked whether an image shows anything unusual and to describe it. A segmentation model then outlines the region it points to. That pattern is behind most current interest in vision-language models for defect detection, particularly for unfamiliar anomalies. It also stacks two sources of uncertainty, so validation on your own images matters more.

How do you test zero-shot segmentation on your production line? 7 steps

A short, structured test answers most questions before a full project starts. Seven steps cover the ground.
  1. Assemble a hard evaluation set: Include your subtle defects, reflective parts, and worst lighting, not only clear examples.
  2. Define success in operational terms: Mask overlap scores are useful, but the decisive question is whether the mask would lead to the right part disposition: accept, rework, or reject.
  3. Compare prompt types: Points, boxes, and text prompts behave differently. Test the one you would actually use in production.
  4. Measure speed on target hardware: Benchmark on the device that would sit near the line, not a research workstation.
  5. Repeat across shifts and variants: Run the same prompts on images from different shifts, operators, lighting states, and a recent part variant, to see whether performance holds without adjustment.
  6. Record how it fails, not only how often: A model that misses in predictable ways is easier to manage than one that fails at random, and a clear list of what it misses is as valuable as an accuracy score.
  7. Check review time and traceability: If reviewing uncertain masks takes longer than manual inspection, the workflow needs redesign. Record model version, prompt, and image for each output so decisions can be audited later, a standard practice in production MLOps pipelines.
If a zero-shot model performs well only after heavy prompt tuning on a handful of images, run the same prompts on a fresh batch before trusting the result. Overfitting prompts is easier than it looks.

When should you move from zero-shot to a fine-tuned model?

Move beyond zero-shot when fine defects dominate, tolerances are tight, or decisions must be made within a machine cycle. Zero-shot segmentation for industrial inspection is often the fastest way to learn whether a computer vision inspection project is tractable, but it is not always the final answer. In those cases, the usual next step is fine-tuning on a modest set of your own images or distilling results into a smaller model.

How Intuceo approaches segmentation work

Intuceo starts with the inspection decision the business needs, then works backward to whether segmentation, detection, or a simpler rule is the right tool. Scope your inspection use case with an AI architect.

Two capabilities carry most of the delivery on vision work. High-fidelity visual inspection applies image segmentation, sub-pixel anomaly detection, and automated feature extraction to sub-millimeter defects, including precision medical optics, where surface anomalies, edge irregularities, and contaminants have to be caught at production speed. Multi-modal vision intelligence brings video, image, and metadata streams together so inspection results arrive alongside line system signals rather than in a separate console.

Deployment is the part that has to survive audit. Intuceo delivers in on-premise, private cloud, and air-gapped environments, driven by PhD-led engineering teams with prior deployments in regulated and high-precision environments. See how this applies across AI-driven advanced manufacturing and to the ML and computer vision capability built for it.

Join AI Dream Session, Vol. 2: Computer Vision Reimagined

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute live session with Intuceo on Thursday, September 24, 2026, at 11:00 AM ET. It covers how newer vision models reduce dependence on large labeled datasets, and where accuracy and production conditions still create hard problems.

Frequently Asked Questions

It is the ability to outline objects or regions in an image using a pretrained foundation model, guided by a prompt such as a point, box, or text description, without training on your specific parts. In inspection, it is most often used to isolate components, extract regions of interest, and speed up labeling, rather than to make final quality decisions on its own.
Not entirely. They can sharply reduce the labeling needed to get started and can pre-label images for engineers to correct. You still need a labeled evaluation set from your own line to confirm performance, and many subtle defect types still benefit from fine-tuning on examples specific to your process.
Four limits dominate: weak performance on fine or low-contrast defects, no built-in understanding of acceptance criteria, sensitivity to glare and lighting changes, and heavy compute requirements for large models.
Yes, in well-chosen roles: annotation assistance, preprocessing that isolates parts or regions, and exploration of archived images. Using them as the sole accept-or-reject authority is riskier.
Not always. Large foundation models are computationally heavy, so decisions inside a single machine cycle may need dedicated hardware or a smaller distilled model.