
Informatica’s 2025 global survey of data leaders found that two-thirds had not moved even half of their generative artificial intelligence (AI) pilots into production. Asked what made business value hard to demonstrate, respondents cited cybersecurity and privacy compliance (46%), uncertainty over responsible use of AI (45%), reliability of results (43%), and lack of trust in data quality (38%).[1] Each of these is a question an AI data governance framework exists to answer: who may use the data, for what purpose, at what level of quality, and with what evidence.
A framework designed around certified reports can confirm who may view a table, but it may have no record of whether that table may train a model. The practical task is to build a data governance framework that enterprise AI teams can work within, one that settles access, quality, and accountability at the pace AI delivery requires.
Key Takeaways
- Data governance sets decision rights. AI requests stall when no one has clear authority to approve them.
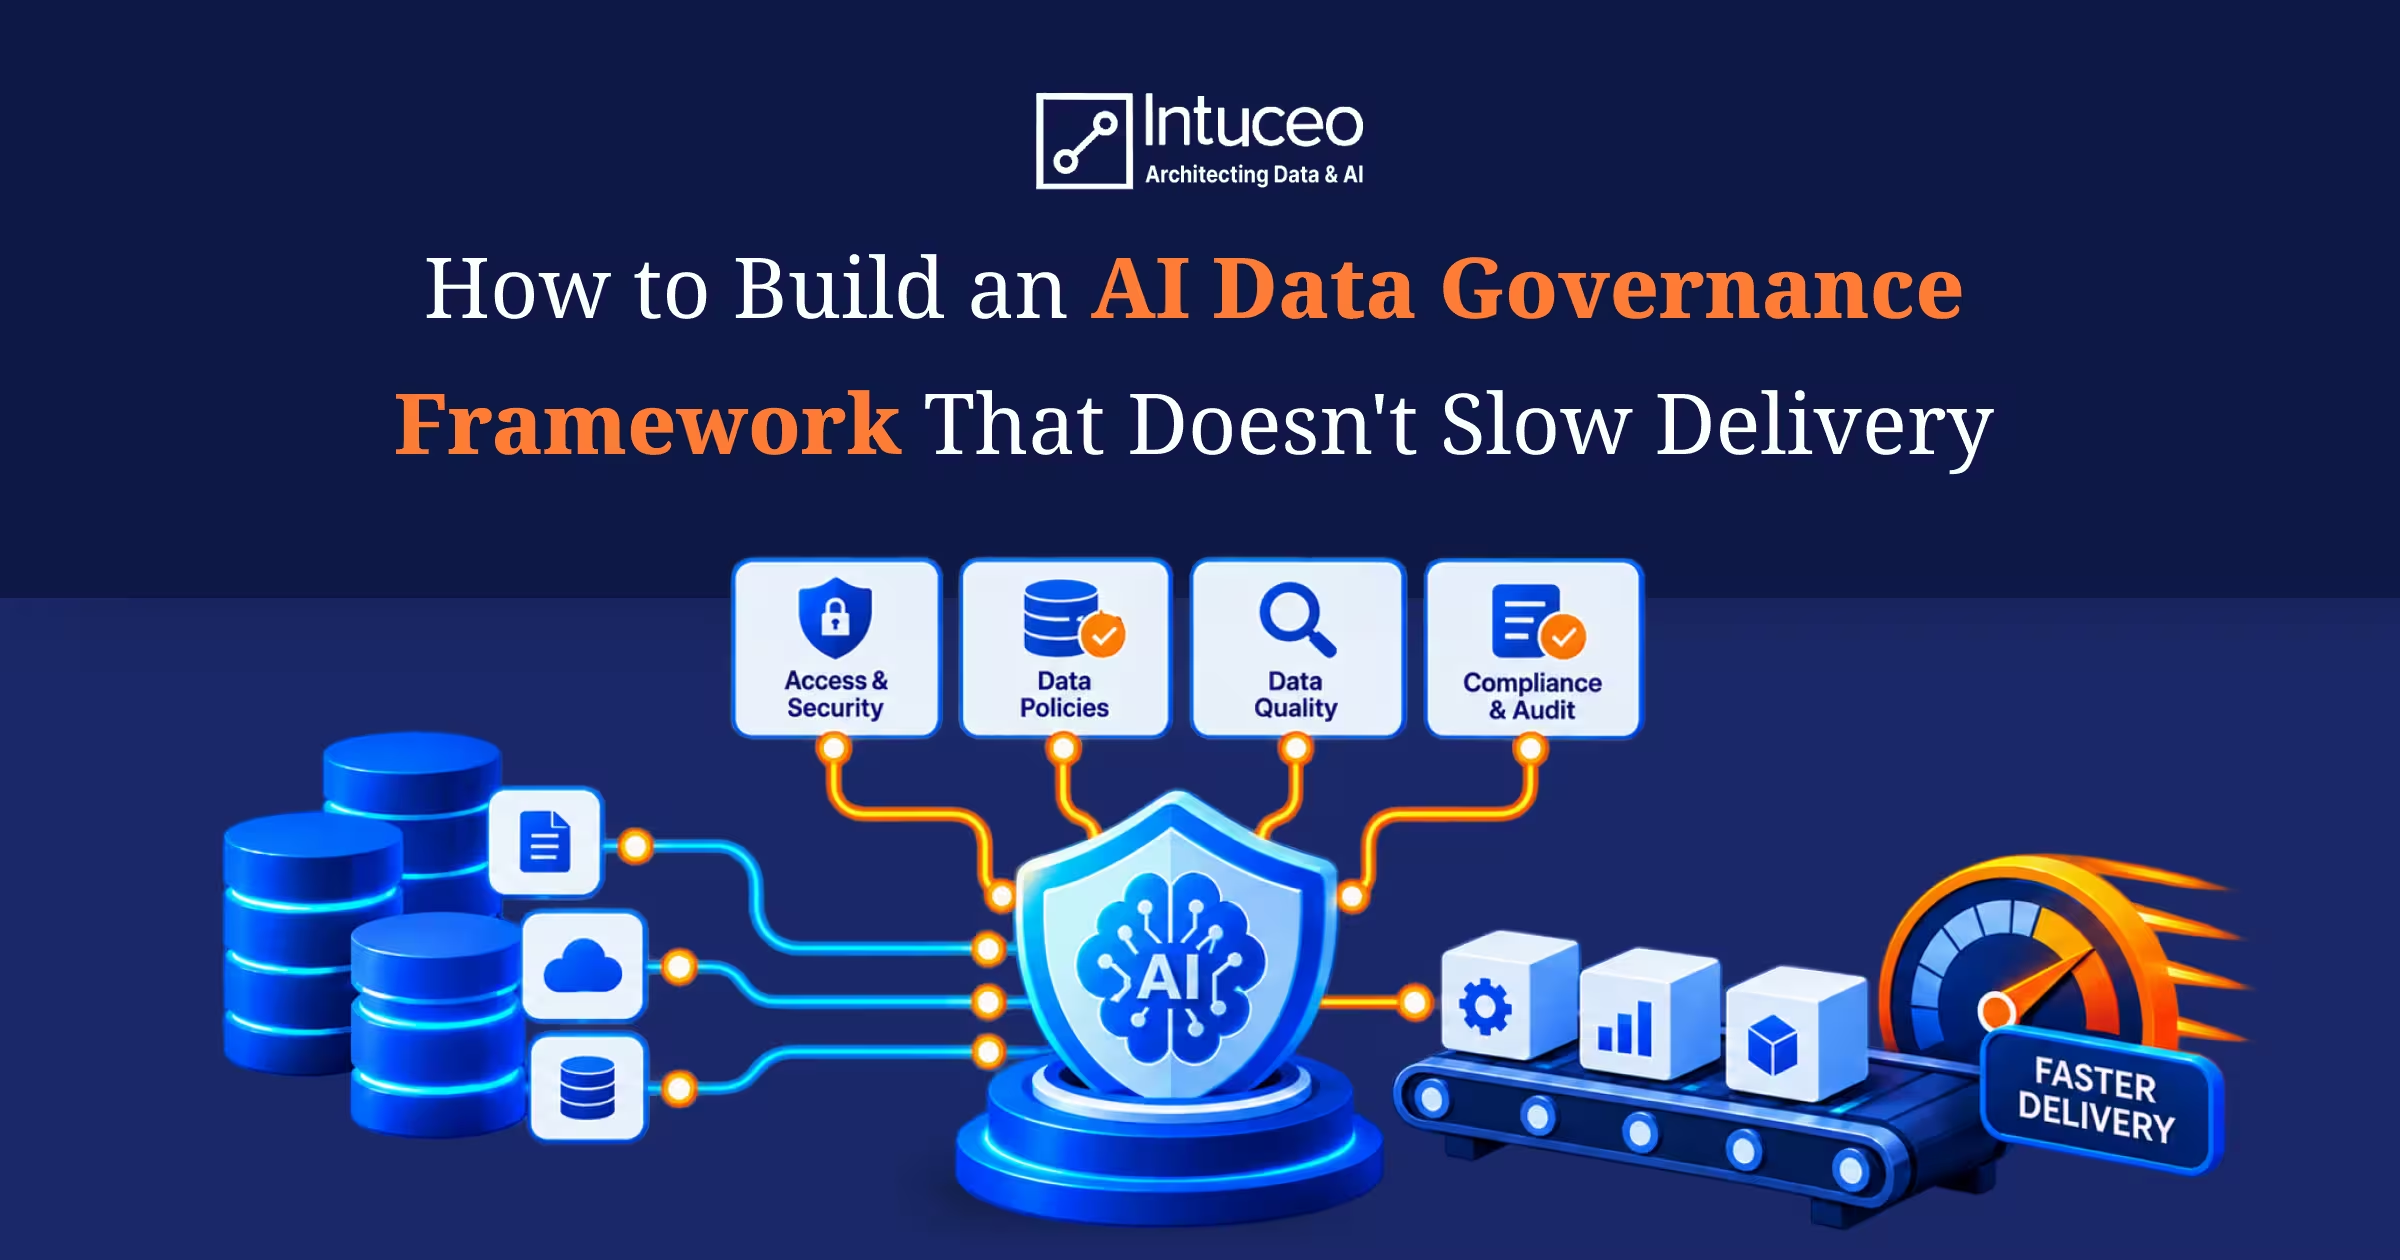
- An AI data governance framework has six components: ownership, an AI-aware catalog, automated quality rules, lineage to the model, privacy controls, and an AI usage policy.
- Approve-by-default rules with SLAs, a separate discovery space, and automatically captured evidence keep governance from becoming a queue.
- The EU AI Act (Article 10) and SR 26-2 both expect documented data quality, which lineage and approval logs supply.
What Is an AI Data Governance Framework?
An AI data governance framework is the set of decision rights, policies, controls, and roles that determines which data may train, ground, or feed an AI model, at what quality, and with what evidence. It extends traditional data governance from tables and reports to training datasets, features, prompts, and model outputs.
What Is the Difference Between Data Governance and Data Management?
Data governance decides who may use data and for what purpose, while data management carries out the work. The data governance vs data management distinction matters for AI programs because it determines who can say yes to a request. Data management is the execution work: building pipelines, maintaining storage, running quality checks, and securing systems. Data governance sets the decision rights that direct that work, covering who owns a dataset, who may use it and for what purpose, what quality threshold it must meet, and who resolves disputes. When those rights are undefined, an AI team asking for training data has no one with clear authority to approve the request, and it stalls in review.
The Data Management Association’s Data Management Body of Knowledge (DAMA-DMBOK), a framework AI teams can build on, reflects this relationship by placing data governance at the center of its wheel, with 11 knowledge areas such as data quality, metadata, and data security arranged around it.[2] DAMA International states that the body of knowledge is not prescriptive and must be adapted to each organization’s environment.[3] For AI programs, adaptation means extending each knowledge area to new assets, such as training datasets and model outputs, and to new questions, such as whether a dataset is fit for a specific model purpose.
How Is Data Governance for AI Different From Traditional BI Governance?
Business intelligence (BI) governance is organized around curated tables, metrics, and certified reports that analysts review before acting. Data governance for AI extends that scope in the following ways.
| Dimension | Traditional BI | AI workloads |
|---|---|---|
| Governed assets | Tables, metrics, and reports | Training, validation, and test datasets, features, embeddings, prompts, and model outputs |
| Quality standard | Accurate and consistent with business definitions | Also representative of the population and context in which the model will operate |
| Lineage depth | Source system to dashboard | Source system to dataset version, model version, and individual output |
| Rate of change | Periodic schema and definition updates | Frequent retraining, new sources, and drift in production data |
| Consumers | Analysts who review outputs | Models and agents, which can act on outputs without a person reviewing each one |
| Usage questions | Who may view the data | Who may view it, and whether it may train or ground a model |
The final row has legal weight. Under the General Data Protection Regulation (GDPR), personal data must be collected for specified, explicit, and legitimate purposes and not further processed in a manner incompatible with those purposes.[4] A customer service dataset approved for operational reporting therefore does not carry automatic permission to train a churn or pricing model. When the catalog records each dataset’s collection purpose and approved uses, that check becomes a lookup instead of a fresh legal review.
What Are the Core Components of an AI Data Governance Framework?
The AI data governance best practices below are organized as six components, each tied to a question an AI team must be able to answer before a model reaches production. Scope each one first to the data that active AI use cases touch, then extend it to the wider data estate.
- Ownership and decision rights (who can approve this use?): Every data domain has a named business owner with authority over access and acceptable use, supported by stewards who maintain definitions and metadata. A governance board handles only the requests that fall outside agreed rules.
- A catalog with AI context (what is this data, and what may it be used for?): A data catalog that AI program teams can search should record more than schema and location. Sensitivity classification, approved uses, training eligibility, known limitations, and the models already consuming a dataset give requesters and approvers the same reference point.
- Quality rules enforced in code (is this data fit to train on today?): Reliable data quality in the AI pipeline depends on rules that run automatically at ingestion and before each training run, with results published as scorecards so data owners and model teams review the same evidence.
- Lineage through to the model (what does a change upstream affect?): Lineage should connect source systems to dataset versions, model versions, and outputs, so teams can see which models a source change affects and auditors can trace a decision back to its inputs.
- Privacy, access, and consent controls (does this dataset contain sensitive data?): Automated scanning for personally identifiable information (PII) and protected health information (PHI), role-based access, masking, and consent tracking keep sensitive data out of training sets unless an approved purpose exists.
- An AI-specific usage policy (what must be documented before production?): Written rules for AI training data governance cover training eligibility, retention of training snapshots, use of third-party and synthetic data, and the documentation required before a dataset can support a production model.
How Do You Keep Data Governance From Slowing AI Delivery?
The components define what an AI data governance framework covers. The operating model governs how long a request waits, and four design choices address the points where an AI request can queue: approval, experimentation, documentation, and measurement.
Approve by default within defined rules
Requests for general data access, dataset creation, or ingestion that carry a valid business purpose should be approved automatically, or by the data owner within a stated service level agreement (SLA). Board review is reserved for exceptions such as personal or restricted data. Reviewers can grant partial or conditional approval where outright approval is not possible.
Separate discovery from production
Model development involves testing candidate datasets that may never reach production. A governed discovery space with masked or sampled data and lighter controls lets teams prototype quickly. Full controls apply at the point of promotion into a controlled production space, where datasets are certified, versioned, and documented. Governance effort then concentrates at the point where data begins to influence production decisions.
Generate evidence automatically
Approval workflows, quality results, lineage, and access logs should be captured by the systems doing the work. Records captured as actions occur are timestamped and attributable, so an auditor’s question about who approved a training dataset can be answered directly from the log.
Measure governance as a service
Track request turnaround against SLA, the share of requests resolved without escalation, and the number of production incidents traced to data issues. Together, these measures show where governance adds protection and where it only adds delay. To see where your own requests wait, benchmark your governance approval flow with Intuceo’s team.
What Does a Data Steward Do in an AI-First Organization?
The data stewardship that enterprise teams already run for reporting covers definitions, reference data, and quality issues. AI use cases add checks that regulation now names explicitly: the European Union (EU) Artificial Intelligence Act, for example, expects high-risk system providers to examine training data for possible biases and to identify data gaps.[5] Unless a role owns these checks, they fall between data and model teams. Assigning them to stewards means writing four duties into the role:
- Certifying datasets for model use: Confirming that a dataset is fit for a stated model purpose, including its representativeness and known gaps.
- Maintaining AI-relevant metadata: Keeping sensitivity tags, approved uses, and documented limitations current in the catalog.
- Triaging quality alerts: Deciding whether a failed rule blocks a training run or is recorded as an accepted limitation.
- Resolving routine access requests: Applying the data owner's rules so that only genuine exceptions reach the governance board.
Why Is Data Governance the Foundation of Responsible AI in Regulated Industries?
In regulated sectors, data governance for responsible AI works by producing evidence that a model was built on appropriate data. The EU Artificial Intelligence Act makes this explicit for high-risk systems. Article 10 requires training, validation, and testing datasets to be subject to governance practices covering data collection and origin, preparation operations, examination of possible biases, and identification of data gaps. It also requires those datasets to be relevant, sufficiently representative, and, to the best extent possible, free of errors and complete for the system’s intended purpose.[5]
United States banking supervisors set a comparable expectation for predictive models. The revised interagency guidance on model risk management, issued in April 2026 by the Federal Reserve, Office of the Comptroller of the Currency (OCC), and Federal Deposit Insurance Corporation (FDIC) as SR 26-2, describes model testing as including a critical assessment of data quality, relevance, and inputs. It places generative and agentic AI outside its scope, leaving controls for those models to each organization’s own governance practices.[6]
For banks running both kinds of models, internal data governance is therefore part of how controls for generative AI get defined. Lineage, dataset versions, quality results, and approval records captured as they occur provide the documentation both regimes expect.
How to Roll Out an AI Data Governance Framework in Four Steps
- Start with funded AI use cases: Govern the data those use cases touch first, so controls and business value arrive together.
- Classify and catalog that data: Assign owners, sensitivity levels, and training eligibility before access requests begin to queue.
- Publish the fast-track path: Set default approval rules, SLAs, and the exception route before widening scope.
- Automate, then extend: Embed quality, lineage, and access checks in pipelines, then add data domains as new use cases are approved.
How Intuceo Builds AI Data Governance Into Delivery
Intuceo designs AI data governance programs alongside the use cases they protect. Engagements cover data cataloguing and lineage, automated PII and PHI scanning, compliance monitoring, and consent management, delivered through an operating model that defaults to approval for well-defined requests and routes exceptions to an SLA-bound governance board.
PhD-led teams apply this structure through Intuceo’s iPDLC™ delivery methodology, so data controls are defined during each project and are in place before a model reaches production. If governance reviews are holding back models that are otherwise ready, an assessment of your current approval flow and data controls can show where clearer decision rights and automation can shorten the path to production.
Frequently Asked Questions
1.How do I build a data governance framework without slowing down AI delivery?
Scope the first phase to the data your active AI use cases need, publish default approval rules with SLAs, and reserve committee review for personal, restricted, or novel uses. Measure request turnaround from the first week, so that slow steps can be identified and fixed individually instead of being attributed to governance as a whole.
2.What are the essential components of enterprise AI data governance?
Ownership and decision rights, a catalog enriched with AI context, automated quality rules, lineage through to model outputs, privacy and consent controls, and an AI-specific usage policy. The usage policy deserves early attention because it answers a question reporting-oriented programs were not designed to ask: whether data collected to deliver a service may also be used to train a model.
3.How does data governance differ for AI workloads vs. traditional BI?
BI governance protects curated tables and reports that a person reviews before acting. AI governance also covers training datasets, features, prompts, and outputs that may drive automated decisions, and it adds representativeness as a quality criterion. Unstructured content raises a further difference: documents used to ground generative AI responses need classification and access control at the document level, so that a retrieval step cannot surface content the requesting user is not permitted to see.
4.What is the role of a data steward in an AI-first organization?
Stewards certify datasets for specific model uses, maintain AI-relevant metadata, triage quality alerts, and resolve routine access requests within the owner’s rules. Judging representativeness and labeling quality requires some familiarity with model development, so pairing each domain steward with a named contact in the AI delivery team that consumes the domain’s data gives both sides a direct line for resolving issues.
5.What is the difference between AI data governance and AI governance?
AI data governance controls the data that trains, grounds, and feeds AI models: who owns it, whether it may be used, and whether it is fit for purpose. AI governance is broader. It adds model approval, performance monitoring, explainability, and accountability for outputs. A complete program needs both, with separate owners.
6.Which frameworks can an AI data governance program build on?
Most programs start from DAMA-DMBOK for core data disciplines. They then map AI-specific risk to the NIST AI Risk Management Framework, whose four functions are Govern, Map, Measure, and Manage. Organizations that want a certifiable management system can add ISO/IEC 42001, the international standard for AI management systems.