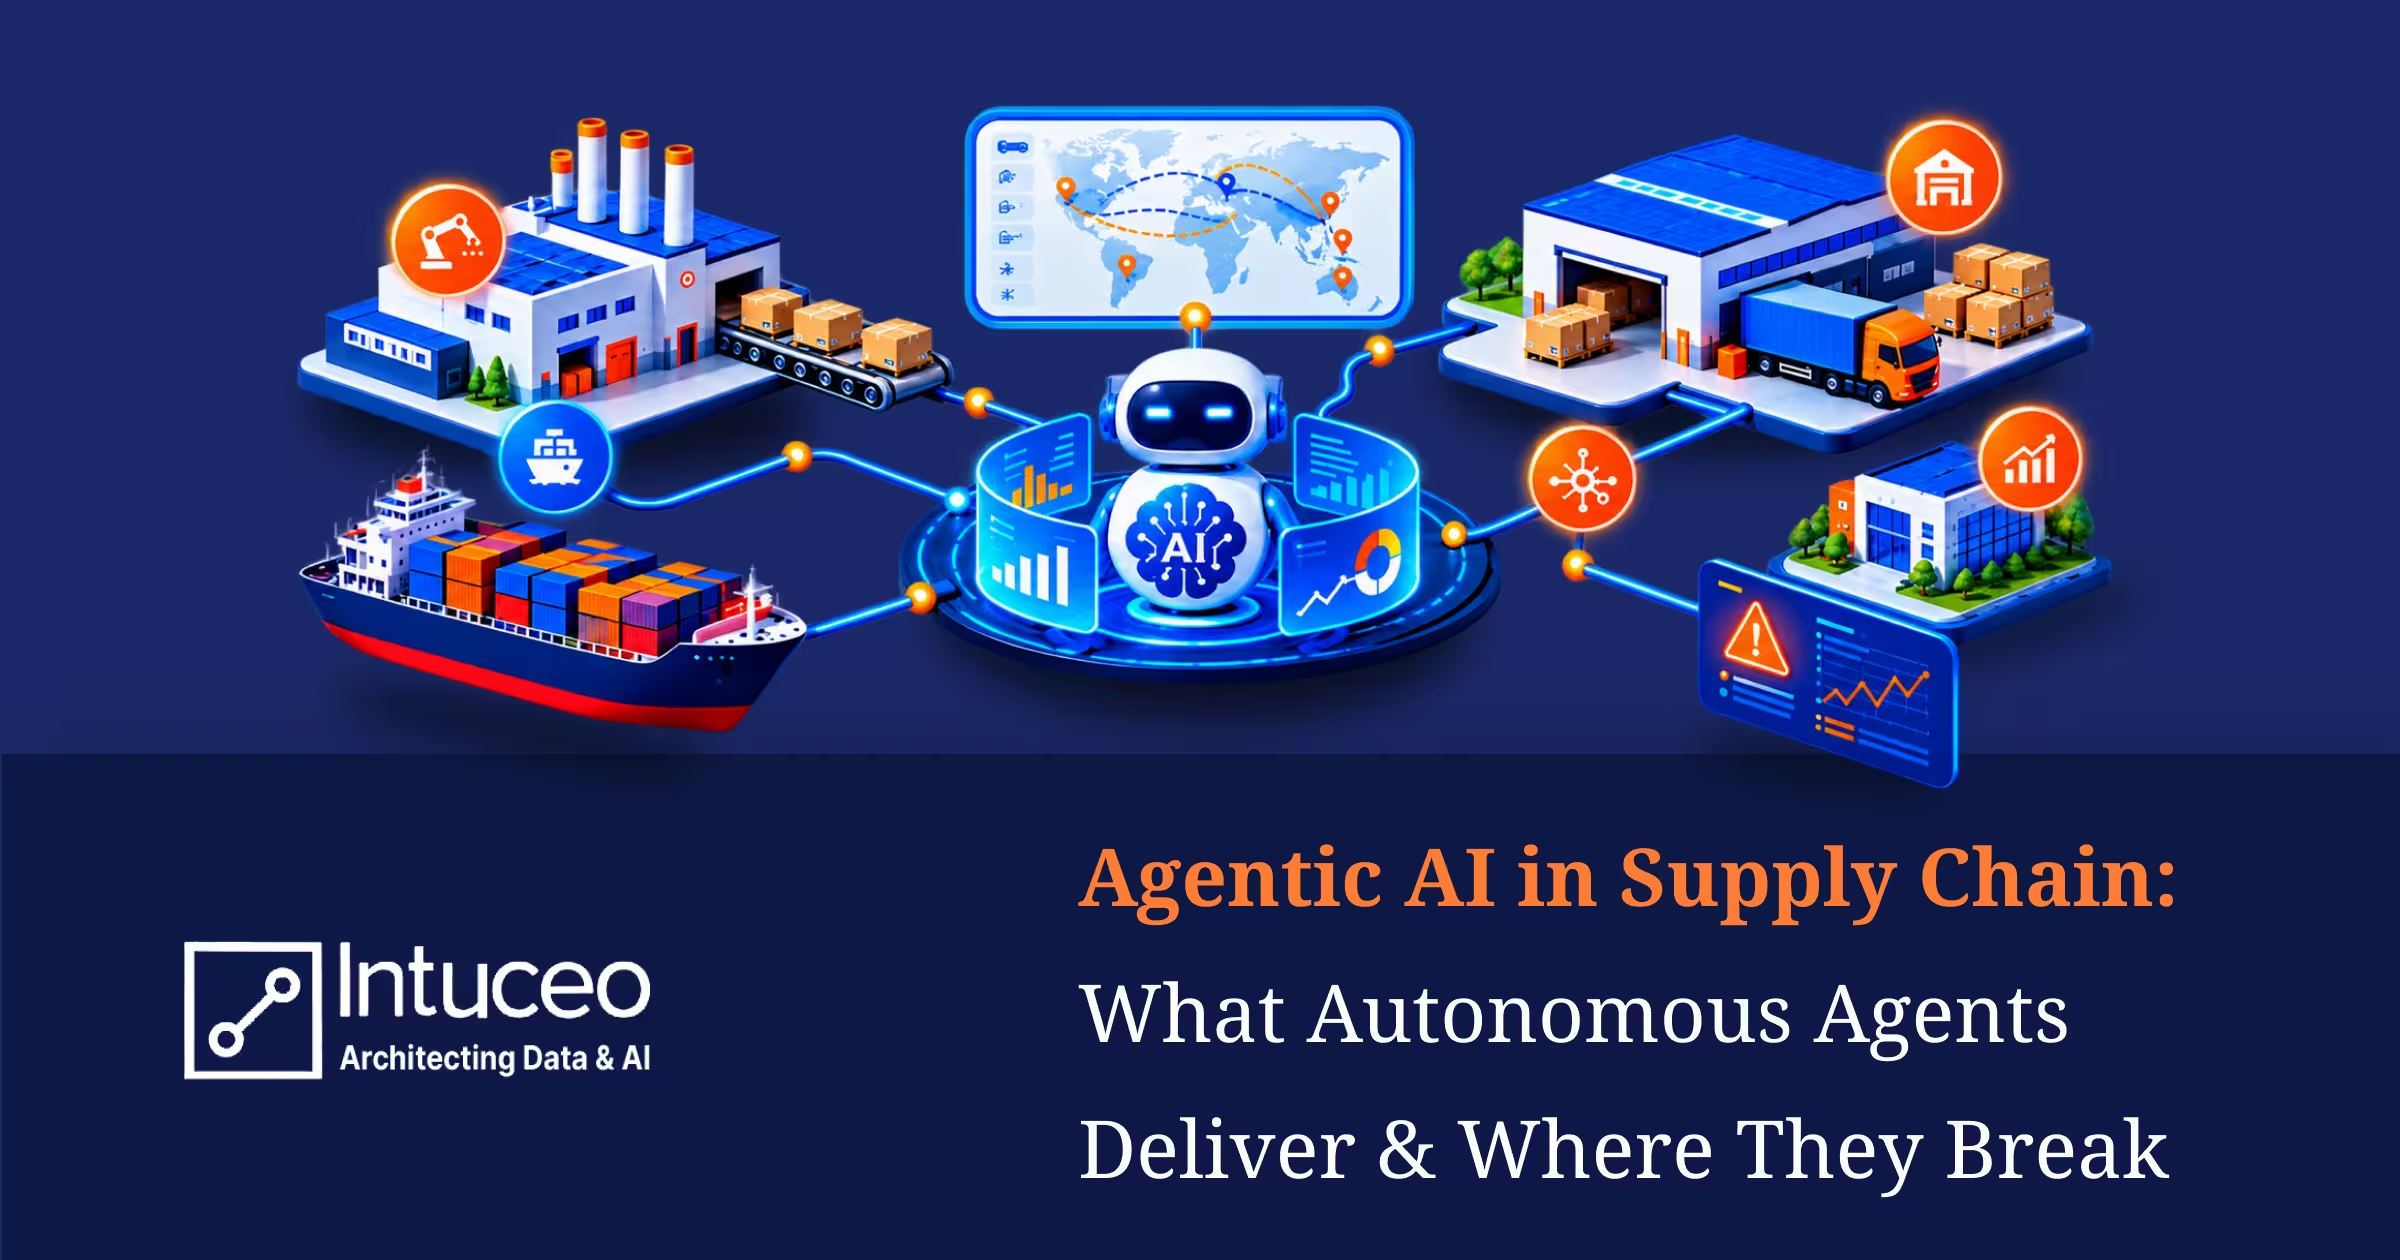
Agentic artificial intelligence (AI) in supply chain has moved quickly from vendor roadmaps into software selection criteria. Gartner reports that AI agents are now a common requirement when enterprises select supply chain management (SCM) software, and predicts that 60% of enterprises using SCM software will have adopted agentic AI features by 2030, up from 5% in 2025. The same analysis expects enterprise deployments to trail vendor availability, because data management, operations management, and workforce readiness have not kept pace with the technology.1
That gap decides whether an agentic AI supply chain program produces measurable results or stalls after the pilot. For operations and technology leaders, the useful question is narrower than whether to adopt AI agents in supply chain operations. It is which decisions an agent can be trusted to make, under what conditions, and how the organization will know when the agent is wrong.
Key Takeaways
- Where it works today: Agentic AI in supply chain delivers on high-volume, rule-bound, reversible decisions such as exception triage, replenishment parameters and freight audit.
- Where it breaks: Failures cluster in five areas: commercial trade-offs, inconsistency at volume, multi-agent coordination, stale data and agent washing.
- How to set autonomy: Assign it per decision class across four tiers: execute, execute and notify, recommend, and escalate.
- How to measure ROI: Track touchless rate, override rate, time to resolution, cost per exception and consistency for each decision class.
What Is Agentic AI in Supply Chain Operations?
Agentic AI in supply chain operations refers to AI agents that execute defined decisions, such as re-tendering a load or adjusting a reorder point, within limits the business sets, rather than only recommending them.
Most supply chain teams already work with some form of AI assistance.
Copilots, the conversational assistants now built into many planning and transportation tools, interpret data, summarize options, and recommend a course of action, and a person then carries it out.
An agentic system goes a step further. It observes an operational state, selects an action against a defined goal, executes that action through connected systems, and checks the result. That added step determines who is accountable, how failures surface, and which controls a buyer needs.
Copilot vs. Agentic AI in Supply Chain: Key Differences
| Dimension | Copilot | Agentic system |
|---|---|---|
| Who acts | A planner, after reviewing a recommendation | The agent, within delegated limits |
| Typical scope | Queries, summaries and scenario comparisons | Multi-step workflows across transportation, warehouse and enterprise systems |
| Primary risk | Poor advice that a reviewer may catch | An incorrect action written into a system of record |
| Controls required | Output review | Thresholds, audit trails, rollback and escalation paths |
Gartner observes that most agentic features now offered in supply chain planning improve the user experience through query interpretation, recommendations and conversational support, without materially changing decision quality or how decisions are made.2 While this is useful, it carries different economics from delegated execution, and buyers should price it accordingly.
Which Agentic AI Supply Chain Use Cases Deliver Value Today?
The defensible answer to how agentic AI is used in supply chain operations today is narrow: in high-volume decisions with clear rules, measurable outcomes, and a low cost of error. Gartner cites touchless forecasting for stable stock-keeping units (SKUs) and automated changes to replenishment parameters as examples of that profile.2
The strongest agentic AI supply chain use cases for enterprise operations share that shape.
- Transportation exception triage: When an estimated time of arrival (ETA) slips, or a carrier rejects a tender, an agent can classify the exception, pull shipment and contract context, and execute a predefined response such as re-tendering to the next carrier in the routing guide. Planners receive only the cases that fall outside policy.
- Replenishment parameter maintenance: Agents can adjust safety stock and reorder points for stable, well-forecast items within approved bands, enabling planners to concentrate on volatile, seasonal, and newly launched items.
- Procurement follow-through: The strongest agentic AI procurement applications are operational. They include chasing purchase order (PO) confirmations, reconciling acknowledged delivery dates against requested dates, and requesting quotes for catalog or tail-spend items below an approval threshold.
- Freight audit and settlement: Matching carrier invoices against contracted rates, accessorial rules, and proof of delivery is repetitive, rule-bound, and easy to verify, which makes it well-suited to agent execution and one of the fastest supply chain AI returns to prove.
- Carrier and appointment coordination: Scheduling dock appointments and answering routine status requests through electronic data interchange (EDI) or email removes a large volume of low-value coordination work from planners.
Each of these decisions can be checked against a clear rule and corrected quickly if the agent makes a mistake. Reversibility is what makes them a credible first tier for agentic AI in logistics.
Where Does Agentic AI in Supply Chain Break Down?
The risks of deploying AI agents in logistics seldom appear in a controlled demonstration. They emerge under volume, variation, and competing objectives, and they tend to fall into five patterns.
Trade-offs that depend on commercial judgment
Gartner identifies cross-enterprise negotiation, dynamic cost trade-offs, and ethical judgment as poor candidates for agentic AI before 2027.2 Whether to pay for premium freight to protect a strategic account, or accept a late delivery to protect margin, depends on relationship context and commercial priorities that rarely exist in structured data.
Inconsistency across repeated runs
Single-run accuracy overstates readiness for production. The authors of τ-bench, a peer-reviewed benchmark that tests tool-using agents against written business policies, measured how often an agent succeeds on every one of several attempts at the same task. At publication, the strongest function-calling agent tested succeeded on fewer than half of all tasks, and its success rate on eight consecutive attempts fell below 25% in the retail scenarios.3
Models have improved since, but the measurement principle holds. An operation that processes the same exception type thousands of times a week needs evidence of consistency, because small error rates compound at that volume.
Coordination failures between agents
Multi-agent systems in supply chain designs typically assign separate agents to demand, inventory, transportation, and procurement, then rely on them to coordinate. Research led by the University of California, Berkeley, which analyzed more than 1,600 annotated execution traces across seven multi-agent frameworks, identified 14 failure modes grouped into system design issues, inter-agent misalignment, and task verification.4
These categories translate directly into supply chain terms. An inventory agent holds stock to protect service levels while a transportation agent consolidates loads to reduce cost, and neither asks which objective takes precedence. A workflow closes an exception without confirming that the carrier actually accepted the re-tender. Both failures originate in design choices about roles, hand-offs and verification, so model upgrades alone will not resolve them.
Stale or inconsistent data
An agent acts with the same confidence whether its ETA feed is current or six hours old, and whether units of measure agree between the enterprise resource planning (ERP) system and the warehouse management system. Experienced planners often sense when data looks wrong. Agents need that sense written in as explicit data-confidence checks, built on governed data pipelines with lineage and freshness monitoring, that pause execution and escalate.
Agent washing: capability claims that exceed the software
Gartner warns that agent washing, the relabeling of conventional automation as agentic, raises the risk of misaligned investment and long-term lock-in, and notes that many current offerings cannot independently re-sequence objectives, negotiate trade-offs or adapt execution logic.2
A practical test during evaluation is to ask a vendor to run an exception the system was not configured for and observe what the agent does.
The table below summarizes the five failure patterns, how each one typically shows up, and the control that addresses it.
| Failure pattern | Typical symptom | Control |
|---|---|---|
| Commercial trade-offs | The agent expedites freight without weighing account priority or margin | Keep these decisions at the Recommend tier |
| Inconsistency at volume | The same exception is resolved differently across repeated runs | Test repeated-trial consistency before go-live |
| Multi-agent coordination | Inventory and transportation agents pursue competing objectives | Define objective precedence and verified hand-offs |
| Stale or inconsistent data | Action is taken on an outdated ETA or mismatched units of measure | Add data-confidence checks that pause and escalate |
| Agent washing | A rules engine is sold as agentic | Ask the vendor to run an exception the system was not configured for |
How Do You Set the Decision Boundary for Agentic AI Exception Management?
In agentic AI exception management, autonomy works best as a graded set of permissions assigned to each decision class, with escalation designed as carefully as execution.
| Tier | Agent role | Suitable when |
|---|---|---|
| Execute autonomously | Acts and records the action | Rule-bound, reversible, low financial exposure |
| Execute and notify | Acts, informs the owner, and allows a rollback window | Moderate exposure, clear policy, high volume |
| Recommend | Prepares the action with its rationale for approval | Material cost, customer or supplier impact |
| Escalate | Assembles context and routes the case to the right owner | Policy conflict, low data confidence or an unfamiliar scenario |
Within an AI governance framework, four criteria set the tier: whether the action can be reversed, the financial exposure per decision, the effect on customers or suppliers, and confidence in the underlying data.
Tiers should change with evidence. A decision class earns more autonomy once its override and reversal rates stay stable over a defined period, and it returns to a lower tier when a disruption shifts the conditions it was calibrated for.
How Do You Measure Supply Chain AI ROI at the Decision Level?
Aggregate efficiency claims are difficult to audit. Supply chain AI return on investment (ROI) is easier to defend when it is measured for each decision class against a baseline captured before deployment.
- Touchless rate: The share of cases resolved without human intervention, tracked separately for each exception type.
- Override and reversal rate: How often people change or undo agent actions, which is the clearest signal that autonomy has been set too high.
- Time to resolution: Elapsed time from detection to closure, compared with the manual baseline for the same exception type.
- Cost per resolved exception: Including premium freight, expedite fees and planner time, so that faster resolution is not achieved at higher total cost.
- Consistency: Outcomes for the same exception type across repeated occurrences, applying the repeated-trial view described above.
How Intuceo Builds AI Agents for Transportation Management
Intuceo delivers agentic AI in supply chain operations through its supply chain and transportation practice, beginning with the decision classes a client’s data and policies can support. That practice draws on transportation work for operators including CSX, MTA Long Island Rail Road (LIRR) and National Air Cargo. Its iTMS™ accelerator, an AI transportation management system, places a Supervisor Agent across three modules: iForesee for demand forecasting, iPlan for procurement and execution planning, and iSee and iVerify for multi-modal visibility and delivery verification. The agent monitors all three for bottlenecks, and when it detects a disruption, it simulates alternative routes and presents the options to planners.
Every recommendation from iForesee and iPlan carries a rationalization layer that shows which variables, such as cost, time, carbon, or risk, shaped it. That record gives reviewers the audit trail a graded autonomy model depends on, a core principle of explainable, production-grade AI. iTMS connects to existing ERP systems and carrier networks without replacing them, and Intuceo’s advisory team uses digital twin modeling to simulate the effect on a client’s network before go-live, so autonomy thresholds are tested before they touch live freight. Through Intuceo’s iPDLC™ delivery framework, iTMS deployments typically reach a live pilot with measurable ROI in about 90 days.
Identify which supply chain decisions are ready for autonomy
Intuceo’s Supply Chain Diagnostic maps your exception volumes, data quality and decision rules to a tiered autonomy plan, so the first agents you deploy are the ones most likely to perform reliably in production.
Frequently Asked Questions
1.What does agentic AI actually do in supply chain management?
It executes defined decisions on behalf of planners. In an agentic AI supply chain deployment, agents typically triage transportation exceptions, maintain replenishment parameters for stable items, follow up on purchase order confirmations and reconcile freight invoices. They act within thresholds the organization sets, record each action and escalate cases that fall outside policy or rely on data the agent cannot verify.
2.Where does agentic AI fail in logistics operations?
Failures cluster in five areas: decisions that require commercial judgment, inconsistent results when the same task repeats at volume, poor coordination between multiple agents with competing objectives, actions taken on stale or mismatched data, and vendor claims that present conventional automation as agentic. Most of these are design and governance issues that can be addressed before deployment.
3.How do autonomous AI agents handle exception management in supply chains?
Well-designed agents classify each exception, gather the relevant shipment, order and contract context, and then act according to the autonomy tier assigned to that exception type. Low-risk, reversible cases are resolved directly. Higher-exposure cases are prepared as recommendations for approval, and cases involving policy conflicts or low data confidence are routed to the appropriate owner with context attached.
4.What is the difference between a copilot and an agentic AI system in logistics?
A copilot interprets data and recommends actions, and a person executes them. An agentic system executes actions itself through connected transportation, warehouse and enterprise systems, within delegated limits. The shift moves accountability for individual actions from the planner to the controls around the agent, which is why thresholds, audit trails and rollback paths become mandatory.
5.Is agentic AI ready for supply chain operations today?
For a narrow set of decisions, yes. Agents perform reliably on high-volume, rule-bound and reversible tasks such as exception triage, replenishment parameter updates and freight audit. Decisions that depend on commercial judgment or cross-enterprise negotiation are better kept as recommendations with human approval, a sequence Gartner also advises.
6.How do you measure the ROI of agentic AI in supply chain?
Measure it for each decision class against a pre-deployment baseline. Track touchless rate, override and reversal rate, time to resolution, cost per resolved exception including premium freight, and consistency across repeated occurrences. A rising override rate signals that autonomy has been set too high.