Live AI Dream Session, Vol. 3: Trustworthy AI in Practice with Sarath Kuravi and Dr. Shonraj Ballae • Nov 10 | 11:00 AM EST Reserve Your Seat Claim Free Seat

Reserve Your Seat

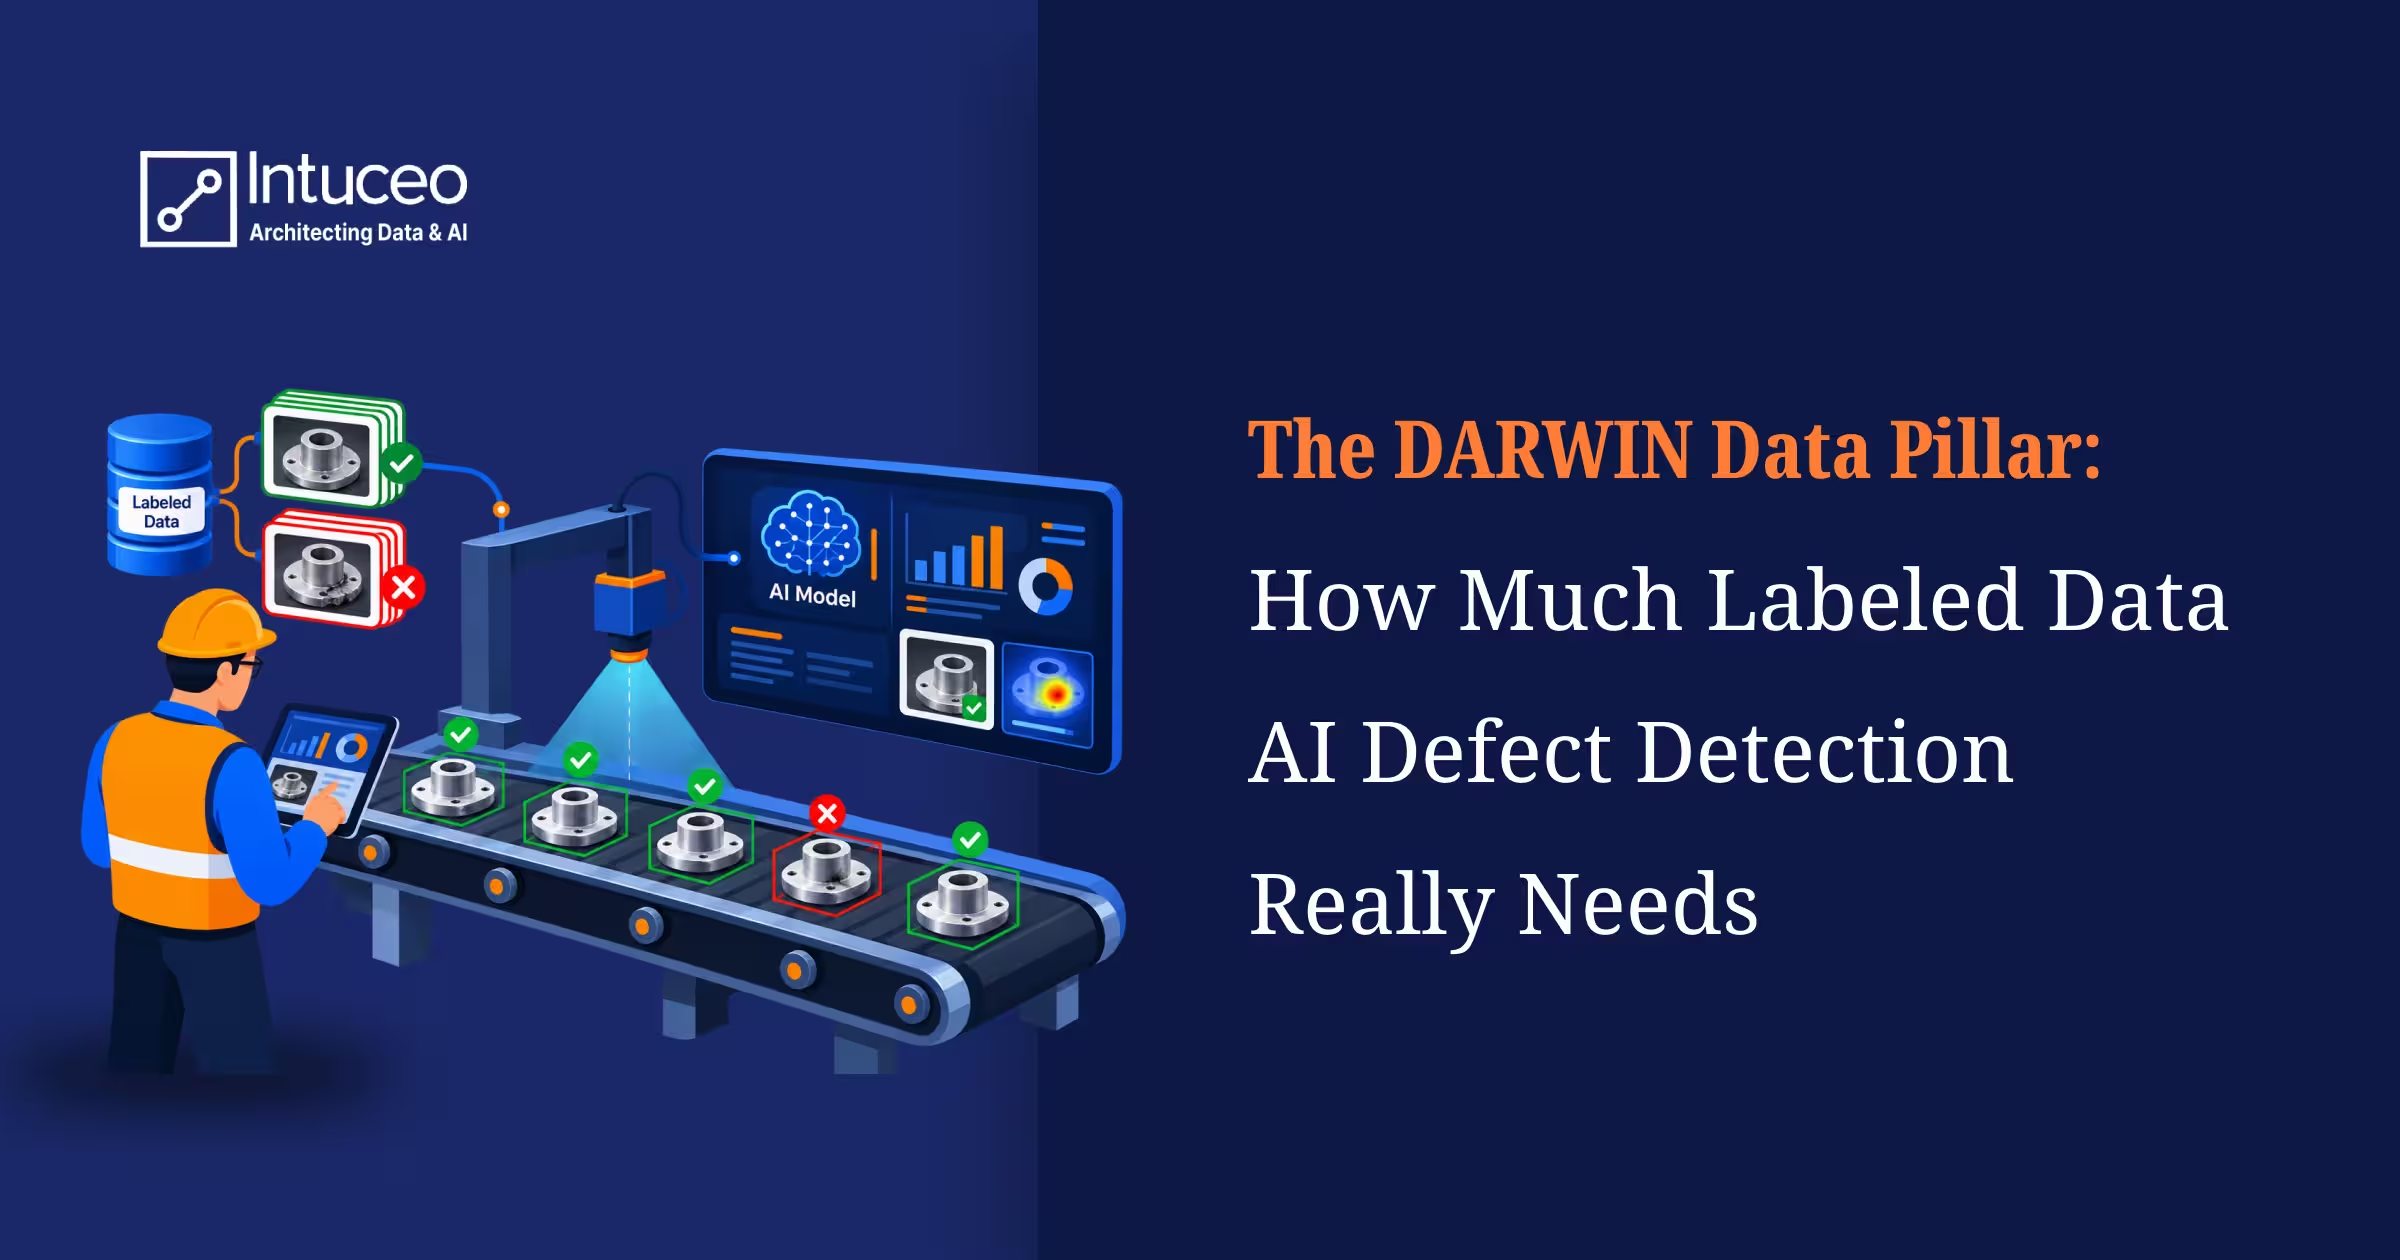
The DARWIN Data Pillar: How Much Labeled Data AI Defect Detection Really Needs

For years, the first question in any vision project was how many labeled images it would take. The answer was usually uncomfortable: thousands per defect class, drawn by people whose time was already committed elsewhere. That single estimate stalled many computer vision inspection projects before they began.
Newer models reduce how much labeled data AI defect detection needs in certain use cases, while other use cases still require the full effort. The Data pillar of the DARWIN™ Framework exists to separate the two before a budget is set.
This article explains how pillar sizes labeled data for AI defect detection within the DARWIN AI framework and what it means for manufacturing teams.

Key Takeaways

What Is the DARWIN™ Framework?

The DARWIN™ Framework is Intuceo AI Labs’ method for judging whether an AI initiative is ready for production across five dimensions: data, architecture, responsibility, workflow, and infrastructure and security. Intuceo AI Labs introduced it to help enterprises evaluate AI initiatives before committing to a build, asking whether each dimension is ready. The goal is a decision that can hold up after the pilot.
AI Dream Session, Vol. 1 set out the strategic question: what does an AI initiative need to move from idea to production? Vol. 2 applies that thinking to computer vision, where data questions tend to dominate.

What Does the DARWIN Data Pillar Ask Before Any Labeling Starts?

The Data pillar reframes the labeled data conversation around four questions.
Answering these before choosing a model prevents a common failure: collecting and labeling a large dataset for a problem that did not need one, or under-investing in a problem that did.

How Much Labeled Data Does AI Defect Detection Need?

Labeled data needs for AI defect detection depend on the decision the model supports. Presence checks and obvious anomalies may need only a small labeled evaluation set. Rare or surface defects can often start from images of good parts. Fine, low-contrast defects with tight tolerances still need substantial labeled examples per defect class.
There is no universal number, and anyone quoting one without seeing images is guessing. Published vendor guidance ranges from a few dozen to several hundred labeled images per defect class, a spread that reflects how differently use cases behave. What has changed is the range of workable starting points.
Broadly, manufacturing vision use cases now fall into three data profiles.
Data profile Typical use cases Labeled data needed
Zero-shot or prompted Part presence, region isolation, counting, obvious anomalies Small evaluation set only, to confirm performance
Few-shot or normal-only Rare defects, new variants, surface anomalies Images of good parts plus a modest labeled evaluation set
Fully supervised Fine, low-contrast defects with tight tolerances and strict acceptance criteria Substantial labeled examples per defect class
The middle row is where much of the change has happened. Research on anomaly detection shows how far performance can go with very little labeled data. WinCLIP, a method built on a vision-language model, reports 91.8% area under the receiver operating characteristic curve (AUROC) for zero-shot anomaly classification on the MVTec AD industrial benchmark, rising to 93.1% for its variant using a single normal image[1].
Treat that as proof of direction, not a promise. On VisA, a second industrial benchmark, the same method scores 78.1% AUROC zero-shot, a reminder that results move with the data[1]. Benchmark images are cleaner and more consistent than most plants. Your results depend on your parts, defects, and imaging conditions.

Why Labeled Data for AI Defect Detection Shrinks but Never Disappears

Labeled data reduction is real. Elimination is not. Even the most data-efficient approach needs labels in three places:
The shift is in proportion. Instead of labeling thousands of training images upfront, teams increasingly treat labeled data for AI defect detection as a smaller, sharper set that proves performance and tracks it over time.

Which Data-Efficient AI Models Reduce Labeling for Defect Detection?

Data-efficient AI models reduce labeling in several ways, each suited to different situations:
Choosing among them is a Data pillar decision because it depends on what data exists, how rare the defects are and how precise the decision must be.

What Makes Training Data for AI Defect Detection Reliable?

When training data for AI defect detection is needed, quality consistently matters more than volume, a pattern we see across AI deployments in advanced manufacturing. A few practical principles apply:

Why Does Data Governance Matter More for Lean Vision Datasets?

Smaller datasets carry less redundancy, so data governance for vision AI matters more, not less. Governance for vision work covers who owns image data, how labels are reviewed and approved, how long images are retained, and how changes on the line trigger revalidation. In regulated environments such as life sciences manufacturing, it also covers traceability and audit readiness.
One caution: a reduced labeling plan without a drift monitoring plan simply moves the risk from build time to run time.

How Do You Know If Your Labeling Plan Is Too Big or Too Small?

The Data pillar also helps teams spot a mismatch between effort and need, and shows where it is safe to reduce labeled data for defect detection. Watch for these signals.

Likely oversized

Likely undersized

Undersized plans tend to show up as disappointing pilots. Oversized plans show up as projects that never start. Both are expensive, which is why the Data pillar treats labeling as a decision to justify rather than a default.

How to Build a Labeled Data Plan for Manufacturing Vision AI in Six Steps

A practical plan for labeled data requirements in manufacturing vision AI starts small and grows with evidence:
1. Inventory archived images, reject records, and existing defect definitions.
2. Match each use case to a data profile: zero-shot, few-shot, or fully supervised.
3. Build a labeled evaluation set first, before any training data.
4. Test the lightest viable approach against that set.
5. Add labeling effort only where results fall short of acceptance criteria.
6. Put monitoring and governance in place before production, not after.
Want a second view on your labeling plan? Scope your vision use case with an AI architect.

How Intuceo supports the data work

Intuceo’s DataOps and engineering team prepares, versions and governs the data that vision models depend on, while Intuceo AI Labs applies the DARWIN™ Framework to decide how much of it a use case genuinely requires. In Intuceo’s lens defect detection work for precision optics, the vision model reduced manual QA workload by up to 30%.

Watch: Computer Vision Reimagined, On Demand

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute session with Intuceo AI Labs on how newer vision models reduce dependence on large labeled datasets, and where they do not. It is now available on demand.

Frequently Asked Questions

The DARWIN™ Framework is Intuceo AI Labs’ method for judging whether an AI initiative is ready for production across five dimensions: data, architecture, responsibility, workflow, and infrastructure and security. It was introduced in AI Dream Session, Vol. 1, and Vol. 2 applies it to computer vision.
It matches each use case to the lightest viable data approach before any labeling begins, then adds effort only where testing against acceptance criteria shows it is needed, rather than committing to a large training set by default.
There is no reliable universal minimum of labeled data for AI defect detection. The one constant is a labeled evaluation set from your own line to validate performance; beyond that, requirements scale with how fine and tightly toleranced the defects are.
Validate against a labeled evaluation set first, then reach for the data-efficient approaches above before committing to full supervision. Keep the hardest examples in the set and monitor for drift so the leaner dataset stays trustworthy.
Often, yes, for rare or surface defects. Normal-only anomaly detection learns from good parts and flags departures. You still need a small labeled evaluation set from your own line to confirm it meets acceptance criteria.
Data Lakehouse Architecture for AI: How to Build an AI-Native Lakehouse for the Enterprise

Enterprise data teams are being asked to deliver two things from one stack: trusted business intelligence for finance and operations, and reliable training data, features, and retrieval context for machine learning and generative AI. The warehouse-plus-lake split that most organizations inherited was never designed to carry both. In practice, that shows up as duplicated data across systems, governance scattered across tools, and compute spend climbing faster than the model teams it is supposed to serve.
An AI-native lakehouse is a data lakehouse architecture for AI that treats machine learning (ML), feature engineering, and large language model (LLM) retrieval as first-class workloads from day one, built on the same storage, catalog, and lineage that serve traditional analytics.
This guide walks through what makes an enterprise data lakehouse architecture AI-native, a reference layering model, the choice between Databricks and Snowflake for enterprise AI, how MLOps on a lakehouse works, and how to migrate without stalling existing reporting.

Key Takeaways

What Is an AI-Native Data Lakehouse?

An AI-native data lakehouse, sometimes called an AI-ready data lakehouse, is a lakehouse built so analytics, model training, feature serving, and LLM retrieval run on one governed copy of data. It stores open table formats such as Delta Lake or Apache Iceberg on object storage and adds vector search, a feature store, and unified catalog governance.

Data Lakehouse vs Data Warehouse: What Makes a Lakehouse AI-Native?

The data lakehouse vs data warehouse comparison usually gets reduced to a cost argument. The bigger difference matters more for AI. A warehouse is built for curated, structured data queried through SQL. A lake accepts everything, but without transactional guarantees or consistent schema, it rarely produces training sets a data scientist could trust twice in a row.
The lakehouse pattern consolidates both using an open table format, Delta Lake, Apache Iceberg, or Apache Hudi, on top of cheap object storage. That gives data teams ACID (atomicity, consistency, isolation, durability) transactions, schema evolution, and time travel against the same files that feed Python notebooks, SQL dashboards, and Spark jobs.
Calling it AI-native adds four things to that foundation:
The table below summarizes how the three architectures compare for AI workloads.
Capability Data warehouse Data lake AI-native lakehouse
Data types Structured All types All types
Transactions ACID None by default ACID through open table formats
ML and GenAI readiness Requires export Raw, often unreliable Native features, vectors, and models
Governance Strong, warehouse-only Fragmented One catalog for data and AI assets
Reproducibility Limited Weak Time travel on training data
Gartner analyst Prasad Pore reports 65% lakehouse adoption among Gartner’s client base, which positions the pattern as the default substrate for new AI workloads rather than a parallel experiment.[1]

Data Lakehouse Architecture for AI: A Six-Layer Reference Model

A workable reference design has six layers. Each has its own failure modes, so each needs its own ownership and controls.

1. Storage Layer: Open Table Formats on Object Storage

Object storage, Amazon S3, Azure Data Lake Storage, or Google Cloud Storage, holding Parquet files under an open table format. Delta Lake and Iceberg are the two formats most enterprise teams converge on. Both give ACID semantics; the choice usually comes down to the compute engine already in play.

2. Catalog and Governance Layer: One Control Plane for Data and AI

Unity Catalog (Databricks’ governance layer), Snowflake Horizon (Snowflake’s governance layer), or an open equivalent such as Apache Polaris (an open Iceberg catalog). This layer carries access control, lineage, and audit for every object the AI stack will touch. Data lakehouse governance decisions made here propagate to features, models, and prompts without re-implementation.

3. Transformation and Quality Layer: The Medallion Pattern

A medallion pattern of Bronze (raw ingest), Silver (cleaned and conformed), and Gold (business-ready) tables, built with Spark, dbt, or SQL. Data quality checks run as pipeline tests, not as a downstream dashboard.

4. Feature and Model Layer: Reproducible Training Data

Feature store, model registry, and experiment tracking. MLflow is the open reference. Features reference the Silver and Gold tables by version, so a training set from last quarter can be rebuilt exactly.

5. Serving and Retrieval Layer: RAG, Features, and Agents

Vector indexes for retrieval-augmented generation (RAG), online feature serving for low-latency inference, and model endpoints for both batch and real-time. For agentic AI workloads, this layer also exposes governed data to the Model Context Protocol or equivalent connectors.

6. Observability Layer: Drift, Health, and Cost

Pipeline health, data drift, model performance, and cost telemetry in one view. Without it, the lakehouse quietly degrades into another cost center.

How Do You Build a Data Lakehouse for AI Workloads?

The answer resolves at the catalog and feature layers. Those two carry the governance and reproducibility that separate production AI from disposable prototypes.

When Should You Choose a Big 4 Firm or Large Integrator for AI?

Databricks vs Snowflake for enterprise AI comes down to starting point: Databricks fits engineering- and ML-heavy teams building models and agents on open formats, while Snowflake fits SQL- and BI-heavy teams adding AI to governed analytics.
Databricks is a Spark-native environment with Delta Lake and Unity Catalog at its core. It appeals to organizations with heavy data engineering and ML workloads, deep Python usage, and a preference for notebook-driven development. MLflow, Model Serving, Vector Search, and Agent Bricks sit on the same catalog as the raw tables. For teams building retrieval pipelines, fine-tuned models, or multi-agent systems against proprietary data, this consolidation is the main argument.
Snowflake began as a SQL-first warehouse and extended into the lakehouse pattern through Iceberg table support, Snowpark for Python and ML, Cortex for LLM features, and Horizon for governance. It suits organizations with substantial SQL and BI investment that want to add AI workloads without rebuilding the analytics layer.
Factor Databricks Snowflake
Origin Spark-native lakehouse SQL-first warehouse
Default table format Delta Lake Native tables plus Iceberg
Governance Unity Catalog Horizon
ML and GenAI tooling MLflow, Model Serving, Vector Search, Agent Bricks Snowpark, Cortex
Best fit Heavy data engineering, Python, custom models, agents Heavy SQL and BI investment, AI added to analytics
Delta Lake deserves a note of its own for enterprise AI. As an open table format, Delta Lake runs under both Databricks and increasingly outside it, including through Iceberg interoperability. Time travel, schema enforcement, and change data feed are the properties that make reproducible training sets and auditable model lineage practical rather than aspirational.
The best data lakehouse architecture for AI, in practice, is the one aligned with the organization’s existing skills, cloud footprint, and governance maturity. The decision rarely turns on a feature matrix. It turns on how much of the current stack can carry forward, which is the first thing an Intuceo lakehouse readiness assessment maps.

How Does MLOps Work on a Data Lakehouse?

MLOps on a lakehouse keeps features, training sets, models, and serving endpoints under the same catalog as the source tables that produced them. That matters for three reasons.
First, reproducibility. Time travel on the underlying Delta or Iceberg tables lets a team retrain a model on the exact data version it was first trained on, which is often what regulators and internal audit actually ask for.
Second, lineage. When a model drifts, the engineering team can trace from the serving endpoint back through the feature, the Gold table, the Silver transformation, and the raw Bronze ingest, inside one lineage graph.
Third, governance. Databricks’ 2026 State of AI Agents report, based on telemetry from more than 20,000 organizations, found that companies using AI governance tools put 12 times more AI projects into production than those without.[2] On a lakehouse, that governance is applied once at the catalog layer and inherited by every downstream model, feature, and agent, the principle behind Intuceo’s DARWIN AI governance approach.
For generative AI specifically, the lakehouse also serves as the retrieval substrate for enterprise LLM infrastructure. Vector indexes sit alongside structured tables, so RAG pipelines and agents can combine semantic search with precise filters against the same governed data without copying it into a separate store.

How to Migrate From a Data Warehouse to a Lakehouse Without Breaking Reporting

A full lift-and-shift data warehouse to lakehouse migration rarely succeeds and rarely pays back inside a budget cycle. A workload-first migration does: move the jobs the warehouse handles poorly first, dual-run reporting during cutover, and retire warehouse workloads only once their replacements are proven.
Migrations that follow this pattern deliver AI workloads first, which is what justified the move in the first place, and let BI follow once the lakehouse has proven itself on harder problems.

How Intuceo Builds AI-Native Lakehouses for Regulated Industries

Intuceo designs and builds AI-native lakehouses on Databricks and Snowflake for regulated industries, including healthcare, life sciences, and the federal space, with Unity Catalog or Horizon governance applied from day one and MLflow-based model lineage tied to the underlying Delta or Iceberg tables.
Where Intuceo’s delivery differs from a generic data engineering engagement: a reference medallion design hardened across prior client engagements including Florida Blue, GuideWell Health, UF Health, Janssen Pharma, and Bausch & Lomb; accelerators such as Intuceo-Ax™ for explainable classification workloads and iPDLC™ for faster AI delivery; and a 20-year track record engineering compliant data environments for Fortune 1000 and federal clients.
Get a lakehouse readiness assessment of your current stack and a 90-day plan to serve your highest-value AI workload from a governed foundation.

Frequently Asked Questions

Compliance belongs in the catalog and storage layers, not in each downstream tool. Unity Catalog or Horizon enforces access control, row and column masking, audit logging, and lineage once, and every feature, model, and agent that reads governed tables inherits those controls. For regulated workloads such as HIPAA-compliant healthcare analytics, pair that with pipeline-level de-identification and tokenization of personally identifiable information (PII) and protected health information (PHI) so sensitive fields never reach training sets or vector stores unless an approved use case explicitly requires them. Audit evidence then flows from the catalog itself rather than from a parallel compliance report.
Both open table formats offer ACID guarantees, schema evolution, and time travel on object storage. Iceberg has broader cross-engine support across Snowflake, Trino, Spark, Flink, and DuckDB, which makes it the stronger choice when the compute strategy is multi-vendor or likely to shift. Delta Lake has deeper feature maturity on Databricks-centric stacks, including Change Data Feed, Deletion Vectors, and tighter integration with MLflow and Unity Catalog. Interoperability layers such as Delta UniForm now let teams write in one format and read through the other, which reduces the need to pick permanently on day one.
Lock-in exposure on a lakehouse is lower than on a warehouse because the data sits in open file and table formats on commodity object storage. Keep the storage layer and the chosen table format decoupled from the compute engine, treat the catalog as a governed abstraction rather than a vendor contract, and avoid encoding critical business logic in proprietary stored procedures or notebook-specific features. Portability becomes a design choice rather than a vendor feature. A lakehouse built this way can be read by multiple engines concurrently and migrated to a different compute vendor without moving the underlying data.
Agents need their own identities, scoped credentials, and audit trails distinct from the human users who deploy them. Grant least-privilege access through the catalog so an agent sees only the tables, columns, or rows its task actually requires, and route inference traffic through a gateway that enforces rate limits, prompt filtering, and output guardrails. For sensitive data, prefer a retrieval interface over direct table access: the agent requests information through a governed endpoint and never reads raw rows it has no business touching.
For most AI workloads, yes. A lakehouse stores structured and unstructured data together, adds ACID transactions through open table formats, and lets features, models, and vector indexes share one catalog with the source tables. A warehouse still suits curated SQL reporting, which is why many enterprises dual-run both during migration.
Six layers: object storage with an open table format, a catalog for governance and lineage, a transformation layer using the Bronze/Silver/Gold medallion pattern, a feature and model layer, a serving and retrieval layer for RAG and agents, and an observability layer for drift, pipeline health, and cost.

Florida AI Consulting Landscape 2026: Boutique vs Big 4 Firms Compared

In the Florida AI consulting landscape, the choice comes down to the shape of the work. Big 4 firms and large integrators such as Accenture fit broad, multi-function programs that need scale, adjacent services, and brand assurance. Boutique AI consulting firms fit defined, technically hard problems where senior specialists, speed, and lower overhead decide whether the model reaches production.
A Florida enterprise with a real artificial intelligence (AI) problem to solve (a claims model headed for production, a demand forecast that has to hold under pressure, a clinical dataset that has to stay compliant) usually puts the same brief in front of two very different kinds of firms. One is a global advisory house or system integrator with thousands of consultants. The other is a specialist shop built around a narrow band of AI and data work. Both will say yes, and that split defines the Florida AI consulting landscape in 2026.
Only one is the right fit for a given situation, and the cost of choosing wrong is real. By some estimates, more than 80% of AI projects fail, twice the failure rate of technology projects that do not involve AI. [1] Any serious comparison of AI consulting firms in Florida starts by separating what each model is built to do from how each one sells.

Key Takeaways

Who Competes in the Florida AI Consulting Landscape?

A shortlist in the AI consulting market in Florida tends to draw from two brackets. The first is the large global firms: the Big Four advisory houses, Deloitte, PwC, EY, and KPMG, alongside scaled system integrators such as Accenture, which is not one of the Big Four but competes for the same enterprise work. Deloitte staffs an office in downtown Jacksonville, [2] and Accenture runs delivery operations across the state.[3]
The second bracket is the specialist firms: smaller, focused practices that do AI, data engineering, and analytics and little else. When someone asks what the best enterprise AI consulting firms in Florida are, there is no single answer that survives contact with a real project. The firm that is right for a two-year, multi-function transformation is rarely the firm that is right for a hard, well-defined modeling problem. The useful question is which model fits the work in front of you.

Boutique vs Big 4 AI Consulting: How the Two Models Differ

The differences that matter to a buyer are structural. They come from how each type of firm is staffed, priced, and organized, not from marketing.
Decision factor Big 4 firms and large integrators Boutique AI specialists
Scale and surge capacity Deep benches; can staff large, parallel workstreams and multi-country rollouts quickly. Smaller teams; capacity is finite and often booked around a few senior people.
Services beyond AI Strategy, change management, tax, audit, and industry practices under one roof. Concentrated on AI, data, and analytics; other needs are partnered or referred out.
Board and audit assurance A recognized name that satisfies boards, auditors, and risk committees. Credibility rests on named references and demonstrable work rather than brand.
Depth in a specific problem Broad coverage; deep specialists exist but may not be assigned to your account. Built around a narrow set of problems, so the specialists are the firm.
Who does the delivery Partners sell; delivery often runs through junior consultants on a staffing pyramid. Senior data scientists and engineers tend to stay on the work from start to finish.
Speed and flexibility Formal process and heavier governance can slow changes in scope. Shorter decision paths; scope and priorities shift with less friction.
Cost Premium rates reflecting overhead, brand, and bench. Lower overhead usually means lower rates for comparable senior effort.
Local presence and procurement Offices in Florida metros and national contract vehicles. Varies; a Florida-based firm can add local access and state and local contract routes.
Best fit Broad, multi-function programs. Defined, technically hard problems.
A large firm carries advantages a small one cannot replicate, and a specialist carries advantages that scale tends to dilute. The decision turns on the shape of the problem, the constraints around it, and who has to be convinced.

When Should You Choose a Big 4 Firm or Large Integrator for AI?

The large firms earn their premium in specific conditions, including :
For an initiative of that scope, a Deloitte data analytics engagement in Florida or an Accenture AI program in Florida brings coordination, bench depth, and brand assurance that a small firm cannot match. If your problem looks like this, the size is the feature.

When Is a Boutique AI Consulting Firm the Better Fit?

A boutique AI consulting firm is a specialist practice focused on AI, data engineering, and analytics, where the senior people who scope the work also deliver it.
A specialist earns its place when the problem is defined and technically hard, and depth matters more than breadth. That covers a forecasting model that has to improve a real decision, a document-extraction pipeline that has to work on messy inputs, or a clinical data problem that has to stay compliant while it runs.
In those cases, boutique AI consulting firms in Florida tend to win on the factors that decide whether the work reaches production: senior people who stay on the engagement, prices focused on engineering rather than brand, and the freedom to change direction without a change-order cycle. Local access and continuity add to the case, and for public sector or regulated buyers, state and local contract routes can matter as much as capability.

What Does a Boutique AI Consulting Firm in Florida Look Like?

A buyer weighing the specialist route would, for example, look at firms such as Intuceo, a Jacksonville-based data and AI services firm with PhD-led engineering teams, patented automated machine learning (ML) accelerators, and the iPDLC delivery framework it uses to move work from prototype to production. Intuceo reports more than two decades of delivery and over 250 solutions shipped, and it carries procurement access through a State of Florida Department of Management Services term contract and a federal General Services Administration (GSA) Multiple Award Schedule.
When considering a boutique vendor, a buyer should confirm that the firm has the bench to sustain the work and references to prove it has solved the same class of problem before.

How Do You Write an AI Consulting RFP in Florida?

Most AI failures trace back to problem framing, data readiness, domain understanding, and delivery discipline rather than to firm size. [1] A good evaluation tests for those directly. That is the core of how to choose an AI consulting firm: the request for proposal (RFP) and the questions you ask do more work than any vendor list.

What Should an AI Consulting RFP Include?

An AI consulting RFP from a Florida buyer should state the business problem and the outcome you are paying for, not a pre-baked solution. At a minimum, it should specify :
Sound enterprise AI vendor selection in Florida rests on scoring every proposal against the same criteria. That is how to evaluate AI consulting proposals on merit rather than reputation.

What Questions Should You Ask an AI Consulting Firm Before Signing?

Before signing, the questions to ask an AI consulting firm are the same regardless of firm size:
If you want a second view before you issue the RFP, define your success metric with our team.

Navigating the Florida AI Consulting Landscape: Size the Firm to the Work

In the Florida AI consulting landscape, sizing the firm to the work is the whole decision. A broad, multi-function program rewards scale, adjacent services, and brand assurance. A defined, technically demanding problem rewards depth, senior attention, and speed. Decide which one you are actually running before you shortlist, and the comparison gets much shorter.
A third route is building an in-house team, which suits AI that is core to your product but takes longer to staff. Many enterprises start with a partner and hand the work to an internal team once the model is in production.

Define the problem before you compare firms

Intuceo runs a scoping session where we help you frame the business problem, test whether your data can support it, and define the success metric your proposals should be measured against.

Frequently Asked Questions

The Florida AI consulting landscape splits into two brackets. Global firms, including the Big Four and large integrators such as Accenture, compete for broad, multi-function programs. Specialist boutiques focused on AI, data engineering, and analytics compete for defined, technically hard problems. The right choice depends on the shape of the work, not the size of the firm.
In boutique vs Big 4 AI consulting, the clearest difference shows up after the contract is signed. At a boutique, the senior people who scoped the work usually deliver it, and pricing is built around a defined problem, so a single well-scoped project can cost a fraction of a large-firm program.
Big Four firms staff from a deeper bench, which lets them run several workstreams at once and absorb scope changes a smaller firm cannot. One practical way to separate them during selection is to ask each to name the individuals who will be on your project and how long they have been with the firm. A boutique can usually name them; a large firm often assigns people later, from whoever is available.
Accenture is strongest when AI has to be wired into large existing systems, when several vendors or business units need coordinating, or when the work spans strategy, build, and ongoing support. That integration capacity is hard to replicate. A specialized firm is strongest on a single, well-bounded problem where you want the senior modelers and engineers on the work rather than a program to manage. The concrete tradeoff: with Accenture you pay for coordination and capacity you may not fully use on a contained problem; with a specialist you get depth and a lower rate, but less room to absorb a program that keeps widening.
State the business problem and the success metric rather than a solution. Specify data ownership and readiness, the seniority of who will staff the work, code and intellectual property ownership, the production and handover plan, Florida compliance requirements such as HIPAA, FISMA, and Section 282.318 where they apply, and an outcome-based pricing model where the work allows it.

HEDIS Care Gap Closure in Florida: How Payers Use AI to Improve Star Ratings

Every open care gap in a Florida health plan carries two costs at once. One is clinical: a member who missed a screening or a chronic-care check. The other is financial: a quality measure that slips below its threshold and pulls down a rating tied to millions in federal payments.
Both costs come due at the same moment. When the measurement year closes, the numbers lock, and the window for HEDIS care gap closure shuts with them. The Healthcare Effectiveness Data and Information Set (HEDIS), maintained by the National Committee for Quality Assurance (NCQA), defines most of those measures. Its results feed the Medicare Advantage (MA) Star Ratings, and those ratings decide quality bonus dollars.
Florida concentrates the problem more than most states. It carries one of the country’s largest Medicare Advantage populations. It runs a Medicaid managed care program that holds plans for their own quality reporting. And its membership spreads across languages and part-year residency. Each trait widens the gap between when care happens and when it gets recorded. Closing that gap is the work analytics does.

Key Takeaways

What Is a HEDIS Care Gap?

A HEDIS care gap is a recommended service, such as a cancer screening or a diabetes check, that a member was eligible for but has no record of receiving during the measurement year. Closing it means delivering that care, or finding and submitting evidence that it already happened, before the year ends. Gaps count against a plan’s quality rates and, through those rates, its Star Ratings.

How Does AI Improve HEDIS Care Gap Closure for Florida Health Plans?

The old approach to gap closure was retrospective. Teams pulled charts near year-end, chased missing records, and confirmed care that had already happened. That model finds gaps too late to close them. It also spends the most effort on the cases with the least to gain.
Using AI for HEDIS care gaps moves the work earlier in the year and narrows it to what will pay off. Four methods do most of the lifting:
Automated reminders then reach members in their own language, which matters across Florida’s diverse membership.

Retrospective vs. AI-Led Care Gap Closure

Dimension Retrospective approach AI-led approach
Timing Year-end chart chase Year-round, starting early in the measurement year
Prioritization All open gaps treated alike Gaps ranked by how likely they are to close
Data used Claims and a sample of charts Claims, clinical notes, lab results, and health information exchange feeds
Outreach Generic reminders Member-specific, in the member’s language
Audit readiness Manual reconstruction Lineage from source to measure

How Does HEDIS Analytics Improve Medicare Advantage Star Ratings?

Star Ratings have grown harder to hold. The Centers for Medicare & Medicaid Services (CMS) recalculates the cut points each year, so a plan can hold steady on clinical performance and still lose a star because the bar moved. In 2026, 207 of 516 rated contracts, roughly 40%, earned four stars or more, down from 261 a year earlier. Only contracts at that level qualify for quality bonus payments.
Ratings draw on about 40 measures. They include cancer screenings, annual flu vaccinations, and whether members with chronic conditions receive recommended services, many of them measures HEDIS defines. [1] CMS’s  final rule for contract year 2027 removes 11 Star Ratings measures starting with the 2029 ratings, which shifts more of the overall score onto HEDIS and member experience measures.
Medicare Advantage Star Ratings analytics earns its place by making that math visible during the year rather than after it. Modeling a plan’s position against likely cut points, a core part of HEDIS and Star Ratings analytics, shows which few measures will swing the overall rating, so quality teams concentrate budget and staff on the gaps that move the number.
For a Florida plan near the four-star line, that focus decides whether it qualifies for a bonus. Member experience scores count too, and they move slowly, which makes early, targeted intervention the only realistic lever inside a rating year. The bonus of a four-star rating earns funds for the extra benefits that keep members enrolled. Analytics that protects the rating protects growth as well. If your contract sits near that line, talk to Intuceo to model your plan against this year’s cut points.

What Does Digital HEDIS Reporting Mean for Florida Health Plans?

For a Northeast Florida operation, inbound automotive and industrial cargo often clears the Port of Jacksonville (JAXPORT). Applying AI to port and yard data aligns berth and gate signals with production demand, so parts arrive against the build schedule instead of piling into buffer stock.
The manual chart chase that many plans still lean on is being retired. NCQA plans to phase out the hybrid reporting method by measurement year 2029. That method combines claims with medical-record review on a sample of members. The goal is fully digital HEDIS reporting by measurement year 2030.[2] NCQA adjusted several measure-level pathways in January 2026 but kept the 2029 endpoint for retiring hybrid reporting.
Measures are moving to Electronic Clinical Data Systems (ECDS) reporting. ECDS draws on data from electronic health records, health information exchanges, and registries, formatted to the Fast Healthcare Interoperability Resources (FHIR) standard. [2]
Once sampling and manual retrieval fall away, rates depend on how cleanly a plan’s clinical data flows into measure logic across the full population. That turns a reporting task into a data task. It hits Florida Medicaid HEDIS reporting, which managed care plans submit to the state, as hard as it hits Medicare Advantage contracts.
AI can automate much of that pipeline. It normalizes incoming data, maps it to measure specifications, flags open gaps, and drafts abstractions for review. The submitted result still passes through the HEDIS Compliance Audit. Getting there means treating supplemental clinical data as a governed asset, not a year-end collection effort. Clear lineage from source to measure lets an auditor trace any rate back to its evidence. Plans that build that lineage now avoid a scramble when the hybrid method retires.

Does Florida Regulate How Health Plans Use AI?

Not through a dedicated statute yet. Florida proposed AI rules for insurers in 2025 and 2026, but none of the insurance-specific bills became law in the 2026 session. Today, NCQA audits and contract terms do most of the governance work.
Florida is drawing lines around AI in insurance while payers adopt it for quality work. In December 2025, Governor Ron DeSantis proposed a Citizen Bill of Rights for Artificial Intelligence. It would bar insurers from using AI as the sole basis to adjust or deny a claim, require them to detail how they use it, and let the Office of Insurance Regulation (OIR) inspect the models to confirm they do not violate fair insurance trade practices. [3]
The Florida House pushed the same line in 2026, passing HB 527 by a vote of 108 to 0 to require a qualified human professional behind every claim denial, but the bill died in the Senate. Other states have pushed similar rules: a qualified person must own coverage denials, and any AI used in utilization review must reflect a member’s individual clinical circumstances.4 Florida’s proposal reaches beyond claims. It would require notice when a consumer interacts with AI, which covers member-facing chatbots and outreach. A companion measure on AI data centers signals how closely the state means to watch the technology’s footprint.
These proposals target adverse coverage decisions. Closing care gaps is a different activity. It finds members who need care and prompts outreach, which the proposals would not restrict. The governance expectation still carries over. Any model that touches a member or a provider should be transparent, explainable, and auditable, with a human owning consequential decisions.
For vendors and enterprises building AI for the Florida market, that changes what a solution has to prove. Documented model behavior, retained audit trails, and human review are becoming conditions of doing business, not features to add later. A plan choosing an analytics approach should assume both OIR scrutiny and an NCQA audit will examine how the models work.

How Should Florida Payers Choose a HEDIS Care Gap Closure Partner?

The best-performing approach to HEDIS care gap closure for Florida health plans is not a single tool. Star and HEDIS results come from three things working together :
In a Florida context, that also means Health Insurance Portability and Accountability Act (HIPAA) aligned handling, explainable models, and experience with the fragmented records a seasonal population creates.
Intuceo supports HEDIS care gap closure for Florida health plans and health systems from its base in Jacksonville. It delivers through reusable accelerators, Intuceo-Ax, Intuceo-Ix, and Intuceo-Dx, together with AgentCare AI, inside its iPDLC delivery approach. The accelerators carry forward patterns from earlier Florida healthcare work, so an engagement does not start from a blank slate. The AI is built to be explainable and auditable, with people in the decision loop.

Frequently Asked Questions

HEDIS is NCQA’s set of standardized quality measures that health plans report. Medicare Star Ratings are CMS’s one-to-five-star scores for Medicare Advantage and Part D contracts, built from about 40 measures, many of them defined by HEDIS. Contracts rated four stars or higher qualify for quality bonus payments.
They use predictive models to rank which member gaps are open and closable now. Natural language processing reads notes, discharge summaries, and scanned results for care that happened but was never coded. Automated, language-aware outreach then reaches the members and providers who can close those gaps before the measurement year ends.
Three kinds of work move ratings. Cut-point modeling shows where a plan stands against this year’s thresholds. Gap prioritization concentrates effort on the measures likely to swing the overall score. Clinical-data integration keeps rates accurate. Because CMS resets cut points every year, the value comes from running this analysis through the year, not after results are final.
Begin with one defect-critical line that already generates inspection images or has cameras in place, so the model has history to learn from. Confirm the data-residency and CUI boundary before choosing where the model will run, then pilot it at the line, so decisions stay on-site and at production speed. Once escape and rework rates improve on that line, extend the approach to adjacent processes.
Yes, if the subcontract involves federal contract information or controlled unclassified information. CMMC requirements flow down to subcontractors at every tier, and any system that processes, stores, or transmits that data, including an AI model and its training pipeline, falls inside the assessment scope.
Yes. Vision and anomaly-detection models can run on edge hardware at the production line or on on-premise servers, so images and sensor data never leave the plant. This is often the default for aerospace and defense work that involves CUI or ITAR-controlled data.

Manufacturing AI in Florida: A Practical Playbook for Aerospace, Defense, and Industrial Manufacturers

Florida holds one of the country’s densest concentrations of precision manufacturing, which makes manufacturing AI in Florida a practical operating decision rather than a future bet. The state is the second-largest aerospace cluster in the United States, with more than 833 aerospace establishments recorded as of 2024. [1] Much of that activity sits in aerospace, defense, and heavy industrial production, where a single escaped defect or an unplanned line stoppage carries consequences most sectors rarely face.
For operators here, the useful question about artificial intelligence (AI) is narrower than much of the market conversation implies: which processes justify it, and under what constraints. A serious approach to AI for aerospace and defense manufacturers begins with understanding that discipline.
Two facts specific to the state shape the answer. Much of the work involves controlled or export-restricted data, which dictates where models and data can physically reside. And most plants sit inside port-based supply chains, so the value of factory-floor intelligence compounds only when it reaches the movement of materials in and out. Both points come after the use cases that consistently repay the investment.

Key Takeaways

Where Does Manufacturing AI in Florida Pay Off First?

What is manufacturing AI? Manufacturing AI is the use of machine learning, computer vision, and natural language processing on production data to detect defects, predict equipment failure, and find the causes of downtime. In Florida’s aerospace and defense plants, it usually runs on-premise or at the production line to meet CMMC and ITAR requirements.
Three categories of work account for most successful AI deployments in advanced manufacturing across aerospace, defense, and industrial plants.

Computer Vision Quality Control at Line Speed

High-frame-rate cameras paired with vision models inspect parts as they move, catching surface flaws, dimensional drift, and contamination that manual checks miss at line speed. In defect-critical production, computer vision inspection shifts quality checks from periodic sampling to continuous coverage.
When the model runs on edge AI hardware at the line rather than in the cloud, the decision stays on-site, and a defective part is pulled in a fraction of a second. For plants where visual inspection ties up skilled labor, the savings are measurable: in Intuceo’s lens defect detection work for precision optics, the vision model reduced manual QA workload by up to 30%.

Predictive Maintenance for Florida Defense Contractors

Vibration, temperature, and acoustic signals from machinery feed predictive maintenance models that estimate remaining useful life (RUL) and forecast failure before it stops a line. For defense contractors running high-value tooling or fleet assets, this converts maintenance from a fixed calendar into a condition-based schedule, which matters most where one asset failure cascades across a program.

Operational Intelligence From Maintenance Logs and Downtime Data

Natural language processing (NLP) applied to technician logs and shift reports surfaces recurring root causes that sensor data alone cannot see, such as procedural drift or environmental factors. Downtime analytics then isolate the sub-processes that quietly erode overall equipment effectiveness (OEE), which is usually where the recoverable margin sits.
The table below summarizes what each use case needs and where it typically runs.
Use case Data it needs Typical deployment under CMMC/ITAR Metric it moves
Computer vision quality control Inspection images, defect labels At the line or on-premise Escape rate, scrap, rework
Predictive maintenance Vibration, temperature, and acoustic data, maintenance history On-premise or FedRAMP Moderate-equivalent cloud Unplanned downtime, maintenance cost
Operational intelligence Technician logs, shift reports, downtime codes On-premise or compliant cloud OEE, repeat failures

How Do CMMC and ITAR Decide Where a Manufacturing AI Model Can Run?

CMMC and ITAR decide where a manufacturing AI model can run, because any system that holds CUI or export-controlled data falls inside the compliance boundary.
Aerospace and defense manufacturers work with two data types that constrain the deployment before any model is built: controlled unclassified information (CUI) such as drawings and specifications, and export-controlled technical data governed by the International Traffic in Arms Regulations (ITAR).
The Cybersecurity Maturity Model Certification (CMMC) program rule took effect on December 16, 2024. It requires defense contractors and subcontractors to safeguard federal contract information (FCI) and CUI, and those requirements flow down through every tier of the supply chain.2
For manufacturing AI in Florida’s defense supply base, the effect is direct. When a vision model trains on part geometry, or a maintenance model ingests telemetry tied to a defense article, the environment holding that data falls inside the assessment boundary.
Cloud services that touch CUI must meet a Federal Risk and Authorization Management Program (FedRAMP) moderate baseline or its equivalent, and export-controlled technical data cannot be shared with foreign persons, in the U.S. or abroad, without export authorization. For many Florida operators, a CMMC-compliant AI deployment therefore means on-premise systems, processing at the line itself, or a sovereign cloud environment rather than a general commercial service.
The flow-down reach matters in this state in particular. Many Florida plants are second- or third-tier suppliers to the primes concentrated on the Space Coast, and a supplier can inherit a certification requirement through its contract without ever selling to the Department of Defense directly. A manufacturing AI program that overlooks that inheritance risks a costly redesign the moment such a clause appears in a contract.
State policy adds a lighter but real layer. Florida has not enacted a broad statute governing private-sector AI use, but its Government Technology Modernization Council, created under section 282.802 of the Florida Statutes, is charged with recommending how the state procures and regulates these systems. [3] For a manufacturer that also sells to state agencies, or that expects federal program scrutiny, the direction favors documentation and explainability that can withstand a procurement review, as covered in our guide to AI compliance for Florida government contractors.
This is where deployments most often go wrong. A team builds a capable model, then discovers only afterward that its data path breaches a flow-down obligation, and the rebuild that follows is expensive. Scoping the compliance boundary first, then deciding where the model will run, avoids that cost. Teams that want a second view before building can map their compliance boundary with our team.
A firm evaluating manufacturing AI consulting partners should weight demonstrated experience operating inside controlled environments, including sovereign, explainable AI deployments.
Intuceo, a Jacksonville-based AI and data analytics services firm, has delivered predictive analytics on federal defense work and builds on-premise systems at the production line and in FedRAMP-aligned cloud environments, which is the relevant qualification when the data cannot leave a controlled boundary. It also holds a State of Florida term contract through the Department of Management Services (DMS), a practical convenience for state-adjacent buyers.

How Does Manufacturing AI Connect to Florida Ports and Freight?

Factory-floor intelligence stops paying off at the plant wall unless it connects to what moves in and out. Aerospace and industrial plants in Florida draw materials through the state’s seaports and feed finished goods into distribution networks, so a production schedule is only as reliable as the inbound parts feeding it. This is where supply chain AI in Florida extends a manufacturing program.
For a Northeast Florida operation, inbound automotive and industrial cargo often clears the Port of Jacksonville (JAXPORT). Applying AI to port and yard data aligns berth and gate signals with production demand, so parts arrive against the build schedule instead of piling into buffer stock.
Transportation analytics applied to outbound freight does the reverse, matching finished-goods dispatch to carrier capacity and lane cost. Inside the warehouse, distribution center analytics govern slotting, replenishment, and labor against real order patterns.
Intuceo connects these through its iTMS intelligent transportation management system, whose supply chain modules link production and demand signals to inbound freight and outbound distribution. Its planning modules forecast demand and position inventory, its execution modules optimize procurement and routing, and its verification modules close the loop on delivery. For a manufacturer, that means production and freight decisions draw on the same data, from the machine to the loading dock.

How Do You Take Manufacturing AI in Florida From Pilot to Production?

Start with one process that already has a measured cost and existing data, set the compliance boundary, then pilot on a single line.
The plants that see a return start with a narrow scope. They choose one process where defects or downtime already carry a measured cost and where data is already being captured, because a vision or maintenance model needs history to learn from. Before that, they draw the CUI and export-control boundary, since it decides whether the model runs on-premise, at the production line, or in a compliant cloud, and moving it later is expensive.
Return is measured against the metrics operators already track, such as OEE, yield, scrap, and unplanned downtime, rather than model accuracy in isolation. A vision deployment justifies itself when escape rates and rework fall. A maintenance deployment justifies itself when a line stops on schedule rather than unexpectedly.
Intuceo runs these engagements through its iPDLC delivery method, which moves from a scoped pilot to production on a defined path rather than an open-ended research effort, and usually proves value on a single line or asset class before extending to the logistics interface.

Find the first process worth automating

If you run an aerospace, defense, or industrial operation in Florida, the fastest route to a defensible result is to identify one defect-critical or downtime-critical process and scope it against your compliance boundary. Intuceo’s team will map that first use case with you and show what a controlled deployment looks like on your floor.

Frequently Asked Questions

The recurring ones are computer vision for quality control, predictive maintenance built on remaining useful life models, and natural language processing applied to maintenance logs for root-cause and downtime analysis. Because aerospace work involves controlled and export-controlled data, these are typically deployed on-site or in compliant environments, and often extended into inbound and outbound logistics through a supply-chain system such as Intuceo’s iTMS.
Sensors capture vibration, temperature, and acoustic data from high-value tooling or fleet assets, and models estimate remaining useful life to flag failures before they occur. This replaces calendar-based servicing with condition-based maintenance. For defense work, the models and telemetry must run inside a CMMC-compliant environment, since the data can qualify as controlled unclassified information.
Return shows up in the metrics a plant already tracks, such as overall equipment effectiveness, yield, scrap, and unplanned downtime, not in model accuracy alone. The strongest cases start where defects or stoppages already carry a measured cost and where usable data already exists, which shortens the path to a result that operations leaders can verify.
Begin with one defect-critical line that already generates inspection images or has cameras in place, so the model has history to learn from. Confirm the data-residency and CUI boundary before choosing where the model will run, then pilot it at the line, so decisions stay on-site and at production speed. Once escape and rework rates improve on that line, extend the approach to adjacent processes.
Yes, if the subcontract involves federal contract information or controlled unclassified information. CMMC requirements flow down to subcontractors at every tier, and any system that processes, stores, or transmits that data, including an AI model and its training pipeline, falls inside the assessment scope.
Yes. Vision and anomaly-detection models can run on edge hardware at the production line or on on-premise servers, so images and sensor data never leave the plant. This is often the default for aerospace and defense work that involves CUI or ITAR-controlled data.

Edge AI Visual Inspection: Why the Fastest Line Decisions Still Belong to Small Trained Models

Generative AI vision models can describe defects they have never seen, segment parts with a single click, and adapt to new variants without retraining. None of that helps if the answer arrives after the part has already moved to the next station. On a production line, a correct decision that arrives late has the same operational effect as a wrong one.
That is why, in edge AI visual inspection, small trained models still own the decision at the point of action. This is not a verdict against foundation models. It is a question of placement. This article explains where time is actually spent in an inspection decision, why compact models fit the fast path, and how larger models can still add value without sitting in the way.

Key Takeaways

What Is Edge AI Visual Inspection?

Edge AI visual inspection runs a computer vision model on hardware next to the camera, such as an industrial PC or embedded accelerator, to accept, reject, or divert parts without sending images to a remote server. It is built for decisions that must land within a single machine cycle.

How Much Time Does an Inline Inspection Decision Have?

Every inline inspection has a deadline set by physics. A part enters the camera’s field of view, gets imaged, and must be accepted, rejected, or diverted before it reaches the reject mechanism. That window depends on conveyor speed, spacing, and station layout.
Inference is only one slice of that window. The full chain includes:
When engineers discuss edge AI inspection latency, they mean the entire chain. A fast model sitting behind a slow network link still produces a slow decision.

Why Small Trained Models Fit Edge AI Visual Inspection

A small model trained for one inspection task does less work per image by design. It does not carry general knowledge about the world. It carries only what’s needed to separate good parts from bad on a specific station. That narrowness brings practical advantages :
The tradeoff is familiar. A small trained model knows only what it was taught. Change the part, supplier, or defect type, and it may need new examples and retraining.

Why Are Foundation Models Slower for Inline Inspection?

Foundation models earn their flexibility through size. Larger image encoders process more parameters for every frame, and many setups run additional language or decoding steps on top. That work takes compute and time, and the published numbers make the scale of it concrete.
The MobileSAM authors distilled the heavy image encoder of the original Segment Anything Model into a lightweight one. On a single graphics processing unit (GPU), the original encoder took 452 milliseconds per image against 8 milliseconds for the replacement, and the full MobileSAM pipeline runs at roughly 10 milliseconds per image. [1]
Two things follow :

Edge AI vs Cloud AI for Visual Inspection: Which Decisions Go Where?

The edge AI vs cloud AI question for visual inspection usually resolves by decision type rather than preference.
Decision type Best location Timing tolerance
Accept or reject within a machine cycle Edge, next to the station Milliseconds, with no network risk
Diverting a suspect part for review Edge or on-site server A short delay is acceptable
Describing an unusual defect for an engineer On-site server or cloud Seconds are fine
Labeling new images and retraining Cloud or data center No live timing constraint
Trend analysis across shifts and plants Cloud or data center Batch processing suits the task
The pattern is consistent. The closer a decision sits to physical action on the line, the more it belongs at the edge on a compact model. Academic work on edge-cloud co-inference supports the same split, with a small edge model handling routine inputs and a large vision model taking the hard cases. [2]

What Does Real-Time Visual Inspection Mean on a Production Line?

Real-time visual inspection means the decision reliably arrives before the latest moment the line can act on it, on every frame, including the slowest ones. Average inference speed hides variance, and a model that is usually fast but occasionally stalls will pass defective parts on exactly those occasions.
Sub-second defect detection sounds quick, and for offline or sampling checks it often is. On high-speed lines the available window can be a small fraction of a second once capture, transfer, and the reject signal are subtracted, so sub-second is a description rather than a standard. The only meaningful threshold is the one your own station geometry produces.

Where Do Foundation Models Add Value in Manufacturing Inspection?

How Do You Measure the Latency Budget of an Inspection Station?

Before choosing any model, work out how much time the line actually allows. A short exercise with operations and controls engineers usually answers it.
What remains is the real budget for inference. Many teams find it tighter than expected, which is why compact models remain the default for AI visual inspection in manufacturing at the point of action.
For example, if a conveyor moves at 1 meter per second and the reject gate sits 0.3 meters past the camera, the window is 300 milliseconds. Subtract capture, transfer, preprocessing, decision logic, PLC signaling, and a safety margin, and the inference budget may be well under 100 milliseconds. These figures are illustrative, so use your own station measurements.
To see where infrastructure and deployment still set these limits in production, watch the AI Dream Session, Vol. 2 recording.

What Is Model Distillation for Visual Inspection?

Model distillation is a training method that teaches a small model to reproduce a larger model’s outputs on a specific task. For inspection, a foundation model can help create the knowledge while a compact model delivers it at line speed. The small model inherits the teacher’s blind spots and still needs validation on real parts, but distillation remains one of the more practical bridges between flexibility and speed.
A vendor latency figure quoted without its conditions is worth little here. Ask what hardware it was measured on, at what image resolution, and whether it covers the full decision chain or inference alone.

How Intuceo Designs Edge AI Visual Inspection Systems

In every edge AI visual inspection project, Intuceo works backward from the decision deadline. The station geometry and the reject window set the constraint, and the model, hardware, and data flow are chosen to meet it, and not the other way round.
Two parts of that approach matter for latency work. Deployment is infrastructure-agnostic, spanning on-premise, edge, hybrid, and air-gapped environments, so a model can sit where the timing requires rather than where a vendor’s hosting model dictates.
The systems are maintained through production-grade MLOps practices built for regulated settings: containerized serving with shadow deployment and canary rollouts, so a candidate model can be timed against the incumbent on live line data before it is given authority, plus drift monitoring with automated retraining triggers for when parts and conditions move.
That combination is how Intuceo supports real-time defect root cause analysis without impeding the production line. See how this applies across advanced manufacturing and to the DataOps and AI/ML Ops capability  behind it.

Watch : Computer Vision Reimagined, On Demand

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute session with Intuceo AI Labs, now available on demand. It covers how infrastructure and deployment still shape what computer vision can do in production, building on the DARWIN Framework from Vol. 1.

Frequently Asked Questions

It is the use of a compact computer vision model running beside the camera on a production line, so accept, reject, or divert decisions happen locally within the machine cycle, with no network dependency. Larger models can still support slower tasks such as exception review and labeling.
Sometimes, but often not at the point of action on a fast line. Large generative AI vision models perform more computation per image, and many inspection windows are short once image capture, transfer, and the reject signal are included. Lighter distilled derivatives are closing the gap, so the answer depends on measuring worst-case timing on your own hardware at production resolution.
Use a small trained model when the decision must happen within a machine cycle, the defect list is stable, image volumes are high, and the system must keep running without a network. Foundation models suit slower tasks such as exception review, labeling, handling new variants, and offline analysis.
Edge deployment removes network delay and dependency but limits how much compute is available, which favors compact models. Foundation models can run on larger on-site servers or in the cloud, gaining flexibility but adding transfer time and more computation per image. Many plants place fast accept-or-reject decisions at the edge and route uncertain cases to larger models.
Generative AI is more flexible, not universally better. On a fixed inspection task, the qualities that decide deployment are speed, timing consistency, cost per image, and how straightforward the model is to validate for an auditor. Recognizing unfamiliar objects matters less at the point of action than meeting the deadline every time. The strongest systems combine both.
Measure the travel time between the camera and the reject point, then subtract capture, transfer, preprocessing, decision logic, and PLC delays, and keep a safety margin. What remains is the inference budget, which should be tested against worst-case timing rather than averages.

Supply Chain AI in Florida: How Ports, Logistics Hubs, and Transportation Leaders Are Cutting Lead Times

The 2026-2030 Florida Seaport Mission Plan, published by the Florida Seaport Transportation and Economic Development Council, directs investment toward dock rehabilitation, capacity expansion, cargo container handling and connectivity across the state’s publicly owned seaports. Physical throughput is being funded. The sequencing logic above it is not being funded at the same pace, and that is where most delay now accumulates.
For anyone evaluating supply chain AI in Florida, the starting point is this: lead time in a freight network rarely disappears at one point. It leaks across handoffs: vessel to yard, yard to gate, gate to drayage, drayage to distribution center, distribution center to customer.
Each handoff carries its own system of record, reporting cadence, and definition of an exception. By the time a planner identifies the problem, the cost is booked. That gap is what Florida operators are now adopting AI to close.

Key Takeaways

Where does lead time leak in Florida freight networks, and how do you measure it?

The Bureau of Transportation Statistics runs the Port Performance Freight Statistics Program, which publishes nationally consistent measures of capacity and throughput for United States seaports, including containership and tanker berthing times updated weekly. [2] It gives operators an external reference point for berth performance.
To measure lead-time leakage before modeling, timestamp each handoff, calculate the median and 90th percentile wait at each one, and rank handoffs by the cost of delay.
Mechanization raises the ceiling. PortMiami has been expanding the fleet of electric rubber-tired gantry cranes at its South Florida Container Terminal, allowing higher container stacking and shorter runs within the yard.
More cranes increase how many moves are possible in an hour. Whether those moves happen in the right order, against the right truck appointments, is a different question that AI for Florida ports is positioned to answer.
Dwell time, the time a container sits in the terminal between discharge and pickup, falls when three things line up: the yard knows which container is wanted next, the gate knows which truck is arriving to collect it, and the carrier knows before arrival whether the slot still holds. Each of those is an AI prediction problem sitting on data that already exists in terminal operating systems, electronic data interchange feeds, and telematics streams.

How does Florida's 2026 data center law (SB 484) affect supply chain AI?

Florida enacted CS/CS/SB 484 as Chapter 2026-65, with most provisions effective July 1, 2026. [4] The law requires the Public Service Commission to implement tariff and service requirements ensuring that large load customers such as large data centers pay their own cost of service, with the risk of nonpayment kept off the general body of ratepayers.
Utilities were required to file conforming tariffs for approval by October 1, 2026. The law also bars any tariff, contract, or utility policy from preventing or hindering curtailment of service to a large load customer when it is necessary to maintain grid stability or protect public safety during emergencies, and prohibits service to large load facilities owned or controlled by foreign countries of concern. [5]
Two consequences follow for anyone deploying Florida logistics AI.
Provision What it means for AI buyers
Large load customers, such as large data centers, must pay their own cost of service. Inference becomes a priced, visible operating line rather than an assumption. Designs that call a large model for every event will carry a different cost profile in Florida than they did in a vendor demonstration.
Tariffs and contracts cannot prevent curtailment of service to large loads during grid emergencies. Compute hosted in-state is explicitly interruptible during grid emergencies. Grid emergencies in Florida cluster in storm season, precisely when routing, diversion and inventory decisions carry the most value.
A decision layer that stops working when the weather turns is worse than no decision layer, because operators will have stopped maintaining the manual process it replaced.
Design implication: keep the models that must survive a disruption small, local and deterministic in their fallback. Reserve heavier reasoning for planning cycles that can tolerate a pause.

Does Florida regulate AI? Why procurement contracts carry the governance load

The proposed Artificial Intelligence Bill of Rights was designed to impose conditions on government contracts for AI technology. It cleared the Senate in March 2026 and then died in the House. [6] A second attempt during the April special session cleared the Senate again and died in House subcommittee the following day. [7]
Florida’s port authorities are governmental entities, which puts their AI vendors in the same position as other Florida government contractors. In the absence of a statutory standard, the obligations a buyer wants have to be written into the contract, not inherited from the code.
For Florida buyers of transportation analytics, four contract terms are worth insisting on:
Vendors should read the same signal in reverse. An offering built around accuracy claims alone is harder to defend to a Florida public sector buyer than one built around evidence. Reshaping a service line to lead with explainability, integration commitments, and exit terms is now a commercial advantage rather than a compliance overhead.

Where should supply chain AI in Florida start? Four decisions to automate first

Most Florida operators do not need a network-wide program. They need to get four decisions right :

Demand and inventory positioning

Forecasting that harmonizes historical movement with live market signals changes where stock sits before the order arrives. This is the core of Florida distribution center analytics: fewer emergency freight bookings, less inventory held against uncertainty, and replenishment triggered by a signal rather than a calendar.

Procurement and dispatch

Carrier selection, share-of-business allocation and container utilization are optimization problems with clear constraints. Routing intelligence that removes empty running takes cost out without touching headcount or assets.

Multi-modal visibility

Rail, road and sea data arrive in different formats on different clocks. A single reconciled record per shipment is the prerequisite for everything else, and it is usually the hardest part of the build.

Freight audit and billing reconciliation

Invoice and proof-of-delivery matching recovers money that is already owed. It is the fastest route to a defensible return, and it builds the internal credibility needed for the larger work.
Intuceo, a Jacksonville-based enterprise AI consultancy, built its iTMS supply chain accelerator to address these four as connected modules, with supervisory agents monitoring forecasting, planning, and execution.
Across deployments, Intuceo reports a 30% increase in forecasting accuracy and billing reconciliation accelerated by 40%. The accelerator is deployed as a layer over existing enterprise resource planning and electronic data interchange estates rather than a replacement for them, which matters in Florida, where mainframe and legacy carrier integrations remain in daily service.

Why Jacksonville matters for port, rail, and logistics AI

Northeast Florida is where sea, rail and highway freight converge most tightly. The Jacksonville Port Authority (JAXPORT) runs its cargo terminals in the same city as Class I rail headquarters, which puts the handoff between sea and rail inside one metropolitan area.
Conversations about logistics AI in Jacksonville therefore tend to start at the interchange rather than at the berth, because a container that clears the terminal quickly and then waits on a rail slot has not saved anyone a day. Intuceo is headquartered in Jacksonville and has delivered supply chain and transportation work for operators including CSX and the MTA Long Island Rail Road (LIRR). Proximity matters: the data that makes these models work is held by yard supervisors, dispatchers, and billing clerks, and it can be extracted much faster in person than over a call.

How to choose a supply chain AI consulting partner in Florida

Put a number on where your lead time goes

Intuceo’s supply chain diagnostic baselines one lead-time metric in your Florida network, identifies where it leaks across handoffs, and returns a costed plan to close it within 90 days.

Frequently Asked Questions

The applications with the clearest effect are berth and yard sequencing, gate appointment matching, and predicted container availability shared with drayage carriers before they arrive. Each one shortens the interval between a container becoming available and a truck collecting it. Capital investment in yard equipment raises the number of moves that are physically possible; sequencing intelligence determines how many of them are the right moves.
Supply chain AI in Florida is typically bought in one of three forms: modules inside an incumbent transportation management system, standalone visibility services, or accelerator-led engagements from services firms that build on top of existing systems. The third suits operators with substantial legacy integration, since it avoids a migration. Intuceo’s iTMS accelerator sits in that category, covering forecasting, dispatch, multi-modal visibility and freight audit as connected modules.
AI helps Florida distribution centers manage inventory in real time by replacing periodic stock reviews with continuous signals. Demand models informed by inbound vessel schedules, order patterns and carrier performance indicate what should be positioned where, and how much buffer is genuinely required. The practical result is fewer expedited shipments and less capital held against uncertainty, with exceptions surfaced while they can still be acted on.
There is no single best platform; the best fit depends on the systems you already operate. Buyers running modern cloud systems can often extend them. Buyers running mainframe, legacy electronic data interchange or long-standing carrier integrations, which describes much of Florida’s rail and port ecosystem, generally get further with a services-led engagement that layers intelligence over those systems. Evaluate AI consulting partners in Florida on integration record, explainability, time to a measurable result, and their willingness to commit to a defined first metric.
Not as of this writing. Florida has no general AI statute. The proposed Artificial Intelligence Bill of Rights, which would have set conditions on government AI contracts, passed the Senate twice in 2026 but died in the House both times. Buyers, including port authorities, have to write explainability, data residency, and audit requirements into contracts.
Intuceo scopes its supply chain diagnostic to deliver a baseline and costed plan within 90 days, and iTMS deployments typically reach a live pilot with measurable ROI in about 90 days.

Zero-Shot Segmentation in Manufacturing: What It Can and Cannot Do

Segmentation has long been one of the most labor-intensive steps in a vision project. Every defect, component edge, or region of interest had to be outlined by hand, pixel by pixel, often across thousands of images.
Promptable foundation models changed that cost structure, at least in principle. An object can now be pointed at, or described, and a mask returned without task-specific training.
The question for quality and engineering teams is how much of that holds up on a real line. While zero-shot segmentation in manufacturing is useful for a defined set of jobs, it is unsuitable for others. This guide separates the two, explains why, and sets out a practical way to test it before anyone commits budget.

Key Takeaways

What zero-shot segmentation means in industrial inspection

Segmentation assigns each pixel in an image to a region: this area is the part, that area is a scratch, the rest is background. Traditional segmentation models learn those regions from hand-drawn masks on the exact task they will perform.
Zero-shot segmentation skips that task-specific training. A foundation model pretrained on a very large, general dataset is prompted at runtime with a point, a bounding box, or, in some setups, a text description, and returns a mask. The best-known example is Meta AI Research’s Segment Anything Model (SAM). Its authors assembled a dataset of over 1 billion masks on 11 million licensed images and trained the model to be promptable so that it transfers zero-shot to new image distributions and tasks.
That scale is the reason the approach generalizes. It is also the reason for caution. None of those images were taken on your line, under your lighting, of your product parts.

Where zero-shot segmentation performs well

The strongest fits share one trait: the region being segmented is visually distinct from its surroundings.
In each case, the model performs localization. It reports where something is. A separate step decides whether that something is acceptable.

Where zero-shot segmentation is unreliable

The limitations map closely onto the defect types manufacturers care about most.

Fine and low-contrast defects

Hairline cracks, micro-scratches, faint discoloration, and subtle porosity often lack clear edges. The SAM authors state that the model can miss fine structures, sometimes generates small disconnected components, and does not produce boundaries as crisply as more computationally intensive methods.[1] On a production line, a missed hairline crack is not a small error to be overlooked.

Acceptance criteria

A mask is not a verdict. The model can outline a mark on a surface without any sense of whether that mark is cosmetic, within tolerance, or cause for rejection. Acceptance criteria live in your quality system, not in a general-purpose model.

Consistency across imaging conditions

Glare, reflective metal, transparent packaging, and shifting ambient light can change results from one frame to the next. The absence of task-specific training does not reduce a model’s sensitivity to imaging conditions.

Speed at line rate

Large foundation models are computationally heavy. Where a decision must be made inside a single machine cycle, the full model may not keep pace without dedicated hardware or a lighter distilled version.

Zero-shot detection vs. segmentation: which does your inspection need?

The two terms are often blended, and the difference affects system design. Zero-shot detection in industrial inspection draws a box around a candidate and assigns a label. Zero-shot segmentation draws the outline. Detection is usually sufficient for presence, position, and counting, and it costs less to run. Segmentation earns its additional compute when shape, area, or boundary precision matters, such as measuring a coating gap or the extent of a surface defect.
Aspect Zero-shot detection Zero-shot segmentation
Output A box and a label A pixel-level outline (mask)
Best for Presence, position, and counting Shape, area, and boundary precision
Compute cost Lower Higher
Example Confirming a part is present Measuring a coating gap or defect extent
Teams often chain the two. An open-vocabulary detection model locates candidate regions from a text prompt in production, and a segmentation model outlines what sits inside each box.

Where does the Segment Anything Model (SAM) fit in manufacturing workflows?

The roles above differ mainly in how much human judgment sits between the mask and the decision, and that is what should order a SAM manufacturing rollout. Exploratory analysis of archived images carries no line risk, because nothing reaches production. Annotation assistance comes next, because an engineer approves every mask before it becomes training data. Preprocessing follows, since a trained classifier still makes the call on the cropped region.
A fourth role, treating the model as the final accept-or-reject authority, is where most disappointment occurs. It is rarely the right starting point.

How do vision-language models and segmentation models work together?

Foundation models for visual inspection increasingly work as a set rather than alone. A vision-language model can be asked whether an image shows anything unusual and to describe it. A segmentation model then outlines the region it points to. That pattern is behind most current interest in vision-language models for defect detection, particularly for unfamiliar anomalies. It also stacks two sources of uncertainty, so validation on your own images matters more.

How do you test zero-shot segmentation on your production line? 7 steps

A short, structured test answers most questions before a full project starts. Seven steps cover the ground.
  1. Assemble a hard evaluation set: Include your subtle defects, reflective parts, and worst lighting, not only clear examples.
  2. Define success in operational terms: Mask overlap scores are useful, but the decisive question is whether the mask would lead to the right part disposition: accept, rework, or reject.
  3. Compare prompt types: Points, boxes, and text prompts behave differently. Test the one you would actually use in production.
  4. Measure speed on target hardware: Benchmark on the device that would sit near the line, not a research workstation.
  5. Repeat across shifts and variants: Run the same prompts on images from different shifts, operators, lighting states, and a recent part variant, to see whether performance holds without adjustment.
  6. Record how it fails, not only how often: A model that misses in predictable ways is easier to manage than one that fails at random, and a clear list of what it misses is as valuable as an accuracy score.
  7. Check review time and traceability: If reviewing uncertain masks takes longer than manual inspection, the workflow needs redesign. Record model version, prompt, and image for each output so decisions can be audited later, a standard practice in production MLOps pipelines.
If a zero-shot model performs well only after heavy prompt tuning on a handful of images, run the same prompts on a fresh batch before trusting the result. Overfitting prompts is easier than it looks.

When should you move from zero-shot to a fine-tuned model?

Move beyond zero-shot when fine defects dominate, tolerances are tight, or decisions must be made within a machine cycle. Zero-shot segmentation for industrial inspection is often the fastest way to learn whether a computer vision inspection project is tractable, but it is not always the final answer. In those cases, the usual next step is fine-tuning on a modest set of your own images or distilling results into a smaller model.

How Intuceo approaches segmentation work

Intuceo starts with the inspection decision the business needs, then works backward to whether segmentation, detection, or a simpler rule is the right tool. Scope your inspection use case with an AI architect.

Two capabilities carry most of the delivery on vision work. High-fidelity visual inspection applies image segmentation, sub-pixel anomaly detection, and automated feature extraction to sub-millimeter defects, including precision medical optics, where surface anomalies, edge irregularities, and contaminants have to be caught at production speed. Multi-modal vision intelligence brings video, image, and metadata streams together so inspection results arrive alongside line system signals rather than in a separate console.

Deployment is the part that has to survive audit. Intuceo delivers in on-premise, private cloud, and air-gapped environments, driven by PhD-led engineering teams with prior deployments in regulated and high-precision environments. See how this applies across AI-driven advanced manufacturing and to the ML and computer vision capability built for it.

Join AI Dream Session, Vol. 2: Computer Vision Reimagined

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute live session with Intuceo on Thursday, September 24, 2026, at 11:00 AM ET. It covers how newer vision models reduce dependence on large labeled datasets, and where accuracy and production conditions still create hard problems.

Frequently Asked Questions

It is the ability to outline objects or regions in an image using a pretrained foundation model, guided by a prompt such as a point, box, or text description, without training on your specific parts. In inspection, it is most often used to isolate components, extract regions of interest, and speed up labeling, rather than to make final quality decisions on its own.
Not entirely. They can sharply reduce the labeling needed to get started and can pre-label images for engineers to correct. You still need a labeled evaluation set from your own line to confirm performance, and many subtle defect types still benefit from fine-tuning on examples specific to your process.
Four limits dominate: weak performance on fine or low-contrast defects, no built-in understanding of acceptance criteria, sensitivity to glare and lighting changes, and heavy compute requirements for large models.
Yes, in well-chosen roles: annotation assistance, preprocessing that isolates parts or regions, and exploration of archived images. Using them as the sole accept-or-reject authority is riskier.
Not always. Large foundation models are computationally heavy, so decisions inside a single machine cycle may need dedicated hardware or a smaller distilled model.

How to Choose an Advanced Analytics Tool for Life Science Data

Life sciences have a data problem disguised as a data advantage. Genomic sequencing, clinical trials, laboratory instruments, safety databases, and decades of research literature now generate information faster than scientific teams can study it. Researchers projecting data growth to 2025 placed genomics on par with or ahead of astronomy, YouTube, and Twitter among the most demanding sources of big data in the world.[1] Volume is rarely the constraint. Converting it into decisions is.
That gap is why so many research and data leaders are evaluating an advanced analytics tool for life science data. The category promises to automate the slow, manual work of preparing and exploring data so scientists can spend their time on interpretation. The label, though, gets stretched across everything from generic dashboards to specialized research systems, and the wrong choice can stall a program for months. This guide covers what advanced analytics in life sciences actually does, why generic tools struggle with research data, and the criteria that separate a real fit from a demo that looks good and fails in production.

What advanced analytics does for life science data

Advanced analytics applies machine learning and natural language processing to the analytics workflow itself. Rather than an analyst manually cleaning data, building a model, and hand-writing every query, the system profiles and prepares the data, surfaces patterns and anomalies, and lets people ask questions in plain language.
For research data, AI-powered analytics for life science data has to do more than chart tidy numbers. It has to make sense of structured lab results sitting beside free-text clinical notes, genomic files, imaging metadata, and PDF regulatory filings. The tools that hold up combine four things: automated data preparation, machine learning analytics for pattern and outlier detection, natural language processing that pulls meaning from text, and conversational querying that returns answers tied back to their source. Spending reflects the pressure. The life science analytics market is projected to reach $16.33 billion by 2030, with research and development being the fastest-growing segment.[2]

Why generic analytics tools struggle with research data

Most analytics tools were built for clean, columnar business data. Life science data is neither clean nor columnar.
Start with a format. Structured, coded data accounts for only 50 to 70% of the information relevant to a clinical trial, and nearly 80% of healthcare data is unstructured, held in clinical notes, imaging reports, and physician narratives.[3] A tool that reads only clean, structured tables ignores most of the available evidence.
Then scale and fragmentation. A single program can span genomic files, electronic health records, LIMS and PLM systems, trial databases, and patent libraries, each in its own format and silo. Joining them by hand is where weeks disappear.
Finally, regulation. In a GxP environment, an insight is only useful if it can be defended. A tool that cannot show how data moved from source to result, or explain why a model reached a conclusion, will not survive an audit. This is the failure point that generic advanced analytics in life sciences deployments hit most often.

Criteria for choosing an advanced analytics tool for life sciences data

It reads unstructured data, not just tables

The first test is whether the tool can work with the share of data that does not fit a spreadsheet. Look for native handling of clinical text, documents, and imaging metadata, and for natural language processing life science insights that extract findings from research papers and trial records rather than leaving them unread.

It automates data preparation

Data preparation is the slowest part of most analyses. Strong tools deliver data preparation automation for life sciences by profiling sources, flagging quality issues, and standardizing formats before modeling begins. The right level of automation returns scientist hours to science instead of spreadsheet cleanup.

It is genuinely self-service for non-data scientists

Many vendors describe a self-service AI platform for life science teams; far fewer deliver one. The practical question is whether a clinical, regulatory, or commercial lead can reach an answer without writing code or waiting in a queue. Conversational AI for life science data analysis helps here, letting users interrogate data in plain language and receive statistically grounded answers, not just generated text.

It explains itself and proves compliance

For regulated work, explainability is not optional. Every insight needs a verifiable path to its source, and every model decision needs an auditable rationale aligned with 21 CFR Part 11, GxP, and HIPAA. A cloud-based advanced analytics solution that cannot generate that evidence creates compliance risk, no matter how fast it runs. This is also how life science companies ensure data compliance in analytics: by choosing tools where traceability is built in, not bolted on later.

It fits existing pipelines

The tool has to work with what you already run. Before committing, confirm which ML tools integrate with existing life science data pipelines, including your data lake, EHR connections, and current BI surfaces such as Tableau, Qlik, or Spotfire. A tool that forces a full rebuild rarely justifies the disruption.

It supports predictive and prescriptive work

Descriptive reporting tells you what happened. Predictive analytics for the life science industry tells you what is likely next, and prescriptive modeling recommends the next action. Tools that embed forecasting, anomaly detection, and next-best-action into the same workflow move teams from reactive reporting to earlier intervention. Applied to machine learning analytics on healthcare data, that shift is the difference between explaining a missed signal and catching it in time.

How Intuceo approaches life sciences analytics

Intuceo’s PhD-led engineers bring Intuceo-Ax as an accelerator built on previous projects’ expertise, so the capabilities above arrive proven and then get configured to the data, pipelines, and compliance demands of the program in front of them.
DataSharp automates data preparation across structured and unstructured sources. InsightExplorer supports what-if analysis, and HiddenInsights surfaces root causes and patterns that manual review misses. A natural-language layer lets non-technical leaders reach institutional insights in as few as three clicks, with every answer backed by traceable data lineage rather than an unexplained number.
For the unstructured side, Intuceo-Ix builds a unified knowledge layer across research silos, indexing millions of documents spanning LIMS, PLM, clinical trials, FDA filings, and patents so teams find what they need in minutes. Where most models return only a yes or no, Intuceo’s explainable AI frameworks also generate the rationale that GxP review demands.
The distinction that matters for buyers is that Intuceo delivers this as engineering work, not a license to administer on your own. The criteria above get applied to your data and your regulatory context; the engagement model is fixed-bid rather than open-ended, and the controls that regulated research depends on are part of the build.

Before you commit, test it on your most complex datasets.

Most advanced analytics decisions go wrong at the pilot stage, when a tool that demos well stumbles on real clinical text, messy source data, or a single audit question. Intuceo’s engineers can run a sample of your own data against the criteria in this guide and show you where each option holds and where it breaks, before you commit to one.

Frequently Asked Questions

Start with your data, not the demo. Confirm the tool can read unstructured sources such as clinical notes and filings, automate data preparation, explain outputs for audit, and connect to existing pipelines. A tool that scores well on these but looks plain often beats a polished one that only handles clean tables.
Yes, though capability varies widely. The marker of a real self-service approach is whether a scientist or commercial lead can ask a question in plain language and act on a sourced answer without engineering support. Conversational querying and automated data preparation are what make that possible.
By choosing tools that build traceability and explainability into the workflow. Every result should carry a verifiable lineage to its source, and every model decision should produce an auditable rationale aligned with 21 CFR Part 11, GxP, and HIPAA. Compliance added after the fact is far harder to defend.
Yes. Natural language processing converts research papers, trial protocols, and safety reports into structured data that can be analyzed alongside numeric results, surfacing connections that would otherwise stay buried in text.
It automates preparation across structured and unstructured data, surfaces patterns and root causes, and answers plain-language questions with traceable lineage, all under compliance controls suited to regulated research.

How Advanced Analytics Tools Speed Up Exploratory Studies in Pharma

Bringing a new therapeutic from discovery to approval still takes roughly 10 to 15 years and commonly costs more than $1 billion to $2 billion.[1] A large share of that time is spent not on running experiments, but on getting data ready to ask questions of it. Research teams sit on genomic readouts, assay results, electronic lab notebooks, and trial datasets that rarely line up, and the people best equipped to find signal in them spend most of their day cleaning and reshaping files instead. This is where advanced analytics tools for exploratory studies in pharma earn their place: they automate the slow setup, so scientists reach the questions faster.

Key Takeaways

What is advanced analytics, and why does it matter for pharma research?

Advanced analytics combines machine learning, natural language processing, and statistical automation to handle the manual steps inside the analytics workflow: preparing data, finding correlations, building first-pass models, and explaining results. Instead of a scientist hand-coding every query, the system proposes relationships, flags anomalies, and answers questions asked in ordinary language. Advanced analytics represents one well-established approach within this broader category, adding AI-driven suggestion layers on top of traditional BI to surface insights researchers might not have thought to look for.
The reason this matters for pharma analytics is timing. Exploratory studies are open-ended by design, with teams testing many hypotheses against messy, high-dimensional data before committing resources to any path. The slowest part is rarely the science. It is the preparation. Even today, data scientists spend roughly 45% of their working hours simply loading and cleansing data before modelling can start.[2] Advanced analytics for pharma removes much of that overhead, which is one reason AI-driven analytics tools are seeing rapid adoption in regulated research environments.

How do advanced analytics tools accelerate exploratory studies in pharma?

They accelerate early-stage research analytics in four concrete ways, each targeting a step where researchers currently lose hours.
Howdoadvancedanalyticstoolsaccelerateexploratorystudiesinpharma

How does advanced analytics support drug discovery?

In discovery, the bottleneck is narrowing millions of possible compounds and targets to the few worth testing in a lab. Advanced analytics speeds this by modelling compound-target interactions, predicting toxicity, and ranking candidates before any physical synthesis. The tools support AI in drug discovery precisely at the stage where the cost of error is highest: before lab resources are committed.
The early evidence for these methods is encouraging. A 2024 analysis in Drug Discovery Today found that AI-discovered molecules met their Phase 1 clinical endpoints at an 80% to 90% rate, substantially higher than historic industry averages.[3] Predictive analytics for drug discovery does not replace medicinal chemistry. It allows teams to spend their limited lab capacity on the candidates most likely to hold up, which is the practical definition of accelerating an exploratory study.

How does advanced analytics transform clinical trial analysis?

Clinical research carries the steepest risk in the entire pipeline. Across more than 400,000 trial records, researchers estimated the overall probability that a drug program entering trials reaches approval at just 13.8%, roughly one in seven.[4] Most of that attrition is decided by how well teams read their data early.
Advanced analytics improves the read. It helps identify eligible patient cohorts faster by searching across fragmented clinical datasets, surfaces site-level and safety signals as data arrives rather than at scheduled checkpoints, and applies predictive analytics in pharma that flag enrolment or efficacy problems while there is still time to adjust. In this way, advanced analytics tools become a practical form of clinical research decision support, shortening the gap between a problem appearing in the data and a team acting on it. Data integration in pharma is the enabling layer: connecting trial records, EHR extracts, and biomarker feeds into a single, analyzable view is what makes real-time signal detection possible.

Can advanced analytics handle complex biological datasets and stay compliant?

Biological data is high-dimensional, noisy, and often unstructured, which is exactly the profile for which advanced analytics is built. The harder requirement in life sciences analytics is not capability but accountability. A result that cannot be explained or traced has limited value in a regulated submission.
This is the practical test for advanced analytics tools in life sciences research: every automated insight needs a verifiable lineage back to source data, and every model decision used in regulated work needs a rationale a reviewer can audit. Explainable AI, immutable logs, and controls aligned to 21 CFR Part 11, GxP, and HIPAA are what separate a tool that demonstrates well from one that holds up under inspection. Advanced analytics frameworks that layer AI-driven suggestions on top of traceable statistical engines are one path to meeting this standard, provided the explainability layer is built from the start rather than retrofitted.

The Intuceo Approach

Advanced analytics, delivered as a service

Intuceo treats advanced analytics as an engagement, not a piece of software to configure and hand over. A PhD-led team arrives with its proprietary analytics accelerator, Intuceo-Ax, already carrying the patterns and configurations from prior regulated research deployments. Rather than starting from blank infrastructure, the team adapts what has already been proven in pharma and life sciences environments, pairing automated data preparation, what-if exploration, and root-cause analysis with natural-language querying that returns statistically grounded answers, complete with the data lineage behind them. Intuceo-Ax is built on advanced analytics principles, extended with additional ML orchestration layers designed specifically for regulated science.
Underneath sit Intuceo’s patented AutoML engines for forecasting, text analytics, and pattern discovery, automating the most labour-intensive phases of model selection and tuning. For unstructured research knowledge, Intuceo-Ix applies semantic search across millions of indexed documents, from LIMS and clinical trial records to FDA filings and patents, so prior findings can be analysed instead of being buried. Because the work targets regulated science, Intuceo architects explainable AI for tasks such as adverse-event classification, generating the evidence-based rationale that GxP and 21 CFR Part 11 demand.
Delivered through fixed-bid engagements, the focus stays on a measurable outcome: getting research teams from pharma data analysis to decision faster, without compromising compliance.

Where is your exploratory work losing the most time?

If your teams spend more time preparing data than studying it, that is a solvable bottleneck. Intuceo’s PhD-led engineers can map where advanced analytics would compress your exploratory cycle, from discovery through clinical analysis, against your specific compliance requirements.

Frequently Asked Questions

Advanced analytics removes the manual bottlenecks that precede actual research. It profiles and cleans incoming datasets automatically, proposes cross-variable relationships that analysts would otherwise test one at a time, and answers plain-language questions without requiring an SQL query for each. In pharma exploratory work, where teams run many hypotheses in parallel against high-dimensional data, this compression of the preparation phase can return several hours per analyst per day to active science.
Natural language processing converts unstructured sources, including research papers, trial protocols, regulatory documents, and safety reports, into structured data that can be analysed alongside numeric results. This unlocks knowledge that would otherwise sit unread and lets teams cross-reference text and numeric data within a single study. For advanced analytics in life sciences workflows, NLP is often the component that makes prior literature and regulatory history available to current-cycle analysis rather than requiring separate manual searches.
Predictive analytics in pharma shortens the time between a signal appearing in the data and a researcher acting on it. For compound prioritisation, models score candidates by predicted toxicity, target affinity, and likelihood of meeting early-phase endpoints, allowing lab resources to be directed at the candidates with the highest probability of success. For cohort analysis in clinical work, predictive models flag enrolment shortfalls, safety patterns, or weak efficacy signals early enough to adjust a study before resources are committed to a path that is unlikely to succeed.
The ones that pair automation with explainability and traceability. For regulated research, every insight needs a verifiable lineage to its source, and every model decision needs an auditable rationale, with controls aligned to 21 CFR Part 11, GxP, and HIPAA. Speed without that audit trail does not survive inspection. Evaluating any advanced analytics tool for life sciences means testing not just what it can surface, but whether its outputs can be reproduced, traced, and defended under regulatory review.
It cuts costs in two places: the hours scientists spend on manual data preparation, and the resources wasted on candidates that fail late. By returning preparation time to research and ranking candidates by likelihood of success before lab work begins, advanced analytics reduces both the labour and the failed-experiment spend that drives discovery budgets. When AI in drug discovery is applied early in the exploratory cycle, the downstream cost savings compound across every subsequent phase that would otherwise have carried a weak candidate forward.