Live AI Dream Session, Vol. 3: Trustworthy AI in Practice with Sarath Kuravi and Dr. Shonraj Ballae • Nov 10 | 11:00 AM EST Reserve Your Seat Claim Free Seat

Reserve Your Seat

Manufacturing AI in Florida: A Practical Playbook for Aerospace, Defense, and Industrial Manufacturers

Florida holds one of the country’s densest concentrations of precision manufacturing, which makes manufacturing AI in Florida a practical operating decision rather than a future bet. The state is the second-largest aerospace cluster in the United States, with more than 833 aerospace establishments recorded as of 2024. [1] Much of that activity sits in aerospace, defense, and heavy industrial production, where a single escaped defect or an unplanned line stoppage carries consequences most sectors rarely face.
For operators here, the useful question about artificial intelligence (AI) is narrower than much of the market conversation implies: which processes justify it, and under what constraints. A serious approach to AI for aerospace and defense manufacturers begins with understanding that discipline.
Two facts specific to the state shape the answer. Much of the work involves controlled or export-restricted data, which dictates where models and data can physically reside. And most plants sit inside port-based supply chains, so the value of factory-floor intelligence compounds only when it reaches the movement of materials in and out. Both points come after the use cases that consistently repay the investment.

Key Takeaways

Where Does Manufacturing AI in Florida Pay Off First?

What is manufacturing AI? Manufacturing AI is the use of machine learning, computer vision, and natural language processing on production data to detect defects, predict equipment failure, and find the causes of downtime. In Florida’s aerospace and defense plants, it usually runs on-premise or at the production line to meet CMMC and ITAR requirements.
Three categories of work account for most successful AI deployments in advanced manufacturing across aerospace, defense, and industrial plants.

Computer Vision Quality Control at Line Speed

High-frame-rate cameras paired with vision models inspect parts as they move, catching surface flaws, dimensional drift, and contamination that manual checks miss at line speed. In defect-critical production, computer vision inspection shifts quality checks from periodic sampling to continuous coverage.
When the model runs on edge AI hardware at the line rather than in the cloud, the decision stays on-site, and a defective part is pulled in a fraction of a second. For plants where visual inspection ties up skilled labor, the savings are measurable: in Intuceo’s lens defect detection work for precision optics, the vision model reduced manual QA workload by up to 30%.

Predictive Maintenance for Florida Defense Contractors

Vibration, temperature, and acoustic signals from machinery feed predictive maintenance models that estimate remaining useful life (RUL) and forecast failure before it stops a line. For defense contractors running high-value tooling or fleet assets, this converts maintenance from a fixed calendar into a condition-based schedule, which matters most where one asset failure cascades across a program.

Operational Intelligence From Maintenance Logs and Downtime Data

Natural language processing (NLP) applied to technician logs and shift reports surfaces recurring root causes that sensor data alone cannot see, such as procedural drift or environmental factors. Downtime analytics then isolate the sub-processes that quietly erode overall equipment effectiveness (OEE), which is usually where the recoverable margin sits.
The table below summarizes what each use case needs and where it typically runs.
Use case Data it needs Typical deployment under CMMC/ITAR Metric it moves
Computer vision quality control Inspection images, defect labels At the line or on-premise Escape rate, scrap, rework
Predictive maintenance Vibration, temperature, and acoustic data, maintenance history On-premise or FedRAMP Moderate-equivalent cloud Unplanned downtime, maintenance cost
Operational intelligence Technician logs, shift reports, downtime codes On-premise or compliant cloud OEE, repeat failures

How Do CMMC and ITAR Decide Where a Manufacturing AI Model Can Run?

CMMC and ITAR decide where a manufacturing AI model can run, because any system that holds CUI or export-controlled data falls inside the compliance boundary.
Aerospace and defense manufacturers work with two data types that constrain the deployment before any model is built: controlled unclassified information (CUI) such as drawings and specifications, and export-controlled technical data governed by the International Traffic in Arms Regulations (ITAR).
The Cybersecurity Maturity Model Certification (CMMC) program rule took effect on December 16, 2024. It requires defense contractors and subcontractors to safeguard federal contract information (FCI) and CUI, and those requirements flow down through every tier of the supply chain.2
For manufacturing AI in Florida’s defense supply base, the effect is direct. When a vision model trains on part geometry, or a maintenance model ingests telemetry tied to a defense article, the environment holding that data falls inside the assessment boundary.
Cloud services that touch CUI must meet a Federal Risk and Authorization Management Program (FedRAMP) moderate baseline or its equivalent, and export-controlled technical data cannot be shared with foreign persons, in the U.S. or abroad, without export authorization. For many Florida operators, a CMMC-compliant AI deployment therefore means on-premise systems, processing at the line itself, or a sovereign cloud environment rather than a general commercial service.
The flow-down reach matters in this state in particular. Many Florida plants are second- or third-tier suppliers to the primes concentrated on the Space Coast, and a supplier can inherit a certification requirement through its contract without ever selling to the Department of Defense directly. A manufacturing AI program that overlooks that inheritance risks a costly redesign the moment such a clause appears in a contract.
State policy adds a lighter but real layer. Florida has not enacted a broad statute governing private-sector AI use, but its Government Technology Modernization Council, created under section 282.802 of the Florida Statutes, is charged with recommending how the state procures and regulates these systems. [3] For a manufacturer that also sells to state agencies, or that expects federal program scrutiny, the direction favors documentation and explainability that can withstand a procurement review, as covered in our guide to AI compliance for Florida government contractors.
This is where deployments most often go wrong. A team builds a capable model, then discovers only afterward that its data path breaches a flow-down obligation, and the rebuild that follows is expensive. Scoping the compliance boundary first, then deciding where the model will run, avoids that cost. Teams that want a second view before building can map their compliance boundary with our team.
A firm evaluating manufacturing AI consulting partners should weight demonstrated experience operating inside controlled environments, including sovereign, explainable AI deployments.
Intuceo, a Jacksonville-based AI and data analytics services firm, has delivered predictive analytics on federal defense work and builds on-premise systems at the production line and in FedRAMP-aligned cloud environments, which is the relevant qualification when the data cannot leave a controlled boundary. It also holds a State of Florida term contract through the Department of Management Services (DMS), a practical convenience for state-adjacent buyers.

How Does Manufacturing AI Connect to Florida Ports and Freight?

Factory-floor intelligence stops paying off at the plant wall unless it connects to what moves in and out. Aerospace and industrial plants in Florida draw materials through the state’s seaports and feed finished goods into distribution networks, so a production schedule is only as reliable as the inbound parts feeding it. This is where supply chain AI in Florida extends a manufacturing program.
For a Northeast Florida operation, inbound automotive and industrial cargo often clears the Port of Jacksonville (JAXPORT). Applying AI to port and yard data aligns berth and gate signals with production demand, so parts arrive against the build schedule instead of piling into buffer stock.
Transportation analytics applied to outbound freight does the reverse, matching finished-goods dispatch to carrier capacity and lane cost. Inside the warehouse, distribution center analytics govern slotting, replenishment, and labor against real order patterns.
Intuceo connects these through its iTMS intelligent transportation management system, whose supply chain modules link production and demand signals to inbound freight and outbound distribution. Its planning modules forecast demand and position inventory, its execution modules optimize procurement and routing, and its verification modules close the loop on delivery. For a manufacturer, that means production and freight decisions draw on the same data, from the machine to the loading dock.

How Do You Take Manufacturing AI in Florida From Pilot to Production?

Start with one process that already has a measured cost and existing data, set the compliance boundary, then pilot on a single line.
The plants that see a return start with a narrow scope. They choose one process where defects or downtime already carry a measured cost and where data is already being captured, because a vision or maintenance model needs history to learn from. Before that, they draw the CUI and export-control boundary, since it decides whether the model runs on-premise, at the production line, or in a compliant cloud, and moving it later is expensive.
Return is measured against the metrics operators already track, such as OEE, yield, scrap, and unplanned downtime, rather than model accuracy in isolation. A vision deployment justifies itself when escape rates and rework fall. A maintenance deployment justifies itself when a line stops on schedule rather than unexpectedly.
Intuceo runs these engagements through its iPDLC delivery method, which moves from a scoped pilot to production on a defined path rather than an open-ended research effort, and usually proves value on a single line or asset class before extending to the logistics interface.

Find the first process worth automating

If you run an aerospace, defense, or industrial operation in Florida, the fastest route to a defensible result is to identify one defect-critical or downtime-critical process and scope it against your compliance boundary. Intuceo’s team will map that first use case with you and show what a controlled deployment looks like on your floor.

Frequently Asked Questions

The recurring ones are computer vision for quality control, predictive maintenance built on remaining useful life models, and natural language processing applied to maintenance logs for root-cause and downtime analysis. Because aerospace work involves controlled and export-controlled data, these are typically deployed on-site or in compliant environments, and often extended into inbound and outbound logistics through a supply-chain system such as Intuceo’s iTMS.
Sensors capture vibration, temperature, and acoustic data from high-value tooling or fleet assets, and models estimate remaining useful life to flag failures before they occur. This replaces calendar-based servicing with condition-based maintenance. For defense work, the models and telemetry must run inside a CMMC-compliant environment, since the data can qualify as controlled unclassified information.
Return shows up in the metrics a plant already tracks, such as overall equipment effectiveness, yield, scrap, and unplanned downtime, not in model accuracy alone. The strongest cases start where defects or stoppages already carry a measured cost and where usable data already exists, which shortens the path to a result that operations leaders can verify.
Begin with one defect-critical line that already generates inspection images or has cameras in place, so the model has history to learn from. Confirm the data-residency and CUI boundary before choosing where the model will run, then pilot it at the line, so decisions stay on-site and at production speed. Once escape and rework rates improve on that line, extend the approach to adjacent processes.
Yes, if the subcontract involves federal contract information or controlled unclassified information. CMMC requirements flow down to subcontractors at every tier, and any system that processes, stores, or transmits that data, including an AI model and its training pipeline, falls inside the assessment scope.
Yes. Vision and anomaly-detection models can run on edge hardware at the production line or on on-premise servers, so images and sensor data never leave the plant. This is often the default for aerospace and defense work that involves CUI or ITAR-controlled data.
Edge AI Visual Inspection: Why the Fastest Line Decisions Still Belong to Small Trained Models

Generative AI vision models can describe defects they have never seen, segment parts with a single click, and adapt to new variants without retraining. None of that helps if the answer arrives after the part has already moved to the next station. On a production line, a correct decision that arrives late has the same operational effect as a wrong one.
That is why, in edge AI visual inspection, small trained models still own the decision at the point of action. This is not a verdict against foundation models. It is a question of placement. This article explains where time is actually spent in an inspection decision, why compact models fit the fast path, and how larger models can still add value without sitting in the way.

Key Takeaways

What Is Edge AI Visual Inspection?

Edge AI visual inspection runs a computer vision model on hardware next to the camera, such as an industrial PC or embedded accelerator, to accept, reject, or divert parts without sending images to a remote server. It is built for decisions that must land within a single machine cycle.

How Much Time Does an Inline Inspection Decision Have?

Every inline inspection has a deadline set by physics. A part enters the camera’s field of view, gets imaged, and must be accepted, rejected, or diverted before it reaches the reject mechanism. That window depends on conveyor speed, spacing, and station layout.
Inference is only one slice of that window. The full chain includes:
When engineers discuss edge AI inspection latency, they mean the entire chain. A fast model sitting behind a slow network link still produces a slow decision.

Why Small Trained Models Fit Edge AI Visual Inspection

A small model trained for one inspection task does less work per image by design. It does not carry general knowledge about the world. It carries only what’s needed to separate good parts from bad on a specific station. That narrowness brings practical advantages :
The tradeoff is familiar. A small trained model knows only what it was taught. Change the part, supplier, or defect type, and it may need new examples and retraining.

Why Are Foundation Models Slower for Inline Inspection?

Foundation models earn their flexibility through size. Larger image encoders process more parameters for every frame, and many setups run additional language or decoding steps on top. That work takes compute and time, and the published numbers make the scale of it concrete.
The MobileSAM authors distilled the heavy image encoder of the original Segment Anything Model into a lightweight one. On a single graphics processing unit (GPU), the original encoder took 452 milliseconds per image against 8 milliseconds for the replacement, and the full MobileSAM pipeline runs at roughly 10 milliseconds per image. [1]
Two things follow :

Edge AI vs Cloud AI for Visual Inspection: Which Decisions Go Where?

The edge AI vs cloud AI question for visual inspection usually resolves by decision type rather than preference.
Decision type Best location Timing tolerance
Accept or reject within a machine cycle Edge, next to the station Milliseconds, with no network risk
Diverting a suspect part for review Edge or on-site server A short delay is acceptable
Describing an unusual defect for an engineer On-site server or cloud Seconds are fine
Labeling new images and retraining Cloud or data center No live timing constraint
Trend analysis across shifts and plants Cloud or data center Batch processing suits the task
The pattern is consistent. The closer a decision sits to physical action on the line, the more it belongs at the edge on a compact model. Academic work on edge-cloud co-inference supports the same split, with a small edge model handling routine inputs and a large vision model taking the hard cases. [2]

What Does Real-Time Visual Inspection Mean on a Production Line?

Real-time visual inspection means the decision reliably arrives before the latest moment the line can act on it, on every frame, including the slowest ones. Average inference speed hides variance, and a model that is usually fast but occasionally stalls will pass defective parts on exactly those occasions.
Sub-second defect detection sounds quick, and for offline or sampling checks it often is. On high-speed lines the available window can be a small fraction of a second once capture, transfer, and the reject signal are subtracted, so sub-second is a description rather than a standard. The only meaningful threshold is the one your own station geometry produces.

Where Do Foundation Models Add Value in Manufacturing Inspection?

How Do You Measure the Latency Budget of an Inspection Station?

Before choosing any model, work out how much time the line actually allows. A short exercise with operations and controls engineers usually answers it.
What remains is the real budget for inference. Many teams find it tighter than expected, which is why compact models remain the default for AI visual inspection in manufacturing at the point of action.
For example, if a conveyor moves at 1 meter per second and the reject gate sits 0.3 meters past the camera, the window is 300 milliseconds. Subtract capture, transfer, preprocessing, decision logic, PLC signaling, and a safety margin, and the inference budget may be well under 100 milliseconds. These figures are illustrative, so use your own station measurements.
To see where infrastructure and deployment still set these limits in production, watch the AI Dream Session, Vol. 2 recording.

What Is Model Distillation for Visual Inspection?

Model distillation is a training method that teaches a small model to reproduce a larger model’s outputs on a specific task. For inspection, a foundation model can help create the knowledge while a compact model delivers it at line speed. The small model inherits the teacher’s blind spots and still needs validation on real parts, but distillation remains one of the more practical bridges between flexibility and speed.
A vendor latency figure quoted without its conditions is worth little here. Ask what hardware it was measured on, at what image resolution, and whether it covers the full decision chain or inference alone.

How Intuceo Designs Edge AI Visual Inspection Systems

In every edge AI visual inspection project, Intuceo works backward from the decision deadline. The station geometry and the reject window set the constraint, and the model, hardware, and data flow are chosen to meet it, and not the other way round.
Two parts of that approach matter for latency work. Deployment is infrastructure-agnostic, spanning on-premise, edge, hybrid, and air-gapped environments, so a model can sit where the timing requires rather than where a vendor’s hosting model dictates.
The systems are maintained through production-grade MLOps practices built for regulated settings: containerized serving with shadow deployment and canary rollouts, so a candidate model can be timed against the incumbent on live line data before it is given authority, plus drift monitoring with automated retraining triggers for when parts and conditions move.
That combination is how Intuceo supports real-time defect root cause analysis without impeding the production line. See how this applies across advanced manufacturing and to the DataOps and AI/ML Ops capability  behind it.

Watch : Computer Vision Reimagined, On Demand

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute session with Intuceo AI Labs, now available on demand. It covers how infrastructure and deployment still shape what computer vision can do in production, building on the DARWIN Framework from Vol. 1.

Frequently Asked Questions

It is the use of a compact computer vision model running beside the camera on a production line, so accept, reject, or divert decisions happen locally within the machine cycle, with no network dependency. Larger models can still support slower tasks such as exception review and labeling.
Sometimes, but often not at the point of action on a fast line. Large generative AI vision models perform more computation per image, and many inspection windows are short once image capture, transfer, and the reject signal are included. Lighter distilled derivatives are closing the gap, so the answer depends on measuring worst-case timing on your own hardware at production resolution.
Use a small trained model when the decision must happen within a machine cycle, the defect list is stable, image volumes are high, and the system must keep running without a network. Foundation models suit slower tasks such as exception review, labeling, handling new variants, and offline analysis.
Edge deployment removes network delay and dependency but limits how much compute is available, which favors compact models. Foundation models can run on larger on-site servers or in the cloud, gaining flexibility but adding transfer time and more computation per image. Many plants place fast accept-or-reject decisions at the edge and route uncertain cases to larger models.
Generative AI is more flexible, not universally better. On a fixed inspection task, the qualities that decide deployment are speed, timing consistency, cost per image, and how straightforward the model is to validate for an auditor. Recognizing unfamiliar objects matters less at the point of action than meeting the deadline every time. The strongest systems combine both.
Measure the travel time between the camera and the reject point, then subtract capture, transfer, preprocessing, decision logic, and PLC delays, and keep a safety margin. What remains is the inference budget, which should be tested against worst-case timing rather than averages.

Supply Chain AI in Florida: How Ports, Logistics Hubs, and Transportation Leaders Are Cutting Lead Times

The 2026-2030 Florida Seaport Mission Plan, published by the Florida Seaport Transportation and Economic Development Council, directs investment toward dock rehabilitation, capacity expansion, cargo container handling and connectivity across the state’s publicly owned seaports. Physical throughput is being funded. The sequencing logic above it is not being funded at the same pace, and that is where most delay now accumulates.
For anyone evaluating supply chain AI in Florida, the starting point is this: lead time in a freight network rarely disappears at one point. It leaks across handoffs: vessel to yard, yard to gate, gate to drayage, drayage to distribution center, distribution center to customer.
Each handoff carries its own system of record, reporting cadence, and definition of an exception. By the time a planner identifies the problem, the cost is booked. That gap is what Florida operators are now adopting AI to close.

Key Takeaways

Where does lead time leak in Florida freight networks, and how do you measure it?

The Bureau of Transportation Statistics runs the Port Performance Freight Statistics Program, which publishes nationally consistent measures of capacity and throughput for United States seaports, including containership and tanker berthing times updated weekly. [2] It gives operators an external reference point for berth performance.
To measure lead-time leakage before modeling, timestamp each handoff, calculate the median and 90th percentile wait at each one, and rank handoffs by the cost of delay.
Mechanization raises the ceiling. PortMiami has been expanding the fleet of electric rubber-tired gantry cranes at its South Florida Container Terminal, allowing higher container stacking and shorter runs within the yard.
More cranes increase how many moves are possible in an hour. Whether those moves happen in the right order, against the right truck appointments, is a different question that AI for Florida ports is positioned to answer.
Dwell time, the time a container sits in the terminal between discharge and pickup, falls when three things line up: the yard knows which container is wanted next, the gate knows which truck is arriving to collect it, and the carrier knows before arrival whether the slot still holds. Each of those is an AI prediction problem sitting on data that already exists in terminal operating systems, electronic data interchange feeds, and telematics streams.

How does Florida's 2026 data center law (SB 484) affect supply chain AI?

Florida enacted CS/CS/SB 484 as Chapter 2026-65, with most provisions effective July 1, 2026. [4] The law requires the Public Service Commission to implement tariff and service requirements ensuring that large load customers such as large data centers pay their own cost of service, with the risk of nonpayment kept off the general body of ratepayers.
Utilities were required to file conforming tariffs for approval by October 1, 2026. The law also bars any tariff, contract, or utility policy from preventing or hindering curtailment of service to a large load customer when it is necessary to maintain grid stability or protect public safety during emergencies, and prohibits service to large load facilities owned or controlled by foreign countries of concern. [5]
Two consequences follow for anyone deploying Florida logistics AI.
Provision What it means for AI buyers
Large load customers, such as large data centers, must pay their own cost of service. Inference becomes a priced, visible operating line rather than an assumption. Designs that call a large model for every event will carry a different cost profile in Florida than they did in a vendor demonstration.
Tariffs and contracts cannot prevent curtailment of service to large loads during grid emergencies. Compute hosted in-state is explicitly interruptible during grid emergencies. Grid emergencies in Florida cluster in storm season, precisely when routing, diversion and inventory decisions carry the most value.
A decision layer that stops working when the weather turns is worse than no decision layer, because operators will have stopped maintaining the manual process it replaced.
Design implication: keep the models that must survive a disruption small, local and deterministic in their fallback. Reserve heavier reasoning for planning cycles that can tolerate a pause.

Does Florida regulate AI? Why procurement contracts carry the governance load

The proposed Artificial Intelligence Bill of Rights was designed to impose conditions on government contracts for AI technology. It cleared the Senate in March 2026 and then died in the House. [6] A second attempt during the April special session cleared the Senate again and died in House subcommittee the following day. [7]
Florida’s port authorities are governmental entities, which puts their AI vendors in the same position as other Florida government contractors. In the absence of a statutory standard, the obligations a buyer wants have to be written into the contract, not inherited from the code.
For Florida buyers of transportation analytics, four contract terms are worth insisting on:
Vendors should read the same signal in reverse. An offering built around accuracy claims alone is harder to defend to a Florida public sector buyer than one built around evidence. Reshaping a service line to lead with explainability, integration commitments, and exit terms is now a commercial advantage rather than a compliance overhead.

Where should supply chain AI in Florida start? Four decisions to automate first

Most Florida operators do not need a network-wide program. They need to get four decisions right :

Demand and inventory positioning

Forecasting that harmonizes historical movement with live market signals changes where stock sits before the order arrives. This is the core of Florida distribution center analytics: fewer emergency freight bookings, less inventory held against uncertainty, and replenishment triggered by a signal rather than a calendar.

Procurement and dispatch

Carrier selection, share-of-business allocation and container utilization are optimization problems with clear constraints. Routing intelligence that removes empty running takes cost out without touching headcount or assets.

Multi-modal visibility

Rail, road and sea data arrive in different formats on different clocks. A single reconciled record per shipment is the prerequisite for everything else, and it is usually the hardest part of the build.

Freight audit and billing reconciliation

Invoice and proof-of-delivery matching recovers money that is already owed. It is the fastest route to a defensible return, and it builds the internal credibility needed for the larger work.
Intuceo, a Jacksonville-based enterprise AI consultancy, built its iTMS supply chain accelerator to address these four as connected modules, with supervisory agents monitoring forecasting, planning, and execution.
Across deployments, Intuceo reports a 30% increase in forecasting accuracy and billing reconciliation accelerated by 40%. The accelerator is deployed as a layer over existing enterprise resource planning and electronic data interchange estates rather than a replacement for them, which matters in Florida, where mainframe and legacy carrier integrations remain in daily service.

Why Jacksonville matters for port, rail, and logistics AI

Northeast Florida is where sea, rail and highway freight converge most tightly. The Jacksonville Port Authority (JAXPORT) runs its cargo terminals in the same city as Class I rail headquarters, which puts the handoff between sea and rail inside one metropolitan area.
Conversations about logistics AI in Jacksonville therefore tend to start at the interchange rather than at the berth, because a container that clears the terminal quickly and then waits on a rail slot has not saved anyone a day. Intuceo is headquartered in Jacksonville and has delivered supply chain and transportation work for operators including CSX and the MTA Long Island Rail Road (LIRR). Proximity matters: the data that makes these models work is held by yard supervisors, dispatchers, and billing clerks, and it can be extracted much faster in person than over a call.

How to choose a supply chain AI consulting partner in Florida

Put a number on where your lead time goes

Intuceo’s supply chain diagnostic baselines one lead-time metric in your Florida network, identifies where it leaks across handoffs, and returns a costed plan to close it within 90 days.

Frequently Asked Questions

The applications with the clearest effect are berth and yard sequencing, gate appointment matching, and predicted container availability shared with drayage carriers before they arrive. Each one shortens the interval between a container becoming available and a truck collecting it. Capital investment in yard equipment raises the number of moves that are physically possible; sequencing intelligence determines how many of them are the right moves.
Supply chain AI in Florida is typically bought in one of three forms: modules inside an incumbent transportation management system, standalone visibility services, or accelerator-led engagements from services firms that build on top of existing systems. The third suits operators with substantial legacy integration, since it avoids a migration. Intuceo’s iTMS accelerator sits in that category, covering forecasting, dispatch, multi-modal visibility and freight audit as connected modules.
AI helps Florida distribution centers manage inventory in real time by replacing periodic stock reviews with continuous signals. Demand models informed by inbound vessel schedules, order patterns and carrier performance indicate what should be positioned where, and how much buffer is genuinely required. The practical result is fewer expedited shipments and less capital held against uncertainty, with exceptions surfaced while they can still be acted on.
There is no single best platform; the best fit depends on the systems you already operate. Buyers running modern cloud systems can often extend them. Buyers running mainframe, legacy electronic data interchange or long-standing carrier integrations, which describes much of Florida’s rail and port ecosystem, generally get further with a services-led engagement that layers intelligence over those systems. Evaluate AI consulting partners in Florida on integration record, explainability, time to a measurable result, and their willingness to commit to a defined first metric.
Not as of this writing. Florida has no general AI statute. The proposed Artificial Intelligence Bill of Rights, which would have set conditions on government AI contracts, passed the Senate twice in 2026 but died in the House both times. Buyers, including port authorities, have to write explainability, data residency, and audit requirements into contracts.
Intuceo scopes its supply chain diagnostic to deliver a baseline and costed plan within 90 days, and iTMS deployments typically reach a live pilot with measurable ROI in about 90 days.

Zero-Shot Segmentation in Manufacturing: What It Can and Cannot Do

Segmentation has long been one of the most labor-intensive steps in a vision project. Every defect, component edge, or region of interest had to be outlined by hand, pixel by pixel, often across thousands of images.
Promptable foundation models changed that cost structure, at least in principle. An object can now be pointed at, or described, and a mask returned without task-specific training.
The question for quality and engineering teams is how much of that holds up on a real line. While zero-shot segmentation in manufacturing is useful for a defined set of jobs, it is unsuitable for others. This guide separates the two, explains why, and sets out a practical way to test it before anyone commits budget.

Key Takeaways

What zero-shot segmentation means in industrial inspection

Segmentation assigns each pixel in an image to a region: this area is the part, that area is a scratch, the rest is background. Traditional segmentation models learn those regions from hand-drawn masks on the exact task they will perform.
Zero-shot segmentation skips that task-specific training. A foundation model pretrained on a very large, general dataset is prompted at runtime with a point, a bounding box, or, in some setups, a text description, and returns a mask. The best-known example is Meta AI Research’s Segment Anything Model (SAM). Its authors assembled a dataset of over 1 billion masks on 11 million licensed images and trained the model to be promptable so that it transfers zero-shot to new image distributions and tasks.
That scale is the reason the approach generalizes. It is also the reason for caution. None of those images were taken on your line, under your lighting, of your product parts.

Where zero-shot segmentation performs well

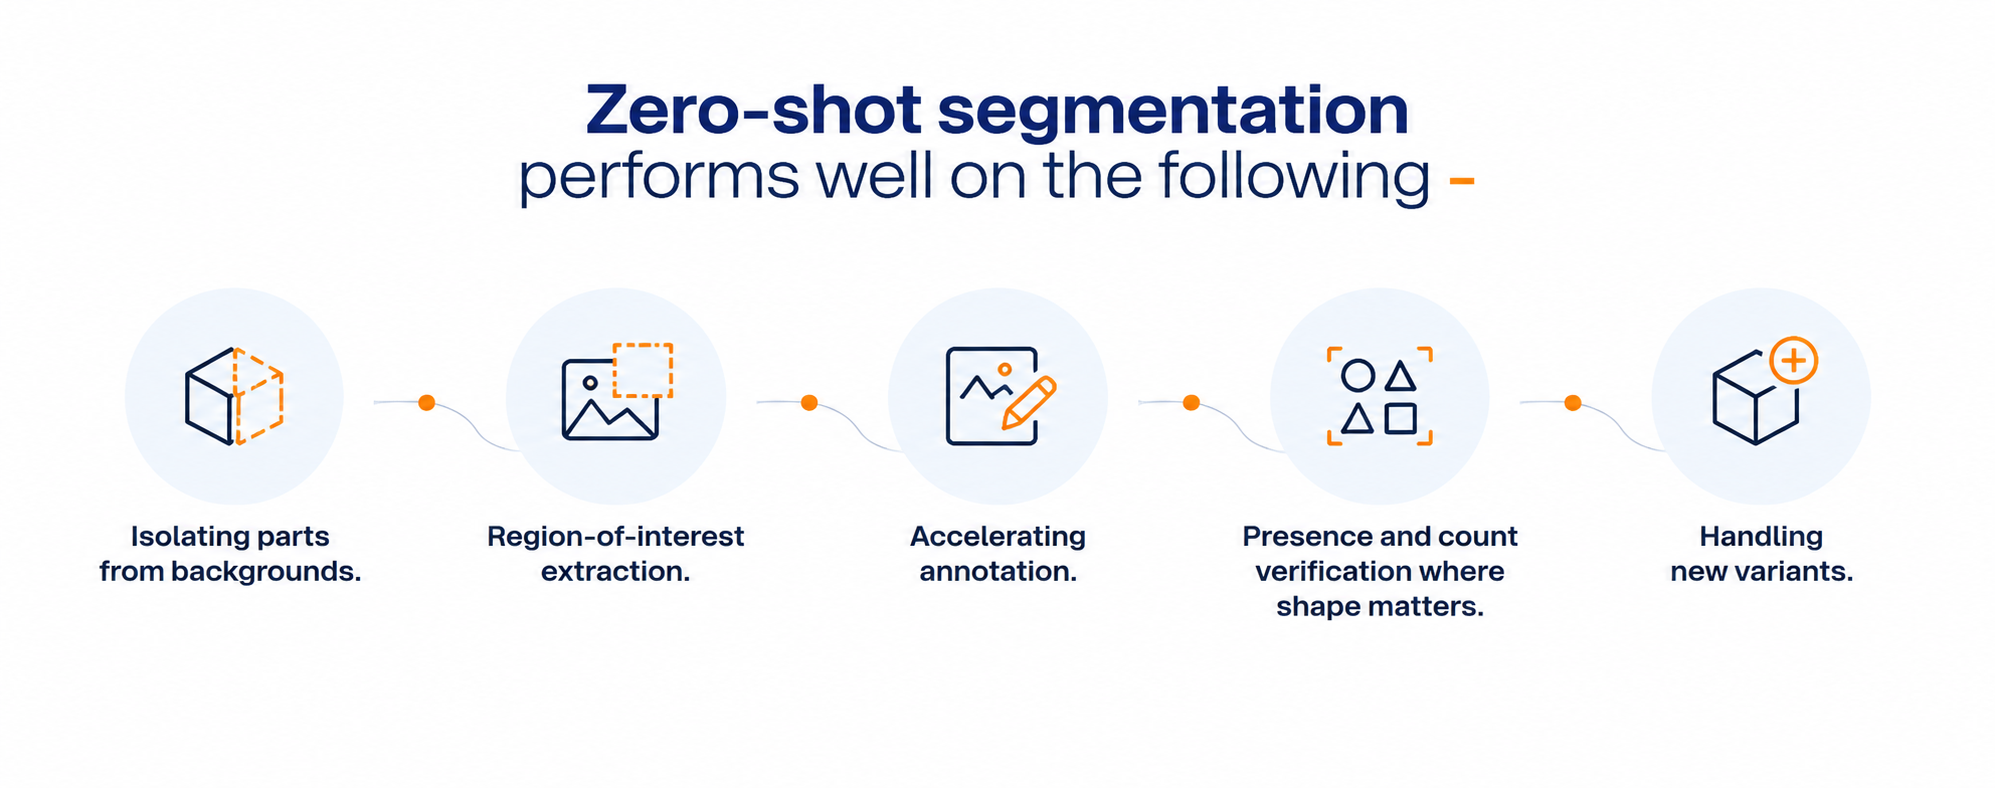
The strongest fits share one trait: the region being segmented is visually distinct from its surroundings.
In each case, the model performs localization. It reports where something is. A separate step decides whether that something is acceptable.

Where zero-shot segmentation is unreliable

The limitations map closely onto the defect types manufacturers care about most.

Fine and low-contrast defects

Hairline cracks, micro-scratches, faint discoloration, and subtle porosity often lack clear edges. The SAM authors state that the model can miss fine structures, sometimes generates small disconnected components, and does not produce boundaries as crisply as more computationally intensive methods.[1] On a production line, a missed hairline crack is not a small error to be overlooked.

Acceptance criteria

A mask is not a verdict. The model can outline a mark on a surface without any sense of whether that mark is cosmetic, within tolerance, or cause for rejection. Acceptance criteria live in your quality system, not in a general-purpose model.

Consistency across imaging conditions

Glare, reflective metal, transparent packaging, and shifting ambient light can change results from one frame to the next. The absence of task-specific training does not reduce a model’s sensitivity to imaging conditions.

Speed at line rate

Large foundation models are computationally heavy. Where a decision must be made inside a single machine cycle, the full model may not keep pace without dedicated hardware or a lighter distilled version.

Zero-shot detection vs. segmentation: which does your inspection need?

The two terms are often blended, and the difference affects system design. Zero-shot detection in industrial inspection draws a box around a candidate and assigns a label. Zero-shot segmentation draws the outline. Detection is usually sufficient for presence, position, and counting, and it costs less to run. Segmentation earns its additional compute when shape, area, or boundary precision matters, such as measuring a coating gap or the extent of a surface defect.
Aspect Zero-shot detection Zero-shot segmentation
Output A box and a label A pixel-level outline (mask)
Best for Presence, position, and counting Shape, area, and boundary precision
Compute cost Lower Higher
Example Confirming a part is present Measuring a coating gap or defect extent
Teams often chain the two. An open-vocabulary detection model locates candidate regions from a text prompt in production, and a segmentation model outlines what sits inside each box.

Where does the Segment Anything Model (SAM) fit in manufacturing workflows?

The roles above differ mainly in how much human judgment sits between the mask and the decision, and that is what should order a SAM manufacturing rollout. Exploratory analysis of archived images carries no line risk, because nothing reaches production. Annotation assistance comes next, because an engineer approves every mask before it becomes training data. Preprocessing follows, since a trained classifier still makes the call on the cropped region.
A fourth role, treating the model as the final accept-or-reject authority, is where most disappointment occurs. It is rarely the right starting point.

How do vision-language models and segmentation models work together?

Foundation models for visual inspection increasingly work as a set rather than alone. A vision-language model can be asked whether an image shows anything unusual and to describe it. A segmentation model then outlines the region it points to. That pattern is behind most current interest in vision-language models for defect detection, particularly for unfamiliar anomalies. It also stacks two sources of uncertainty, so validation on your own images matters more.

How do you test zero-shot segmentation on your production line? 7 steps

A short, structured test answers most questions before a full project starts. Seven steps cover the ground.
  1. Assemble a hard evaluation set: Include your subtle defects, reflective parts, and worst lighting, not only clear examples.
  2. Define success in operational terms: Mask overlap scores are useful, but the decisive question is whether the mask would lead to the right part disposition: accept, rework, or reject.
  3. Compare prompt types: Points, boxes, and text prompts behave differently. Test the one you would actually use in production.
  4. Measure speed on target hardware: Benchmark on the device that would sit near the line, not a research workstation.
  5. Repeat across shifts and variants: Run the same prompts on images from different shifts, operators, lighting states, and a recent part variant, to see whether performance holds without adjustment.
  6. Record how it fails, not only how often: A model that misses in predictable ways is easier to manage than one that fails at random, and a clear list of what it misses is as valuable as an accuracy score.
  7. Check review time and traceability: If reviewing uncertain masks takes longer than manual inspection, the workflow needs redesign. Record model version, prompt, and image for each output so decisions can be audited later, a standard practice in production MLOps pipelines.
If a zero-shot model performs well only after heavy prompt tuning on a handful of images, run the same prompts on a fresh batch before trusting the result. Overfitting prompts is easier than it looks.

When should you move from zero-shot to a fine-tuned model?

Move beyond zero-shot when fine defects dominate, tolerances are tight, or decisions must be made within a machine cycle. Zero-shot segmentation for industrial inspection is often the fastest way to learn whether a computer vision inspection project is tractable, but it is not always the final answer. In those cases, the usual next step is fine-tuning on a modest set of your own images or distilling results into a smaller model.

How Intuceo approaches segmentation work

Intuceo starts with the inspection decision the business needs, then works backward to whether segmentation, detection, or a simpler rule is the right tool. Scope your inspection use case with an AI architect.

Two capabilities carry most of the delivery on vision work. High-fidelity visual inspection applies image segmentation, sub-pixel anomaly detection, and automated feature extraction to sub-millimeter defects, including precision medical optics, where surface anomalies, edge irregularities, and contaminants have to be caught at production speed. Multi-modal vision intelligence brings video, image, and metadata streams together so inspection results arrive alongside line system signals rather than in a separate console.

Deployment is the part that has to survive audit. Intuceo delivers in on-premise, private cloud, and air-gapped environments, driven by PhD-led engineering teams with prior deployments in regulated and high-precision environments. See how this applies across AI-driven advanced manufacturing and to the ML and computer vision capability built for it.

Join AI Dream Session, Vol. 2: Computer Vision Reimagined

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute live session with Intuceo on Thursday, September 24, 2026, at 11:00 AM ET. It covers how newer vision models reduce dependence on large labeled datasets, and where accuracy and production conditions still create hard problems.

Frequently Asked Questions

It is the ability to outline objects or regions in an image using a pretrained foundation model, guided by a prompt such as a point, box, or text description, without training on your specific parts. In inspection, it is most often used to isolate components, extract regions of interest, and speed up labeling, rather than to make final quality decisions on its own.
Not entirely. They can sharply reduce the labeling needed to get started and can pre-label images for engineers to correct. You still need a labeled evaluation set from your own line to confirm performance, and many subtle defect types still benefit from fine-tuning on examples specific to your process.
Four limits dominate: weak performance on fine or low-contrast defects, no built-in understanding of acceptance criteria, sensitivity to glare and lighting changes, and heavy compute requirements for large models.
Yes, in well-chosen roles: annotation assistance, preprocessing that isolates parts or regions, and exploration of archived images. Using them as the sole accept-or-reject authority is riskier.
Not always. Large foundation models are computationally heavy, so decisions inside a single machine cycle may need dedicated hardware or a smaller distilled model.