Live AI Dream Session, Vol. 3: Trustworthy AI in Practice with Sarath Kuravi and Dr. Shonraj Ballae • Nov 10 | 11:00 AM EST Reserve Your Seat Claim Free Seat

Reserve Your Seat

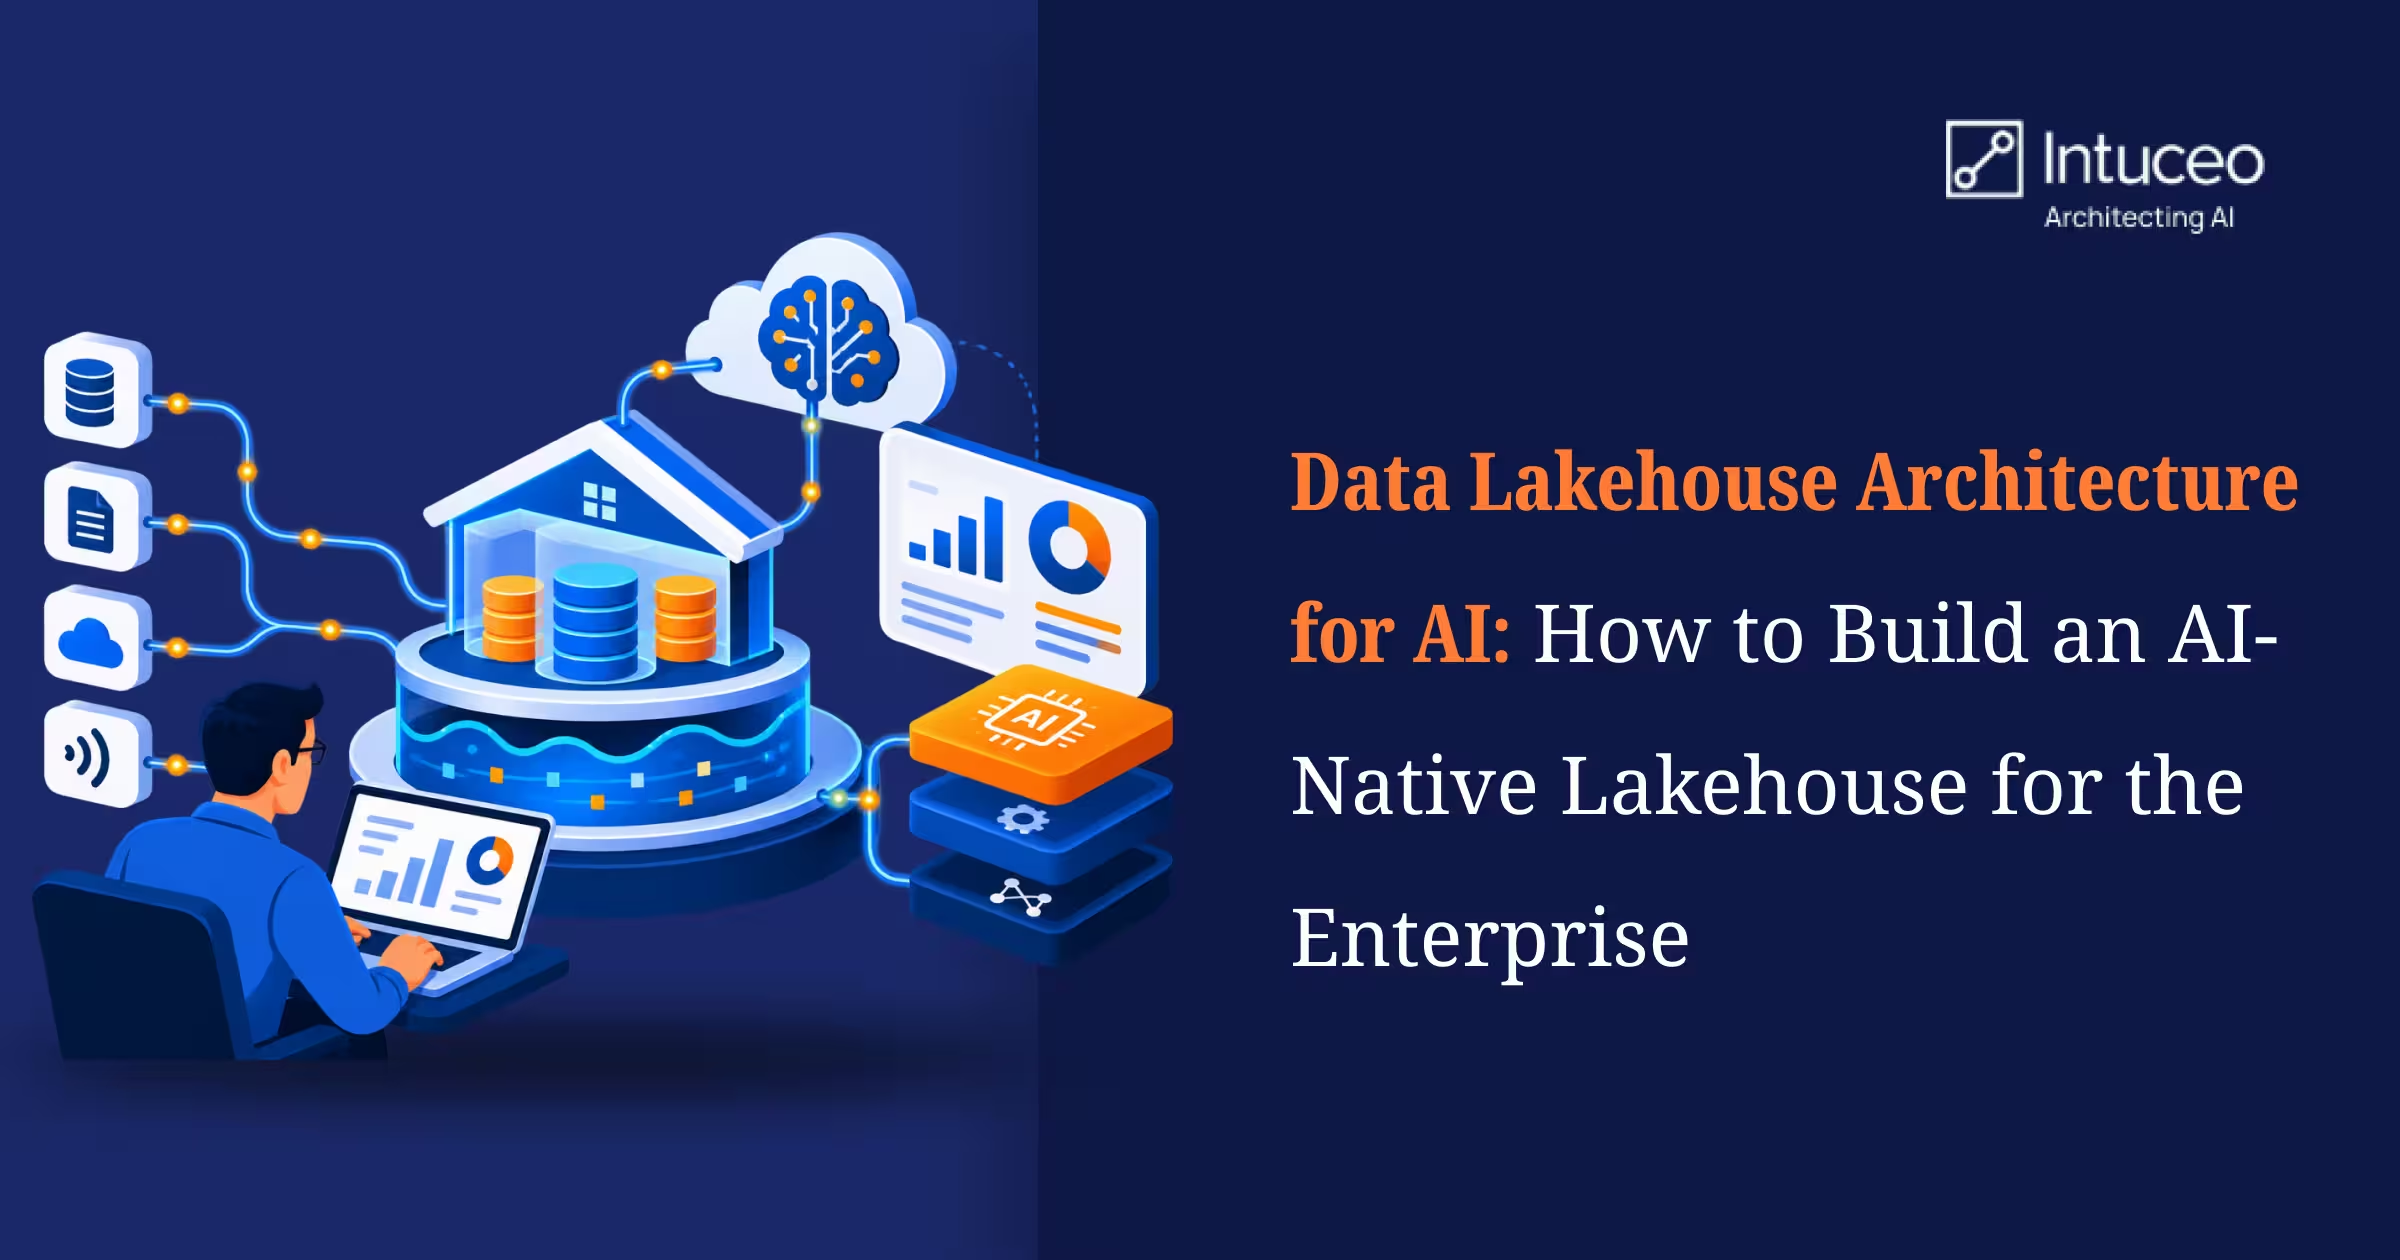
Data Lakehouse Architecture for AI: How to Build an AI-Native Lakehouse for the Enterprise

Enterprise data teams are being asked to deliver two things from one stack: trusted business intelligence for finance and operations, and reliable training data, features, and retrieval context for machine learning and generative AI. The warehouse-plus-lake split that most organizations inherited was never designed to carry both. In practice, that shows up as duplicated data across systems, governance scattered across tools, and compute spend climbing faster than the model teams it is supposed to serve.
An AI-native lakehouse is a data lakehouse architecture for AI that treats machine learning (ML), feature engineering, and large language model (LLM) retrieval as first-class workloads from day one, built on the same storage, catalog, and lineage that serve traditional analytics.
This guide walks through what makes an enterprise data lakehouse architecture AI-native, a reference layering model, the choice between Databricks and Snowflake for enterprise AI, how MLOps on a lakehouse works, and how to migrate without stalling existing reporting.

Key Takeaways

What Is an AI-Native Data Lakehouse?

An AI-native data lakehouse, sometimes called an AI-ready data lakehouse, is a lakehouse built so analytics, model training, feature serving, and LLM retrieval run on one governed copy of data. It stores open table formats such as Delta Lake or Apache Iceberg on object storage and adds vector search, a feature store, and unified catalog governance.

Data Lakehouse vs Data Warehouse: What Makes a Lakehouse AI-Native?

The data lakehouse vs data warehouse comparison usually gets reduced to a cost argument. The bigger difference matters more for AI. A warehouse is built for curated, structured data queried through SQL. A lake accepts everything, but without transactional guarantees or consistent schema, it rarely produces training sets a data scientist could trust twice in a row.
The lakehouse pattern consolidates both using an open table format, Delta Lake, Apache Iceberg, or Apache Hudi, on top of cheap object storage. That gives data teams ACID (atomicity, consistency, isolation, durability) transactions, schema evolution, and time travel against the same files that feed Python notebooks, SQL dashboards, and Spark jobs.
Calling it AI-native adds four things to that foundation:
The table below summarizes how the three architectures compare for AI workloads.
Capability Data warehouse Data lake AI-native lakehouse
Data types Structured All types All types
Transactions ACID None by default ACID through open table formats
ML and GenAI readiness Requires export Raw, often unreliable Native features, vectors, and models
Governance Strong, warehouse-only Fragmented One catalog for data and AI assets
Reproducibility Limited Weak Time travel on training data
Gartner analyst Prasad Pore reports 65% lakehouse adoption among Gartner’s client base, which positions the pattern as the default substrate for new AI workloads rather than a parallel experiment.[1]

Data Lakehouse Architecture for AI: A Six-Layer Reference Model

A workable reference design has six layers. Each has its own failure modes, so each needs its own ownership and controls.

1. Storage Layer: Open Table Formats on Object Storage

Object storage, Amazon S3, Azure Data Lake Storage, or Google Cloud Storage, holding Parquet files under an open table format. Delta Lake and Iceberg are the two formats most enterprise teams converge on. Both give ACID semantics; the choice usually comes down to the compute engine already in play.

2. Catalog and Governance Layer: One Control Plane for Data and AI

Unity Catalog (Databricks’ governance layer), Snowflake Horizon (Snowflake’s governance layer), or an open equivalent such as Apache Polaris (an open Iceberg catalog). This layer carries access control, lineage, and audit for every object the AI stack will touch. Data lakehouse governance decisions made here propagate to features, models, and prompts without re-implementation.

3. Transformation and Quality Layer: The Medallion Pattern

A medallion pattern of Bronze (raw ingest), Silver (cleaned and conformed), and Gold (business-ready) tables, built with Spark, dbt, or SQL. Data quality checks run as pipeline tests, not as a downstream dashboard.

4. Feature and Model Layer: Reproducible Training Data

Feature store, model registry, and experiment tracking. MLflow is the open reference. Features reference the Silver and Gold tables by version, so a training set from last quarter can be rebuilt exactly.

5. Serving and Retrieval Layer: RAG, Features, and Agents

Vector indexes for retrieval-augmented generation (RAG), online feature serving for low-latency inference, and model endpoints for both batch and real-time. For agentic AI workloads, this layer also exposes governed data to the Model Context Protocol or equivalent connectors.

6. Observability Layer: Drift, Health, and Cost

Pipeline health, data drift, model performance, and cost telemetry in one view. Without it, the lakehouse quietly degrades into another cost center.

How Do You Build a Data Lakehouse for AI Workloads?

The answer resolves at the catalog and feature layers. Those two carry the governance and reproducibility that separate production AI from disposable prototypes.

When Should You Choose a Big 4 Firm or Large Integrator for AI?

Databricks vs Snowflake for enterprise AI comes down to starting point: Databricks fits engineering- and ML-heavy teams building models and agents on open formats, while Snowflake fits SQL- and BI-heavy teams adding AI to governed analytics.
Databricks is a Spark-native environment with Delta Lake and Unity Catalog at its core. It appeals to organizations with heavy data engineering and ML workloads, deep Python usage, and a preference for notebook-driven development. MLflow, Model Serving, Vector Search, and Agent Bricks sit on the same catalog as the raw tables. For teams building retrieval pipelines, fine-tuned models, or multi-agent systems against proprietary data, this consolidation is the main argument.
Snowflake began as a SQL-first warehouse and extended into the lakehouse pattern through Iceberg table support, Snowpark for Python and ML, Cortex for LLM features, and Horizon for governance. It suits organizations with substantial SQL and BI investment that want to add AI workloads without rebuilding the analytics layer.
Factor Databricks Snowflake
Origin Spark-native lakehouse SQL-first warehouse
Default table format Delta Lake Native tables plus Iceberg
Governance Unity Catalog Horizon
ML and GenAI tooling MLflow, Model Serving, Vector Search, Agent Bricks Snowpark, Cortex
Best fit Heavy data engineering, Python, custom models, agents Heavy SQL and BI investment, AI added to analytics
Delta Lake deserves a note of its own for enterprise AI. As an open table format, Delta Lake runs under both Databricks and increasingly outside it, including through Iceberg interoperability. Time travel, schema enforcement, and change data feed are the properties that make reproducible training sets and auditable model lineage practical rather than aspirational.
The best data lakehouse architecture for AI, in practice, is the one aligned with the organization’s existing skills, cloud footprint, and governance maturity. The decision rarely turns on a feature matrix. It turns on how much of the current stack can carry forward, which is the first thing an Intuceo lakehouse readiness assessment maps.

How Does MLOps Work on a Data Lakehouse?

MLOps on a lakehouse keeps features, training sets, models, and serving endpoints under the same catalog as the source tables that produced them. That matters for three reasons.
First, reproducibility. Time travel on the underlying Delta or Iceberg tables lets a team retrain a model on the exact data version it was first trained on, which is often what regulators and internal audit actually ask for.
Second, lineage. When a model drifts, the engineering team can trace from the serving endpoint back through the feature, the Gold table, the Silver transformation, and the raw Bronze ingest, inside one lineage graph.
Third, governance. Databricks’ 2026 State of AI Agents report, based on telemetry from more than 20,000 organizations, found that companies using AI governance tools put 12 times more AI projects into production than those without.[2] On a lakehouse, that governance is applied once at the catalog layer and inherited by every downstream model, feature, and agent, the principle behind Intuceo’s DARWIN AI governance approach.
For generative AI specifically, the lakehouse also serves as the retrieval substrate for enterprise LLM infrastructure. Vector indexes sit alongside structured tables, so RAG pipelines and agents can combine semantic search with precise filters against the same governed data without copying it into a separate store.

How to Migrate From a Data Warehouse to a Lakehouse Without Breaking Reporting

A full lift-and-shift data warehouse to lakehouse migration rarely succeeds and rarely pays back inside a budget cycle. A workload-first migration does: move the jobs the warehouse handles poorly first, dual-run reporting during cutover, and retire warehouse workloads only once their replacements are proven.
Migrations that follow this pattern deliver AI workloads first, which is what justified the move in the first place, and let BI follow once the lakehouse has proven itself on harder problems.

How Intuceo Builds AI-Native Lakehouses for Regulated Industries

Intuceo designs and builds AI-native lakehouses on Databricks and Snowflake for regulated industries, including healthcare, life sciences, and the federal space, with Unity Catalog or Horizon governance applied from day one and MLflow-based model lineage tied to the underlying Delta or Iceberg tables.
Where Intuceo’s delivery differs from a generic data engineering engagement: a reference medallion design hardened across prior client engagements including Florida Blue, GuideWell Health, UF Health, Janssen Pharma, and Bausch & Lomb; accelerators such as Intuceo-Ax™ for explainable classification workloads and iPDLC™ for faster AI delivery; and a 20-year track record engineering compliant data environments for Fortune 1000 and federal clients.
Get a lakehouse readiness assessment of your current stack and a 90-day plan to serve your highest-value AI workload from a governed foundation.

Frequently Asked Questions

Compliance belongs in the catalog and storage layers, not in each downstream tool. Unity Catalog or Horizon enforces access control, row and column masking, audit logging, and lineage once, and every feature, model, and agent that reads governed tables inherits those controls. For regulated workloads such as HIPAA-compliant healthcare analytics, pair that with pipeline-level de-identification and tokenization of personally identifiable information (PII) and protected health information (PHI) so sensitive fields never reach training sets or vector stores unless an approved use case explicitly requires them. Audit evidence then flows from the catalog itself rather than from a parallel compliance report.
Both open table formats offer ACID guarantees, schema evolution, and time travel on object storage. Iceberg has broader cross-engine support across Snowflake, Trino, Spark, Flink, and DuckDB, which makes it the stronger choice when the compute strategy is multi-vendor or likely to shift. Delta Lake has deeper feature maturity on Databricks-centric stacks, including Change Data Feed, Deletion Vectors, and tighter integration with MLflow and Unity Catalog. Interoperability layers such as Delta UniForm now let teams write in one format and read through the other, which reduces the need to pick permanently on day one.
Lock-in exposure on a lakehouse is lower than on a warehouse because the data sits in open file and table formats on commodity object storage. Keep the storage layer and the chosen table format decoupled from the compute engine, treat the catalog as a governed abstraction rather than a vendor contract, and avoid encoding critical business logic in proprietary stored procedures or notebook-specific features. Portability becomes a design choice rather than a vendor feature. A lakehouse built this way can be read by multiple engines concurrently and migrated to a different compute vendor without moving the underlying data.
Agents need their own identities, scoped credentials, and audit trails distinct from the human users who deploy them. Grant least-privilege access through the catalog so an agent sees only the tables, columns, or rows its task actually requires, and route inference traffic through a gateway that enforces rate limits, prompt filtering, and output guardrails. For sensitive data, prefer a retrieval interface over direct table access: the agent requests information through a governed endpoint and never reads raw rows it has no business touching.
For most AI workloads, yes. A lakehouse stores structured and unstructured data together, adds ACID transactions through open table formats, and lets features, models, and vector indexes share one catalog with the source tables. A warehouse still suits curated SQL reporting, which is why many enterprises dual-run both during migration.
Six layers: object storage with an open table format, a catalog for governance and lineage, a transformation layer using the Bronze/Silver/Gold medallion pattern, a feature and model layer, a serving and retrieval layer for RAG and agents, and an observability layer for drift, pipeline health, and cost.
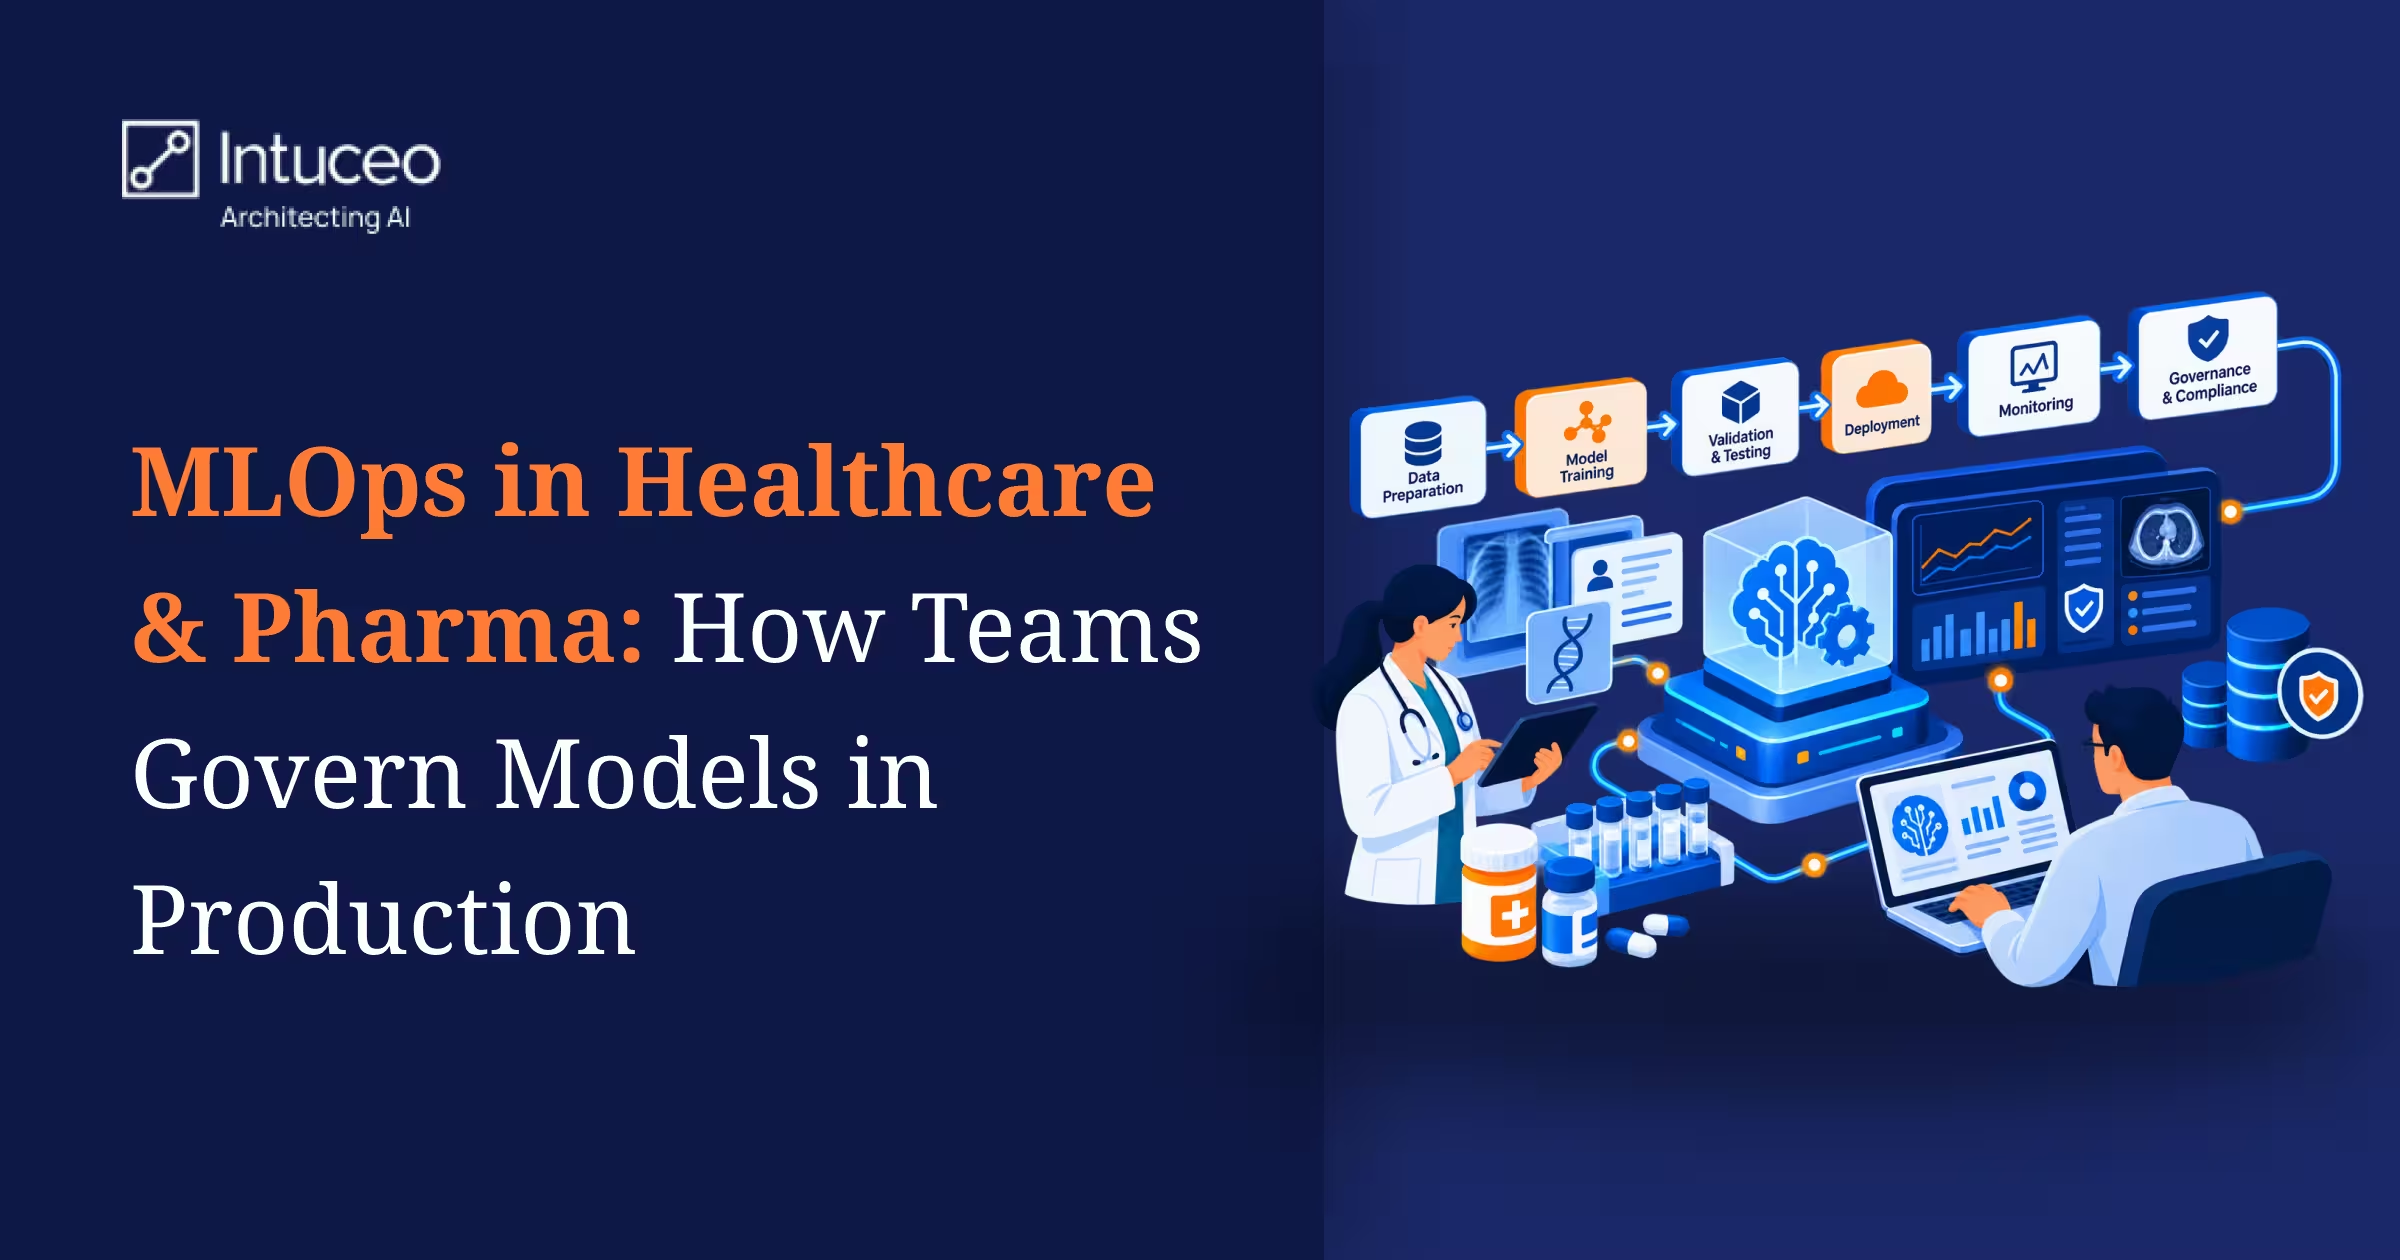
MLOps in Healthcare and Pharma: How Teams Govern Models in Production

A model that classifies adverse event reports or stratifies patient risk becomes a regulated computerized system the day it goes live, with one complication that conventional validation never had to absorb: its performance depends on data it has not seen yet. The records it produces still carry the same integrity, traceability, and privacy obligations as a batch record or a claims file. MLOps in healthcare and pharma is the discipline that keeps those two facts aligned, so that every model in production can be reproduced, explained, and defended at inspection.
Machine learning operations (MLOps) already gives teams the raw mechanics: pipelines, experiment tracking, model registries, and monitoring. This guide covers what healthcare and pharma teams add on top of those mechanics, stage by stage, building on our broader guide to MLOps for regulated industries.
What is MLOps in healthcare and pharma?
MLOps in healthcare and pharma is the practice of running machine learning pipelines so every production model can be reproduced, explained, and defended at inspection. It adds regulated controls to standard MLOps: validated releases, Part 11 audit trails, HIPAA safeguards, and change control that is approved before retraining begins.

Key Takeaways

Which Regulations Apply to MLOps in Healthcare and Pharma?

No single regulation governs machine learning (ML) in healthcare and life sciences. Teams assemble their obligations from records rules, privacy law, the good practice regulations collectively known as GxP (manufacturing, clinical, laboratory, and pharmacovigilance), and artificial intelligence (AI) guidance that is still maturing. The documents below carry the most weight for models in production.
Source Status What it asks of the pipeline
21 CFR Part 11 (Code of Federal Regulations) Binding regulation Validated systems, secure time-stamped audit trails for record creation, modification, and deletion, and change control over systems documentation[1]
Health Insurance Portability and Accountability Act (HIPAA) Security Rule, 45 CFR 164.312 Binding regulation Access control, integrity safeguards, and audit controls that record and examine activity in systems holding electronic protected health information (ePHI)[2]
U.S. Food and Drug Administration (FDA) guidance on AI for drug and biological decision-making, January 2025 Draft, nonbinding A risk-based credibility assessment for a defined context of use, with life cycle maintenance after deployment[3]
FDA and European Medicines Agency (EMA) Guiding Principles of Good AI Practice, January 2026 Joint principles Traceable data provenance in line with GxP, risk-based performance assessment, and scheduled monitoring for issues such as data drift[4]
FDA Predetermined Change Control Plan (PCCP) guidance for AI-enabled device software Final, nonbinding Pre-specified modifications, a protocol to develop, validate, and implement them, and an impact assessment[5]
European Union (EU) Good Manufacturing Practice (GMP) Annex 22, Artificial Intelligence Consultation draft Continuous oversight of AI systems, including change control, performance monitoring, and human review procedures[6]
The practical reading of the table is that Part 11 and HIPAA are enforceable today, while the AI-specific documents describe the evidence inspectors will increasingly expect to see. FDA AI compliance in 2026 therefore means satisfying binding records and privacy rules with evidence organized the way the AI guidance describes it.

How Does FDA’s Context of Use Shape AI Model Validation?

FDA’s draft guidance anchors validation to a defined question and a context of use (COU), then rates model risk on two factors. Model influence is the weight the model’s output carries in the decision relative to other evidence. Decision consequence is the significance of an adverse outcome if that decision turns out to be wrong.[3]
The guidance’s own example of high risk on both counts is a model used to decide which trial participants can skip inpatient monitoring after dosing. A model that ranks literature for a human reviewer would sit far lower, and its credibility plan can be lighter in proportion.
This framing answers how FDA expects AI models to be validated and monitored in clinical settings: through evidence scaled to risk, defined before deployment, and maintained for as long as the model is in use. Operationally, the COU statement, risk rating, and acceptance criteria belong in the model registry as metadata on every version. When an inspector asks why a model was validated the way it was, the answer then travels with the model rather than sitting in a document nobody can locate.

How to Govern MLOps in Healthcare and Pharma, Stage by Stage

Implementing MLOps in healthcare and pharma comes down to deciding what evidence each stage must produce, then making the pipeline produce it automatically.

How Is MLOps in Healthcare Different From Standard MLOps?

Standard MLOps and its regulated form share the same tooling. The difference is the evidence each step has to leave behind.
Area Standard MLOps MLOps in healthcare and pharma
Data Versioned datasets Immutable, hashed snapshots linked to each model version, with ePHI kept in access-controlled zones and de-identified before experimentation
Validation Metrics reviewed after training Acceptance criteria fixed before training, tested on held-out data, with the report assembled from pipeline metadata
Release Automated promotion to production An approval signature bound to a specific model version, with a Part 11 audit trail of who approved what and when
Monitoring Drift alerts Thresholds set by the COU risk rating; a breach opens a quality investigation with documented root cause
Retraining Scheduled or triggered automatically A retraining protocol or PCCP, approved in advance, covering triggers, data windows, acceptance criteria, and rollback
Accountability The ML team A named owner, risk tier, and review date in a model inventory, with human review of AI outputs that inform regulated decisions

Stage 1: Data Preparation and Provenance

The FDA and EMA principles ask that data provenance, processing steps, and analytical decisions be documented in a traceable, verifiable manner consistent with GxP.[4] In practice, every training set becomes an immutable, hashed snapshot that a model version points to, so retraining on identical data is always possible. A HIPAA-compliant ML pipeline adds two controls at this stage: ePHI stays inside access-controlled zones with logged activity, and data is de-identified before it reaches experimentation environments that have no need for identifiers.

Stage 2: Training and Validation

GxP MLOps for pharma uses the same automation as conventional MLOps, operated under a risk-based quality system so the automation itself generates the evidence. Each training run captures the code commit, container image, parameters, and dataset version without manual entry. Performance is tested against acceptance criteria fixed before training, on held-out data the team did not tune against, and the validation report is assembled from pipeline metadata instead of being written after the fact.

Stage 3: Release and Approval Under Part 11

Promotion from staging to production is where 21 CFR Part 11 AI validation concentrates, starting with validation of the systems involved (§11.10(a)). The promotion is an electronic record: it needs an approval signature bound to a specific model version (§11.70), and an audit trail showing who approved what and when (§11.10(e)). Part 11 also requires change control over systems documentation (§11.10(k)), which in an MLOps setting extends to pipeline definitions and infrastructure code.[1]

Stage 4: Production Monitoring and Drift

Monitoring covers three signals: shifts in input distributions, shifts in output distributions, and realized performance once ground truth arrives, such as adjudicated adverse event cases or confirmed readmissions. In healthcare MLOps, alert thresholds should follow the COU risk rating. A breach opens an investigation under the quality system with documented root cause, which keeps automatic retraining from silently masking a problem. Prediction logs are records in their own right and need retention periods aligned with the underlying regulation.

Stage 5: Change Control and Retraining

Every retrained model is a new version, and the pharma AI model lifecycle depends on deciding in advance how much revalidation each type of change requires. For AI-enabled medical devices, a PCCP lets manufacturers describe planned modifications, the methodology to develop, validate, and implement them, and an assessment of their impact, so pre-authorized changes do not each need a new marketing submission.[5] The draft EU Annex 22 points in the same direction for manufacturing, pairing change control with ongoing performance monitoring.[6] The retraining protocol, covering triggers, data windows, acceptance criteria, and rollback, should be approved before the first deployment rather than drafted during the first incident.

Evidence Each Stage Must Produce

The table below summarizes what the pipeline should generate at each stage, and which requirement drives it.
Stage Evidence the pipeline must produce Main driver
Data preparation Hashed, immutable training data snapshots tied to each model version, logged ePHI access, and de-identified data for experimentation FDA and EMA principles; HIPAA Security Rule
Training and validation Code commit, container image, parameters, and dataset version for every run, plus results against pre-set acceptance criteria GxP risk-based quality system
Release and approval An approval signature bound to the model version, an audit trail of approvals, and change control over pipeline and infrastructure code 21 CFR Part 11
Production monitoring Input, output, and performance monitoring records, investigation records for threshold breaches, and retained prediction logs FDA draft AI guidance; FDA and EMA principles
Change control An approved retraining protocol or PCCP, and revalidation evidence for every new model version FDA PCCP guidance; draft EU Annex 22
Not sure your retraining protocol would hold up at inspection? Book a governance gap review.

Why Is Human Oversight Required for AI in GxP Settings?

In an April 2026 warning letter, FDA stated that when a manufacturer uses AI to help with current good manufacturing practice (CGMP) activities, any output or recommendation from an AI agent must be reviewed and cleared by an authorized human representative of the firm’s quality unit.[7] That case involved AI-drafted specifications and procedures rather than a deployed predictive model, yet the principle carries over directly: accountability for an AI-assisted decision stays with named people.
The FDA and EMA principles reinforce this by asking that performance assessment cover the complete system, including human and AI interaction.[4] For MLOps teams, that translates into review queues for low-confidence outputs, explanations surfaced at the point of review, overrides captured in the audit trail, and override rates tracked as a monitoring signal in their own right. Sound model governance for healthcare AI wraps these controls in a model inventory that records an accountable owner, a risk tier, and a periodic review date for every model in service.

How Intuceo supports governed MLOps

Intuceo is a PhD-led AI, ML, and data analytics services firm whose life sciences work includes Janssen, Ferring Pharmaceuticals, and Bausch & Lomb. Its MLOps engagements build compliance into the pipeline from the first commit, so audit logs, lineage, and validation evidence accumulate through normal operation. Deployed models carry drift monitoring, controlled retraining loops, and interpretability views designed for the reviewers who sign off on outputs.
Explainability, bias checks, and model documentation are reviewed by Intuceo’s PhD-led Board of Science & Innovation, and the iPDLC™ delivery framework places PhD-led quality gates at every transition from development to production. Teams work across MLflow, Kubeflow, and Amazon SageMaker, so governance fits the stack a client already runs instead of forcing a migration.
Running models in production ahead of an inspection or a submission? Get a governance gap review that maps each model to its context of use, audit trail coverage, and change control readiness.

Frequently Asked Questions

Pharma companies govern ML models under Part 11 by first scoping which ML artifacts count as regulated records. FDA’s Part 11 scope and application guidance ties the rule to records that other regulations, known as predicate rules, already require. It also describes enforcement discretion for certain Part 11 requirements, while predicate rule obligations stay fully in force.[8] Pharma teams therefore classify ML artifacts individually. Model outputs that feed a GxP decision, validation reports, release approvals, and training data cited in a submission are typically treated as regulated records. Exploratory notebooks stay outside scope until their results become the basis for a regulated decision.
It looks like a validated computerized system whose validation never fully closes. The International Society for Pharmaceutical Engineering (ISPE) Good Automated Manufacturing Practice (GAMP®) Guide: Artificial Intelligence was published in July 2025 for use alongside GAMP 5 (Second Edition). It covers the AI-enabled system life cycle, the responsibilities of internal and external suppliers, and ongoing monitoring and maintenance.[9] Two practical consequences follow. Cloud ML services used in GxP work need supplier assessment and infrastructure qualification. GxP and non-GxP workspaces should also be kept separate, so exploratory work cannot reach production without passing through change control.
Healthcare organizations keep ML pipelines HIPAA-compliant by de-identifying data, scrubbing identifiers from ML outputs, and holding business associate agreements (BAAs) with vendors. Most start by deciding which de-identification route applies. HIPAA recognizes two: removing a specified list of identifiers, or a formal determination by a qualified expert applying statistical and scientific methods.[10]
Beyond that, the most common leak path in healthcare MLOps is incidental. Identifiers get written into experiment logs, prediction logs, feature store snapshots, or error traces. Most of the gaps teams find in audits close with three steps: scrubbing those outputs, keeping features to the minimum the model needs, and holding BAAs with any vendor that touches ePHI.
A typical pharma MLOps stack has five layers:
Whatever tools you choose, the configured system, including its procedures, access controls, and retention settings, must be validated. That is why tool selection should follow the governance design rather than come before it.
A PCCP lets makers of AI-enabled medical devices pre-specify planned model modifications, the protocol to develop, validate, and implement them, and an assessment of their impact. Once FDA authorizes the plan, changes made within it do not each need a new marketing submission.[5] For MLOps teams, the PCCP becomes the approved rulebook for retraining.

Manufacturing AI in Florida: A Practical Playbook for Aerospace, Defense, and Industrial Manufacturers

Florida holds one of the country’s densest concentrations of precision manufacturing, which makes manufacturing AI in Florida a practical operating decision rather than a future bet. The state is the second-largest aerospace cluster in the United States, with more than 833 aerospace establishments recorded as of 2024. [1] Much of that activity sits in aerospace, defense, and heavy industrial production, where a single escaped defect or an unplanned line stoppage carries consequences most sectors rarely face.
For operators here, the useful question about artificial intelligence (AI) is narrower than much of the market conversation implies: which processes justify it, and under what constraints. A serious approach to AI for aerospace and defense manufacturers begins with understanding that discipline.
Two facts specific to the state shape the answer. Much of the work involves controlled or export-restricted data, which dictates where models and data can physically reside. And most plants sit inside port-based supply chains, so the value of factory-floor intelligence compounds only when it reaches the movement of materials in and out. Both points come after the use cases that consistently repay the investment.

Key Takeaways

Where Does Manufacturing AI in Florida Pay Off First?

What is manufacturing AI? Manufacturing AI is the use of machine learning, computer vision, and natural language processing on production data to detect defects, predict equipment failure, and find the causes of downtime. In Florida’s aerospace and defense plants, it usually runs on-premise or at the production line to meet CMMC and ITAR requirements.
Three categories of work account for most successful AI deployments in advanced manufacturing across aerospace, defense, and industrial plants.

Computer Vision Quality Control at Line Speed

High-frame-rate cameras paired with vision models inspect parts as they move, catching surface flaws, dimensional drift, and contamination that manual checks miss at line speed. In defect-critical production, computer vision inspection shifts quality checks from periodic sampling to continuous coverage.
When the model runs on edge AI hardware at the line rather than in the cloud, the decision stays on-site, and a defective part is pulled in a fraction of a second. For plants where visual inspection ties up skilled labor, the savings are measurable: in Intuceo’s lens defect detection work for precision optics, the vision model reduced manual QA workload by up to 30%.

Predictive Maintenance for Florida Defense Contractors

Vibration, temperature, and acoustic signals from machinery feed predictive maintenance models that estimate remaining useful life (RUL) and forecast failure before it stops a line. For defense contractors running high-value tooling or fleet assets, this converts maintenance from a fixed calendar into a condition-based schedule, which matters most where one asset failure cascades across a program.

Operational Intelligence From Maintenance Logs and Downtime Data

Natural language processing (NLP) applied to technician logs and shift reports surfaces recurring root causes that sensor data alone cannot see, such as procedural drift or environmental factors. Downtime analytics then isolate the sub-processes that quietly erode overall equipment effectiveness (OEE), which is usually where the recoverable margin sits.
The table below summarizes what each use case needs and where it typically runs.
Use case Data it needs Typical deployment under CMMC/ITAR Metric it moves
Computer vision quality control Inspection images, defect labels At the line or on-premise Escape rate, scrap, rework
Predictive maintenance Vibration, temperature, and acoustic data, maintenance history On-premise or FedRAMP Moderate-equivalent cloud Unplanned downtime, maintenance cost
Operational intelligence Technician logs, shift reports, downtime codes On-premise or compliant cloud OEE, repeat failures

How Do CMMC and ITAR Decide Where a Manufacturing AI Model Can Run?

CMMC and ITAR decide where a manufacturing AI model can run, because any system that holds CUI or export-controlled data falls inside the compliance boundary.
Aerospace and defense manufacturers work with two data types that constrain the deployment before any model is built: controlled unclassified information (CUI) such as drawings and specifications, and export-controlled technical data governed by the International Traffic in Arms Regulations (ITAR).
The Cybersecurity Maturity Model Certification (CMMC) program rule took effect on December 16, 2024. It requires defense contractors and subcontractors to safeguard federal contract information (FCI) and CUI, and those requirements flow down through every tier of the supply chain.2
For manufacturing AI in Florida’s defense supply base, the effect is direct. When a vision model trains on part geometry, or a maintenance model ingests telemetry tied to a defense article, the environment holding that data falls inside the assessment boundary.
Cloud services that touch CUI must meet a Federal Risk and Authorization Management Program (FedRAMP) moderate baseline or its equivalent, and export-controlled technical data cannot be shared with foreign persons, in the U.S. or abroad, without export authorization. For many Florida operators, a CMMC-compliant AI deployment therefore means on-premise systems, processing at the line itself, or a sovereign cloud environment rather than a general commercial service.
The flow-down reach matters in this state in particular. Many Florida plants are second- or third-tier suppliers to the primes concentrated on the Space Coast, and a supplier can inherit a certification requirement through its contract without ever selling to the Department of Defense directly. A manufacturing AI program that overlooks that inheritance risks a costly redesign the moment such a clause appears in a contract.
State policy adds a lighter but real layer. Florida has not enacted a broad statute governing private-sector AI use, but its Government Technology Modernization Council, created under section 282.802 of the Florida Statutes, is charged with recommending how the state procures and regulates these systems. [3] For a manufacturer that also sells to state agencies, or that expects federal program scrutiny, the direction favors documentation and explainability that can withstand a procurement review, as covered in our guide to AI compliance for Florida government contractors.
This is where deployments most often go wrong. A team builds a capable model, then discovers only afterward that its data path breaches a flow-down obligation, and the rebuild that follows is expensive. Scoping the compliance boundary first, then deciding where the model will run, avoids that cost. Teams that want a second view before building can map their compliance boundary with our team.
A firm evaluating manufacturing AI consulting partners should weight demonstrated experience operating inside controlled environments, including sovereign, explainable AI deployments.
Intuceo, a Jacksonville-based AI and data analytics services firm, has delivered predictive analytics on federal defense work and builds on-premise systems at the production line and in FedRAMP-aligned cloud environments, which is the relevant qualification when the data cannot leave a controlled boundary. It also holds a State of Florida term contract through the Department of Management Services (DMS), a practical convenience for state-adjacent buyers.

How Does Manufacturing AI Connect to Florida Ports and Freight?

Factory-floor intelligence stops paying off at the plant wall unless it connects to what moves in and out. Aerospace and industrial plants in Florida draw materials through the state’s seaports and feed finished goods into distribution networks, so a production schedule is only as reliable as the inbound parts feeding it. This is where supply chain AI in Florida extends a manufacturing program.
For a Northeast Florida operation, inbound automotive and industrial cargo often clears the Port of Jacksonville (JAXPORT). Applying AI to port and yard data aligns berth and gate signals with production demand, so parts arrive against the build schedule instead of piling into buffer stock.
Transportation analytics applied to outbound freight does the reverse, matching finished-goods dispatch to carrier capacity and lane cost. Inside the warehouse, distribution center analytics govern slotting, replenishment, and labor against real order patterns.
Intuceo connects these through its iTMS intelligent transportation management system, whose supply chain modules link production and demand signals to inbound freight and outbound distribution. Its planning modules forecast demand and position inventory, its execution modules optimize procurement and routing, and its verification modules close the loop on delivery. For a manufacturer, that means production and freight decisions draw on the same data, from the machine to the loading dock.

How Do You Take Manufacturing AI in Florida From Pilot to Production?

Start with one process that already has a measured cost and existing data, set the compliance boundary, then pilot on a single line.
The plants that see a return start with a narrow scope. They choose one process where defects or downtime already carry a measured cost and where data is already being captured, because a vision or maintenance model needs history to learn from. Before that, they draw the CUI and export-control boundary, since it decides whether the model runs on-premise, at the production line, or in a compliant cloud, and moving it later is expensive.
Return is measured against the metrics operators already track, such as OEE, yield, scrap, and unplanned downtime, rather than model accuracy in isolation. A vision deployment justifies itself when escape rates and rework fall. A maintenance deployment justifies itself when a line stops on schedule rather than unexpectedly.
Intuceo runs these engagements through its iPDLC delivery method, which moves from a scoped pilot to production on a defined path rather than an open-ended research effort, and usually proves value on a single line or asset class before extending to the logistics interface.

Find the first process worth automating

If you run an aerospace, defense, or industrial operation in Florida, the fastest route to a defensible result is to identify one defect-critical or downtime-critical process and scope it against your compliance boundary. Intuceo’s team will map that first use case with you and show what a controlled deployment looks like on your floor.

Frequently Asked Questions

The recurring ones are computer vision for quality control, predictive maintenance built on remaining useful life models, and natural language processing applied to maintenance logs for root-cause and downtime analysis. Because aerospace work involves controlled and export-controlled data, these are typically deployed on-site or in compliant environments, and often extended into inbound and outbound logistics through a supply-chain system such as Intuceo’s iTMS.
Sensors capture vibration, temperature, and acoustic data from high-value tooling or fleet assets, and models estimate remaining useful life to flag failures before they occur. This replaces calendar-based servicing with condition-based maintenance. For defense work, the models and telemetry must run inside a CMMC-compliant environment, since the data can qualify as controlled unclassified information.
Return shows up in the metrics a plant already tracks, such as overall equipment effectiveness, yield, scrap, and unplanned downtime, not in model accuracy alone. The strongest cases start where defects or stoppages already carry a measured cost and where usable data already exists, which shortens the path to a result that operations leaders can verify.
Begin with one defect-critical line that already generates inspection images or has cameras in place, so the model has history to learn from. Confirm the data-residency and CUI boundary before choosing where the model will run, then pilot it at the line, so decisions stay on-site and at production speed. Once escape and rework rates improve on that line, extend the approach to adjacent processes.
Yes, if the subcontract involves federal contract information or controlled unclassified information. CMMC requirements flow down to subcontractors at every tier, and any system that processes, stores, or transmits that data, including an AI model and its training pipeline, falls inside the assessment scope.
Yes. Vision and anomaly-detection models can run on edge hardware at the production line or on on-premise servers, so images and sensor data never leave the plant. This is often the default for aerospace and defense work that involves CUI or ITAR-controlled data.

Edge AI Visual Inspection: Why the Fastest Line Decisions Still Belong to Small Trained Models

Generative AI vision models can describe defects they have never seen, segment parts with a single click, and adapt to new variants without retraining. None of that helps if the answer arrives after the part has already moved to the next station. On a production line, a correct decision that arrives late has the same operational effect as a wrong one.
That is why, in edge AI visual inspection, small trained models still own the decision at the point of action. This is not a verdict against foundation models. It is a question of placement. This article explains where time is actually spent in an inspection decision, why compact models fit the fast path, and how larger models can still add value without sitting in the way.

Key Takeaways

What Is Edge AI Visual Inspection?

Edge AI visual inspection runs a computer vision model on hardware next to the camera, such as an industrial PC or embedded accelerator, to accept, reject, or divert parts without sending images to a remote server. It is built for decisions that must land within a single machine cycle.

How Much Time Does an Inline Inspection Decision Have?

Every inline inspection has a deadline set by physics. A part enters the camera’s field of view, gets imaged, and must be accepted, rejected, or diverted before it reaches the reject mechanism. That window depends on conveyor speed, spacing, and station layout.
Inference is only one slice of that window. The full chain includes:
When engineers discuss edge AI inspection latency, they mean the entire chain. A fast model sitting behind a slow network link still produces a slow decision.

Why Small Trained Models Fit Edge AI Visual Inspection

A small model trained for one inspection task does less work per image by design. It does not carry general knowledge about the world. It carries only what’s needed to separate good parts from bad on a specific station. That narrowness brings practical advantages :
The tradeoff is familiar. A small trained model knows only what it was taught. Change the part, supplier, or defect type, and it may need new examples and retraining.

Why Are Foundation Models Slower for Inline Inspection?

Foundation models earn their flexibility through size. Larger image encoders process more parameters for every frame, and many setups run additional language or decoding steps on top. That work takes compute and time, and the published numbers make the scale of it concrete.
The MobileSAM authors distilled the heavy image encoder of the original Segment Anything Model into a lightweight one. On a single graphics processing unit (GPU), the original encoder took 452 milliseconds per image against 8 milliseconds for the replacement, and the full MobileSAM pipeline runs at roughly 10 milliseconds per image. [1]
Two things follow :

Edge AI vs Cloud AI for Visual Inspection: Which Decisions Go Where?

The edge AI vs cloud AI question for visual inspection usually resolves by decision type rather than preference.
Decision type Best location Timing tolerance
Accept or reject within a machine cycle Edge, next to the station Milliseconds, with no network risk
Diverting a suspect part for review Edge or on-site server A short delay is acceptable
Describing an unusual defect for an engineer On-site server or cloud Seconds are fine
Labeling new images and retraining Cloud or data center No live timing constraint
Trend analysis across shifts and plants Cloud or data center Batch processing suits the task
The pattern is consistent. The closer a decision sits to physical action on the line, the more it belongs at the edge on a compact model. Academic work on edge-cloud co-inference supports the same split, with a small edge model handling routine inputs and a large vision model taking the hard cases. [2]

What Does Real-Time Visual Inspection Mean on a Production Line?

Real-time visual inspection means the decision reliably arrives before the latest moment the line can act on it, on every frame, including the slowest ones. Average inference speed hides variance, and a model that is usually fast but occasionally stalls will pass defective parts on exactly those occasions.
Sub-second defect detection sounds quick, and for offline or sampling checks it often is. On high-speed lines the available window can be a small fraction of a second once capture, transfer, and the reject signal are subtracted, so sub-second is a description rather than a standard. The only meaningful threshold is the one your own station geometry produces.

Where Do Foundation Models Add Value in Manufacturing Inspection?

How Do You Measure the Latency Budget of an Inspection Station?

Before choosing any model, work out how much time the line actually allows. A short exercise with operations and controls engineers usually answers it.
What remains is the real budget for inference. Many teams find it tighter than expected, which is why compact models remain the default for AI visual inspection in manufacturing at the point of action.
For example, if a conveyor moves at 1 meter per second and the reject gate sits 0.3 meters past the camera, the window is 300 milliseconds. Subtract capture, transfer, preprocessing, decision logic, PLC signaling, and a safety margin, and the inference budget may be well under 100 milliseconds. These figures are illustrative, so use your own station measurements.
To see where infrastructure and deployment still set these limits in production, watch the AI Dream Session, Vol. 2 recording.

What Is Model Distillation for Visual Inspection?

Model distillation is a training method that teaches a small model to reproduce a larger model’s outputs on a specific task. For inspection, a foundation model can help create the knowledge while a compact model delivers it at line speed. The small model inherits the teacher’s blind spots and still needs validation on real parts, but distillation remains one of the more practical bridges between flexibility and speed.
A vendor latency figure quoted without its conditions is worth little here. Ask what hardware it was measured on, at what image resolution, and whether it covers the full decision chain or inference alone.

How Intuceo Designs Edge AI Visual Inspection Systems

In every edge AI visual inspection project, Intuceo works backward from the decision deadline. The station geometry and the reject window set the constraint, and the model, hardware, and data flow are chosen to meet it, and not the other way round.
Two parts of that approach matter for latency work. Deployment is infrastructure-agnostic, spanning on-premise, edge, hybrid, and air-gapped environments, so a model can sit where the timing requires rather than where a vendor’s hosting model dictates.
The systems are maintained through production-grade MLOps practices built for regulated settings: containerized serving with shadow deployment and canary rollouts, so a candidate model can be timed against the incumbent on live line data before it is given authority, plus drift monitoring with automated retraining triggers for when parts and conditions move.
That combination is how Intuceo supports real-time defect root cause analysis without impeding the production line. See how this applies across advanced manufacturing and to the DataOps and AI/ML Ops capability  behind it.

Watch : Computer Vision Reimagined, On Demand

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute session with Intuceo AI Labs, now available on demand. It covers how infrastructure and deployment still shape what computer vision can do in production, building on the DARWIN Framework from Vol. 1.

Frequently Asked Questions

It is the use of a compact computer vision model running beside the camera on a production line, so accept, reject, or divert decisions happen locally within the machine cycle, with no network dependency. Larger models can still support slower tasks such as exception review and labeling.
Sometimes, but often not at the point of action on a fast line. Large generative AI vision models perform more computation per image, and many inspection windows are short once image capture, transfer, and the reject signal are included. Lighter distilled derivatives are closing the gap, so the answer depends on measuring worst-case timing on your own hardware at production resolution.
Use a small trained model when the decision must happen within a machine cycle, the defect list is stable, image volumes are high, and the system must keep running without a network. Foundation models suit slower tasks such as exception review, labeling, handling new variants, and offline analysis.
Edge deployment removes network delay and dependency but limits how much compute is available, which favors compact models. Foundation models can run on larger on-site servers or in the cloud, gaining flexibility but adding transfer time and more computation per image. Many plants place fast accept-or-reject decisions at the edge and route uncertain cases to larger models.
Generative AI is more flexible, not universally better. On a fixed inspection task, the qualities that decide deployment are speed, timing consistency, cost per image, and how straightforward the model is to validate for an auditor. Recognizing unfamiliar objects matters less at the point of action than meeting the deadline every time. The strongest systems combine both.
Measure the travel time between the camera and the reject point, then subtract capture, transfer, preprocessing, decision logic, and PLC delays, and keep a safety margin. What remains is the inference budget, which should be tested against worst-case timing rather than averages.

Supply Chain AI in Florida: How Ports, Logistics Hubs, and Transportation Leaders Are Cutting Lead Times

The 2026-2030 Florida Seaport Mission Plan, published by the Florida Seaport Transportation and Economic Development Council, directs investment toward dock rehabilitation, capacity expansion, cargo container handling and connectivity across the state’s publicly owned seaports. Physical throughput is being funded. The sequencing logic above it is not being funded at the same pace, and that is where most delay now accumulates.
For anyone evaluating supply chain AI in Florida, the starting point is this: lead time in a freight network rarely disappears at one point. It leaks across handoffs: vessel to yard, yard to gate, gate to drayage, drayage to distribution center, distribution center to customer.
Each handoff carries its own system of record, reporting cadence, and definition of an exception. By the time a planner identifies the problem, the cost is booked. That gap is what Florida operators are now adopting AI to close.

Key Takeaways

Where does lead time leak in Florida freight networks, and how do you measure it?

The Bureau of Transportation Statistics runs the Port Performance Freight Statistics Program, which publishes nationally consistent measures of capacity and throughput for United States seaports, including containership and tanker berthing times updated weekly. [2] It gives operators an external reference point for berth performance.
To measure lead-time leakage before modeling, timestamp each handoff, calculate the median and 90th percentile wait at each one, and rank handoffs by the cost of delay.
Mechanization raises the ceiling. PortMiami has been expanding the fleet of electric rubber-tired gantry cranes at its South Florida Container Terminal, allowing higher container stacking and shorter runs within the yard.
More cranes increase how many moves are possible in an hour. Whether those moves happen in the right order, against the right truck appointments, is a different question that AI for Florida ports is positioned to answer.
Dwell time, the time a container sits in the terminal between discharge and pickup, falls when three things line up: the yard knows which container is wanted next, the gate knows which truck is arriving to collect it, and the carrier knows before arrival whether the slot still holds. Each of those is an AI prediction problem sitting on data that already exists in terminal operating systems, electronic data interchange feeds, and telematics streams.

How does Florida's 2026 data center law (SB 484) affect supply chain AI?

Florida enacted CS/CS/SB 484 as Chapter 2026-65, with most provisions effective July 1, 2026. [4] The law requires the Public Service Commission to implement tariff and service requirements ensuring that large load customers such as large data centers pay their own cost of service, with the risk of nonpayment kept off the general body of ratepayers.
Utilities were required to file conforming tariffs for approval by October 1, 2026. The law also bars any tariff, contract, or utility policy from preventing or hindering curtailment of service to a large load customer when it is necessary to maintain grid stability or protect public safety during emergencies, and prohibits service to large load facilities owned or controlled by foreign countries of concern. [5]
Two consequences follow for anyone deploying Florida logistics AI.
Provision What it means for AI buyers
Large load customers, such as large data centers, must pay their own cost of service. Inference becomes a priced, visible operating line rather than an assumption. Designs that call a large model for every event will carry a different cost profile in Florida than they did in a vendor demonstration.
Tariffs and contracts cannot prevent curtailment of service to large loads during grid emergencies. Compute hosted in-state is explicitly interruptible during grid emergencies. Grid emergencies in Florida cluster in storm season, precisely when routing, diversion and inventory decisions carry the most value.
A decision layer that stops working when the weather turns is worse than no decision layer, because operators will have stopped maintaining the manual process it replaced.
Design implication: keep the models that must survive a disruption small, local and deterministic in their fallback. Reserve heavier reasoning for planning cycles that can tolerate a pause.

Does Florida regulate AI? Why procurement contracts carry the governance load

The proposed Artificial Intelligence Bill of Rights was designed to impose conditions on government contracts for AI technology. It cleared the Senate in March 2026 and then died in the House. [6] A second attempt during the April special session cleared the Senate again and died in House subcommittee the following day. [7]
Florida’s port authorities are governmental entities, which puts their AI vendors in the same position as other Florida government contractors. In the absence of a statutory standard, the obligations a buyer wants have to be written into the contract, not inherited from the code.
For Florida buyers of transportation analytics, four contract terms are worth insisting on:
Vendors should read the same signal in reverse. An offering built around accuracy claims alone is harder to defend to a Florida public sector buyer than one built around evidence. Reshaping a service line to lead with explainability, integration commitments, and exit terms is now a commercial advantage rather than a compliance overhead.

Where should supply chain AI in Florida start? Four decisions to automate first

Most Florida operators do not need a network-wide program. They need to get four decisions right :

Demand and inventory positioning

Forecasting that harmonizes historical movement with live market signals changes where stock sits before the order arrives. This is the core of Florida distribution center analytics: fewer emergency freight bookings, less inventory held against uncertainty, and replenishment triggered by a signal rather than a calendar.

Procurement and dispatch

Carrier selection, share-of-business allocation and container utilization are optimization problems with clear constraints. Routing intelligence that removes empty running takes cost out without touching headcount or assets.

Multi-modal visibility

Rail, road and sea data arrive in different formats on different clocks. A single reconciled record per shipment is the prerequisite for everything else, and it is usually the hardest part of the build.

Freight audit and billing reconciliation

Invoice and proof-of-delivery matching recovers money that is already owed. It is the fastest route to a defensible return, and it builds the internal credibility needed for the larger work.
Intuceo, a Jacksonville-based enterprise AI consultancy, built its iTMS supply chain accelerator to address these four as connected modules, with supervisory agents monitoring forecasting, planning, and execution.
Across deployments, Intuceo reports a 30% increase in forecasting accuracy and billing reconciliation accelerated by 40%. The accelerator is deployed as a layer over existing enterprise resource planning and electronic data interchange estates rather than a replacement for them, which matters in Florida, where mainframe and legacy carrier integrations remain in daily service.

Why Jacksonville matters for port, rail, and logistics AI

Northeast Florida is where sea, rail and highway freight converge most tightly. The Jacksonville Port Authority (JAXPORT) runs its cargo terminals in the same city as Class I rail headquarters, which puts the handoff between sea and rail inside one metropolitan area.
Conversations about logistics AI in Jacksonville therefore tend to start at the interchange rather than at the berth, because a container that clears the terminal quickly and then waits on a rail slot has not saved anyone a day. Intuceo is headquartered in Jacksonville and has delivered supply chain and transportation work for operators including CSX and the MTA Long Island Rail Road (LIRR). Proximity matters: the data that makes these models work is held by yard supervisors, dispatchers, and billing clerks, and it can be extracted much faster in person than over a call.

How to choose a supply chain AI consulting partner in Florida

Put a number on where your lead time goes

Intuceo’s supply chain diagnostic baselines one lead-time metric in your Florida network, identifies where it leaks across handoffs, and returns a costed plan to close it within 90 days.

Frequently Asked Questions

The applications with the clearest effect are berth and yard sequencing, gate appointment matching, and predicted container availability shared with drayage carriers before they arrive. Each one shortens the interval between a container becoming available and a truck collecting it. Capital investment in yard equipment raises the number of moves that are physically possible; sequencing intelligence determines how many of them are the right moves.
Supply chain AI in Florida is typically bought in one of three forms: modules inside an incumbent transportation management system, standalone visibility services, or accelerator-led engagements from services firms that build on top of existing systems. The third suits operators with substantial legacy integration, since it avoids a migration. Intuceo’s iTMS accelerator sits in that category, covering forecasting, dispatch, multi-modal visibility and freight audit as connected modules.
AI helps Florida distribution centers manage inventory in real time by replacing periodic stock reviews with continuous signals. Demand models informed by inbound vessel schedules, order patterns and carrier performance indicate what should be positioned where, and how much buffer is genuinely required. The practical result is fewer expedited shipments and less capital held against uncertainty, with exceptions surfaced while they can still be acted on.
There is no single best platform; the best fit depends on the systems you already operate. Buyers running modern cloud systems can often extend them. Buyers running mainframe, legacy electronic data interchange or long-standing carrier integrations, which describes much of Florida’s rail and port ecosystem, generally get further with a services-led engagement that layers intelligence over those systems. Evaluate AI consulting partners in Florida on integration record, explainability, time to a measurable result, and their willingness to commit to a defined first metric.
Not as of this writing. Florida has no general AI statute. The proposed Artificial Intelligence Bill of Rights, which would have set conditions on government AI contracts, passed the Senate twice in 2026 but died in the House both times. Buyers, including port authorities, have to write explainability, data residency, and audit requirements into contracts.
Intuceo scopes its supply chain diagnostic to deliver a baseline and costed plan within 90 days, and iTMS deployments typically reach a live pilot with measurable ROI in about 90 days.

Zero-Shot Segmentation in Manufacturing: What It Can and Cannot Do

Segmentation has long been one of the most labor-intensive steps in a vision project. Every defect, component edge, or region of interest had to be outlined by hand, pixel by pixel, often across thousands of images.
Promptable foundation models changed that cost structure, at least in principle. An object can now be pointed at, or described, and a mask returned without task-specific training.
The question for quality and engineering teams is how much of that holds up on a real line. While zero-shot segmentation in manufacturing is useful for a defined set of jobs, it is unsuitable for others. This guide separates the two, explains why, and sets out a practical way to test it before anyone commits budget.

Key Takeaways

What zero-shot segmentation means in industrial inspection

Segmentation assigns each pixel in an image to a region: this area is the part, that area is a scratch, the rest is background. Traditional segmentation models learn those regions from hand-drawn masks on the exact task they will perform.
Zero-shot segmentation skips that task-specific training. A foundation model pretrained on a very large, general dataset is prompted at runtime with a point, a bounding box, or, in some setups, a text description, and returns a mask. The best-known example is Meta AI Research’s Segment Anything Model (SAM). Its authors assembled a dataset of over 1 billion masks on 11 million licensed images and trained the model to be promptable so that it transfers zero-shot to new image distributions and tasks.
That scale is the reason the approach generalizes. It is also the reason for caution. None of those images were taken on your line, under your lighting, of your product parts.

Where zero-shot segmentation performs well

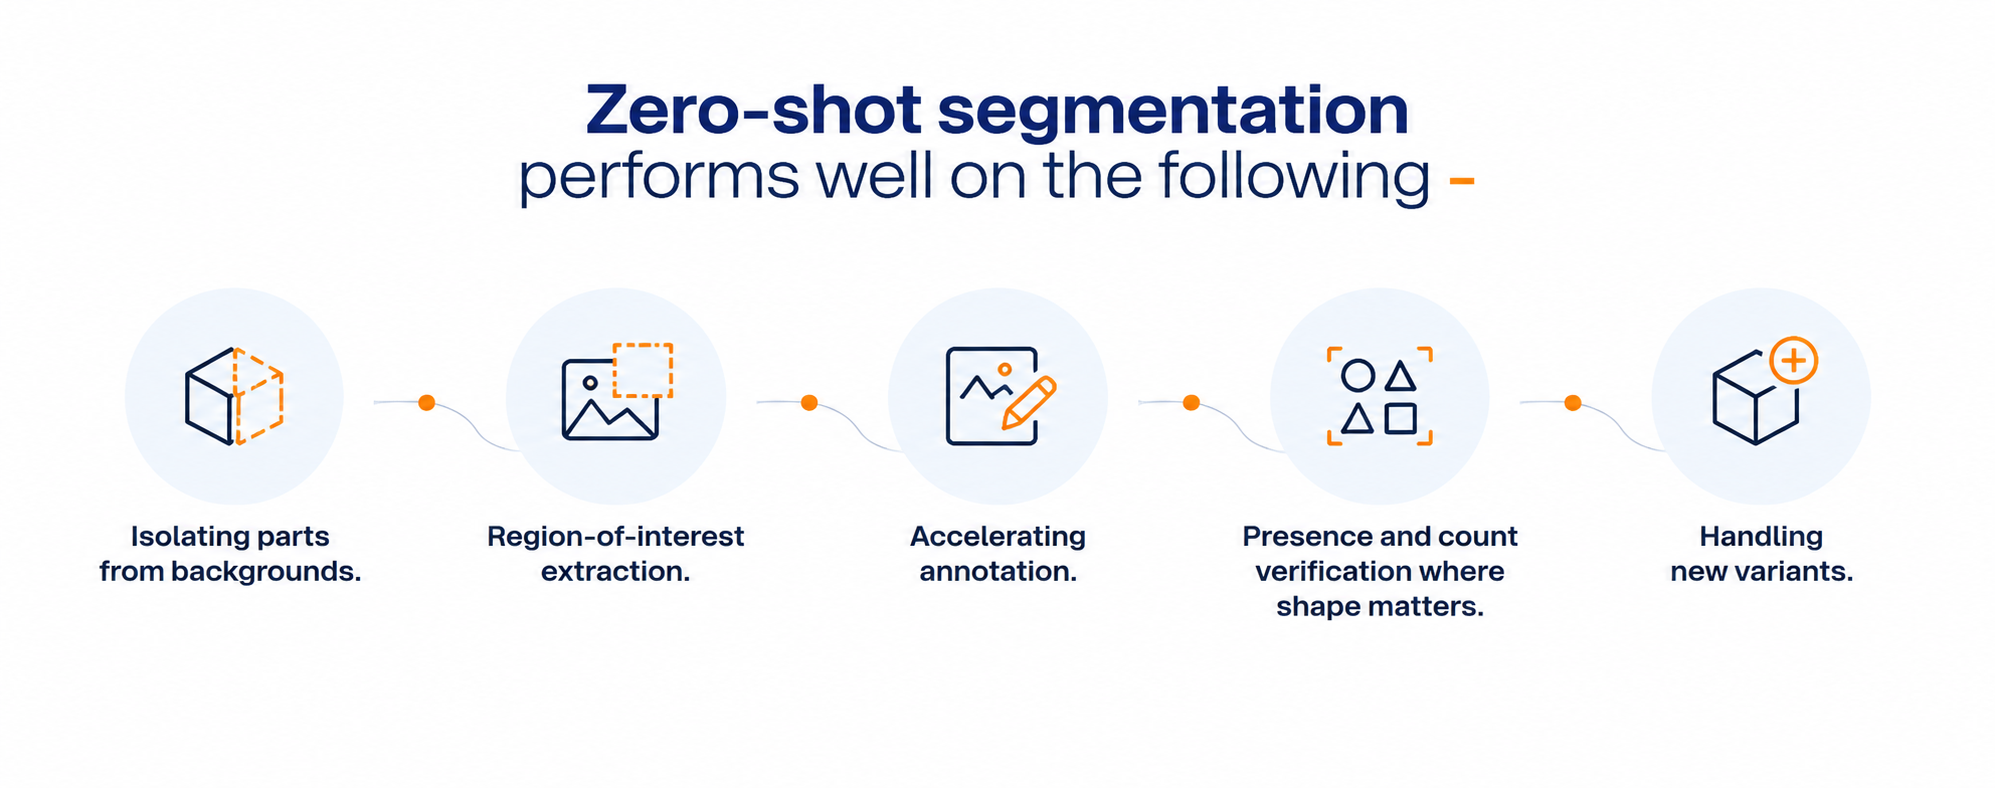
The strongest fits share one trait: the region being segmented is visually distinct from its surroundings.
In each case, the model performs localization. It reports where something is. A separate step decides whether that something is acceptable.

Where zero-shot segmentation is unreliable

The limitations map closely onto the defect types manufacturers care about most.

Fine and low-contrast defects

Hairline cracks, micro-scratches, faint discoloration, and subtle porosity often lack clear edges. The SAM authors state that the model can miss fine structures, sometimes generates small disconnected components, and does not produce boundaries as crisply as more computationally intensive methods.[1] On a production line, a missed hairline crack is not a small error to be overlooked.

Acceptance criteria

A mask is not a verdict. The model can outline a mark on a surface without any sense of whether that mark is cosmetic, within tolerance, or cause for rejection. Acceptance criteria live in your quality system, not in a general-purpose model.

Consistency across imaging conditions

Glare, reflective metal, transparent packaging, and shifting ambient light can change results from one frame to the next. The absence of task-specific training does not reduce a model’s sensitivity to imaging conditions.

Speed at line rate

Large foundation models are computationally heavy. Where a decision must be made inside a single machine cycle, the full model may not keep pace without dedicated hardware or a lighter distilled version.

Zero-shot detection vs. segmentation: which does your inspection need?

The two terms are often blended, and the difference affects system design. Zero-shot detection in industrial inspection draws a box around a candidate and assigns a label. Zero-shot segmentation draws the outline. Detection is usually sufficient for presence, position, and counting, and it costs less to run. Segmentation earns its additional compute when shape, area, or boundary precision matters, such as measuring a coating gap or the extent of a surface defect.
Aspect Zero-shot detection Zero-shot segmentation
Output A box and a label A pixel-level outline (mask)
Best for Presence, position, and counting Shape, area, and boundary precision
Compute cost Lower Higher
Example Confirming a part is present Measuring a coating gap or defect extent
Teams often chain the two. An open-vocabulary detection model locates candidate regions from a text prompt in production, and a segmentation model outlines what sits inside each box.

Where does the Segment Anything Model (SAM) fit in manufacturing workflows?

The roles above differ mainly in how much human judgment sits between the mask and the decision, and that is what should order a SAM manufacturing rollout. Exploratory analysis of archived images carries no line risk, because nothing reaches production. Annotation assistance comes next, because an engineer approves every mask before it becomes training data. Preprocessing follows, since a trained classifier still makes the call on the cropped region.
A fourth role, treating the model as the final accept-or-reject authority, is where most disappointment occurs. It is rarely the right starting point.

How do vision-language models and segmentation models work together?

Foundation models for visual inspection increasingly work as a set rather than alone. A vision-language model can be asked whether an image shows anything unusual and to describe it. A segmentation model then outlines the region it points to. That pattern is behind most current interest in vision-language models for defect detection, particularly for unfamiliar anomalies. It also stacks two sources of uncertainty, so validation on your own images matters more.

How do you test zero-shot segmentation on your production line? 7 steps

A short, structured test answers most questions before a full project starts. Seven steps cover the ground.
  1. Assemble a hard evaluation set: Include your subtle defects, reflective parts, and worst lighting, not only clear examples.
  2. Define success in operational terms: Mask overlap scores are useful, but the decisive question is whether the mask would lead to the right part disposition: accept, rework, or reject.
  3. Compare prompt types: Points, boxes, and text prompts behave differently. Test the one you would actually use in production.
  4. Measure speed on target hardware: Benchmark on the device that would sit near the line, not a research workstation.
  5. Repeat across shifts and variants: Run the same prompts on images from different shifts, operators, lighting states, and a recent part variant, to see whether performance holds without adjustment.
  6. Record how it fails, not only how often: A model that misses in predictable ways is easier to manage than one that fails at random, and a clear list of what it misses is as valuable as an accuracy score.
  7. Check review time and traceability: If reviewing uncertain masks takes longer than manual inspection, the workflow needs redesign. Record model version, prompt, and image for each output so decisions can be audited later, a standard practice in production MLOps pipelines.
If a zero-shot model performs well only after heavy prompt tuning on a handful of images, run the same prompts on a fresh batch before trusting the result. Overfitting prompts is easier than it looks.

When should you move from zero-shot to a fine-tuned model?

Move beyond zero-shot when fine defects dominate, tolerances are tight, or decisions must be made within a machine cycle. Zero-shot segmentation for industrial inspection is often the fastest way to learn whether a computer vision inspection project is tractable, but it is not always the final answer. In those cases, the usual next step is fine-tuning on a modest set of your own images or distilling results into a smaller model.

How Intuceo approaches segmentation work

Intuceo starts with the inspection decision the business needs, then works backward to whether segmentation, detection, or a simpler rule is the right tool. Scope your inspection use case with an AI architect.

Two capabilities carry most of the delivery on vision work. High-fidelity visual inspection applies image segmentation, sub-pixel anomaly detection, and automated feature extraction to sub-millimeter defects, including precision medical optics, where surface anomalies, edge irregularities, and contaminants have to be caught at production speed. Multi-modal vision intelligence brings video, image, and metadata streams together so inspection results arrive alongside line system signals rather than in a separate console.

Deployment is the part that has to survive audit. Intuceo delivers in on-premise, private cloud, and air-gapped environments, driven by PhD-led engineering teams with prior deployments in regulated and high-precision environments. See how this applies across AI-driven advanced manufacturing and to the ML and computer vision capability built for it.

Join AI Dream Session, Vol. 2: Computer Vision Reimagined

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute live session with Intuceo on Thursday, September 24, 2026, at 11:00 AM ET. It covers how newer vision models reduce dependence on large labeled datasets, and where accuracy and production conditions still create hard problems.

Frequently Asked Questions

It is the ability to outline objects or regions in an image using a pretrained foundation model, guided by a prompt such as a point, box, or text description, without training on your specific parts. In inspection, it is most often used to isolate components, extract regions of interest, and speed up labeling, rather than to make final quality decisions on its own.
Not entirely. They can sharply reduce the labeling needed to get started and can pre-label images for engineers to correct. You still need a labeled evaluation set from your own line to confirm performance, and many subtle defect types still benefit from fine-tuning on examples specific to your process.
Four limits dominate: weak performance on fine or low-contrast defects, no built-in understanding of acceptance criteria, sensitivity to glare and lighting changes, and heavy compute requirements for large models.
Yes, in well-chosen roles: annotation assistance, preprocessing that isolates parts or regions, and exploration of archived images. Using them as the sole accept-or-reject authority is riskier.
Not always. Large foundation models are computationally heavy, so decisions inside a single machine cycle may need dedicated hardware or a smaller distilled model.

Life Sciences AI Consulting in Florida

Most life sciences teams evaluating an analytics partner are not shopping for artificial intelligence (AI). They have a specific bottleneck: enrollment is behind on two studies, safety case intake is absorbing headcount that should be doing signal evaluation, or ten years of research data sits in systems nobody can query. The question is which firm can fix that under inspection conditions.
Intuceo delivers life sciences AI consulting in Florida as a services engagement, configuring analytics against the sponsor’s own systems, validation expectations, and quality procedures, using accelerators built during prior regulated engagements rather than starting each build from zero.

What Life Sciences AI and Analytics Services Does Intuceo Provide in Florida?

Five areas of work account for most life sciences engagements. Each one is scoped, validated, and handed over with documentation the quality team can defend.

Clinical trial intelligence

Site and country feasibility modeling from historical enrollment and real-world data, patient cohort identification against provider datasets, protocol deviation detection, and automated query generation on Electronic Data Capture (EDC) records. Clinical trial intelligence, the use of AI and real-world data to model feasibility and flag risk before it delays a study, helps sponsors and Contract Research Organizations (CROs) shorten startup and reduce manual data review cycles. This is the same approach behind Intuceo’s AI-powered patient matching for clinical trials, which cut enrollment delays by half.

Pharmacovigilance and safety automation

Individual Case Safety Report (ICSR) intake and triage from unstructured sources, Medical Dictionary for Regulatory Activities coding assistance, duplicate detection, narrative drafting for reviewer approval, and Pharmacovigilance System Master File (PSMF) annex assembly with change control. Pharmacovigilance automation, the use of AI to handle these safety case tasks, is configured to keep the qualified person accountable for every decision the system proposes.

Post-market adverse event detection

Disproportionality and temporal signal detection across spontaneous reports, literature, and provider records, with case-level traceability back to the source document. United States marketing applicants must report each adverse drug experience that is both serious and unexpected within 15 calendar days of receipt,[1] which makes intake speed and audit trail quality inseparable requirements. This is the same detection and traceability approach behind Intuceo’s adverse event detection deployment for a global pharmaceutical manufacturer.

Research and development acceleration

Semantic search across internal study reports, assay data, and regulatory correspondence, the same advanced analytics in pharma R&D approach Intuceo has applied to drug discovery, so scientists retrieve prior work instead of repeating it. Target and biomarker literature triage, experiment metadata harmonization, and machine learning (ML) models on preclinical datasets, each with the reasoning path documented for scientific review.

Pharmaceutical manufacturing analytics

Batch genealogy, golden batch comparison, yield and deviation root cause analysis, and Corrective and Preventive Action (CAPA) linkage across manufacturing execution and laboratory systems. Useful where yield variance and repeat deviations are documented but not explained. This mirrors the ML-based inspection pipeline Intuceo built for medical device manufacturing.

Regulatory document intelligence

Extraction and classification across submission dossiers, standard operating procedures, batch records, and Trial Master File content. Reviewers get structured fields and a link to the exact page the value came from, which is what shortens a document review rather than a summary they cannot verify.

What AI Accelerators Power Intuceo's Life Sciences Engagements?

These are internal assets brought into an engagement to shorten deployment, not licensed software. They are configured against the client’s data, environment, and validation requirements.
Accelerator Applied to
Intuceo-Ax™ Analytics acceleration across clinical, safety, and manufacturing datasets, including cohort building and yield analysis.
Intuceo-Ix™ Semantic and neural search over study reports, literature, and regulatory correspondence for research retrieval.
Intuceo-Dx™ Document and vision intelligence for batch records, safety source documents, submission content, and scanned archives.
AgentCare AI Agentic workflows for case intake, triage routing, and CAPA follow-up, with human approval gates at each decision point.
iPDLC™ Delivery lifecycle framework governing documentation, testing evidence, and handover for validated environments.
DARWIN framework Structured assessment across data, architecture, responsibility, workflow, and infrastructure readiness before build begins.

Why Should Florida Life Sciences Companies Choose a Florida-Based AI Consulting Partner?

Intuceo is headquartered in Jacksonville. For validation-heavy work, that changes the shape of an engagement in ways that matter more than they do in most software categories. Read more about why Intuceo is based in Jacksonville.

What Life Sciences and Healthcare Experience Does Intuceo Bring?

This experience is the foundation of Intuceo’s life sciences AI consulting in Florida: data engineering and analytics work for pharmaceutical manufacturers, medical device firms, health systems, and payers operating under audit.

Pharmaceutical and device

Janssen Pharma, Ferring Pharma, and Bausch & Lomb, spanning clinical data, safety operations, and manufacturing analytics.

Florida health systems and payers

Florida Blue, GuideWell Health, UF Health, Mission Health, and d2i, where provider and claims data supports real-world evidence work. This work runs alongside Intuceo’s broader healthcare analytics practice for Florida payers and providers.

Regulated delivery discipline

Doctorate-led technical oversight, explainable model outputs, and testing evidence produced as part of delivery rather than assembled afterward. Meet the PhD-led team behind this oversight.

Data engineering depth

Long-running life sciences data engineering work integrating laboratory, clinical, manufacturing, and claims systems, the same data foundation covered in Intuceo’s DataOps and engineering capabilities, which is usually the constraint before any model is built.

How Does a Life Sciences AI Consulting Engagement with Intuceo Start?

Structured assessment

A two- to three-week review of the target workflow, source systems, data quality, and validation expectations, using the DARWIN framework. Output is a scoped plan with effort, dependencies, and evidence requirements.

Configured pilot

One workflow built on real client data with the relevant accelerator configured, run against defined acceptance criteria and reviewed by the quality function before scope expands.

Validated rollout

Extension to additional studies, sites, or facilities with documentation, testing evidence, and knowledge transfer delivered under iPDLC™ governance.

Start Life Sciences AI Consulting in Florida with Intuceo.

Partner with Jacksonville-based engineers to configure validated AI accelerators against your own systems, shorten trial cycles, and automate compliance under strict inspection conditions.

Frequently Asked Questions

Prior engagements include Janssen Pharma, Ferring Pharma, and Bausch & Lomb on the pharmaceutical and device side. Adjacent healthcare work includes Florida Blue, GuideWell Health, UF Health, Mission Health, and d2i, which is where much of the provider and claims data experience relevant to real-world evidence comes from. See results from a recent pharmaceutical commercial analytics engagement. Reference conversations can be arranged for shortlisted engagements, subject to client consent.

It compresses specific tasks rather than the trial as a whole. The measurable gains come from site and investigator selection informed by historical enrollment performance, cohort identification run against provider and claims data instead of manual chart review, automated detection of protocol deviations and data discrepancies in Electronic Data Capture systems, and coding assistance that leaves the final classification with a trained reviewer. Each of these reduces cycle time on a step that is currently manual. None of them removes the sponsor’s obligation to explain how a decision was reached.

The Pharmacovigilance System Master File is a detailed description of the pharmacovigilance system a marketing authorisation holder operates for its authorised medicines. It sits outside the marketing authorisation dossier and is maintained independently from it. It must stay permanently available for inspection at the site where it is kept, and a copy has to be submitted to a national competent authority or the European Medicines Agency within seven days of a request. Automation applies to the mechanics, not the accountability: pulling annex content directly from the source systems that generate it, maintaining version history and change logs automatically, flagging annexes that have drifted out of date, and holding the file in a state where a seven-day request is routine rather than a fire drill. The qualified person responsible for pharmacovigilance remains the owner of what the file says.

Yes. This work typically joins manufacturing execution, historian, and laboratory information management data to build batch genealogy, then compares underperforming batches against reference batches to isolate the parameters that moved. Deviation and CAPA records are linked to the same batch context so recurring root causes become visible instead of being closed one at a time. Equipment effectiveness and changeover analysis are usually part of the same scope.

Yes. Most delivery runs remotely, with onsite presence scheduled for the phases where it changes the outcome: the structured assessment, validation walkthroughs, quality reviews, and go-live. Because the team is based in Jacksonville and works on Eastern Time, Florida sponsors get same-day onsite availability without paying for a permanently deployed team.

Yes. Intuceo is headquartered in Jacksonville, and most onsite validation work for Florida life sciences clients happens there or within same-day reach of Gainesville, Tampa, Orlando, and South Florida.

Healthcare Analytics Consulting for Florida Payers and Providers

Intuceo is a Jacksonville-based firm delivering healthcare analytics consulting to Florida health plans and health systems. Engagements cover quality measurement, revenue cycle performance, and member risk, each built on encrypted, HIPAA-compliant data environments suited to regulated health data.
For Florida health plans and health systems navigating these changes, Intuceo’s healthcare analytics consulting team provides the data remediation and analytical infrastructure to move forward, governed by the iPDLC delivery lifecycle from scoping through production handoff. Request a scoping call

Engage Intuceo through

State of Florida

DMS term contract 80101507-23-STC-ITSA, valid through September 2027

Federal agencies

GSA Multiple Award Schedule 47QTCA24D00EH

Commercial

Direct master services agreements with health plans and health systems

Healthcare organizations Intuceo has delivered for

Why Florida Payers and Providers Are Turning to Healthcare Analytics Consulting

Florida Medicaid analytics and quality reporting work is being bought as remediation rather than experimentation. The measure logic and the regional reporting history both moved, and most reporting environments were never built to absorb either change.

7 measures added, 2 retired

Quality measure specifications were rewritten for 2026
HEDIS Measurement Year 2026 also moved four measures into Electronic Clinical Data Systems reporting and reissued specifications in a format aligned to the Fast Healthcare Interoperability Resources (FHIR) data standard.
Measure logic hard-coded over the last decade now needs re-validation.

11 regions to 9

Florida redrew its Medicaid reporting geography
Florida Medicaid analytics work changed materially when the state moved Statewide Medicaid Managed Care to nine lettered regions, A through I, in February 2025.[2] Regional trend lines break mid-history without a county-level crosswalk.

$21 billion

Administrative work remains largely manual
The 2025 CAQH Index puts the remaining industry savings opportunity from fully automating manual and partially manual administrative transactions at USD 21 billion.[3] Most of that opportunity sits in eligibility, authorization, and denials.

How Healthcare Analytics Consulting Is Scoped for Payers vs. Providers

Health plans and health systems ask different questions of different data, so the two are scoped independently. Intuceo has delivered on both sides, which matters as Florida payers and providers increasingly have to reconcile data with each other.

HEDIS and Star Ratings production

HEDIS analytics Florida work starts with measure calculation on a defensible data lineage – the same foundation Intuceo has built for Florida Blue, GuideWell Health, and UF Health – with the audit trail a certified compliance auditor will ask for already in place. Gap-in-care analysis runs off the same lineage, not a parallel extract.

Quality of care oversight

Predictive models rank which open care gaps are still closable inside the measurement period and which members are reachable, so outreach spend lands where it moves at a rate.

Member high-utilizer analytics

Clinical Risk Group classification across claims, pharmacy, and encounter data separates members with a single expensive year from complex chronic cohorts whose trajectory is still movable.

Potentially preventable events

Tracking of preventable admissions, readmissions, and complications to isolate where avoidable cost is generated and inform provider contracting. See how this works in our healthcare analytics consulting guide.

Encounter data validation

Validation and leakage detection for self-funded employers and labor funds, with reporting that holds up when a trustee asks how a number was produced.

Hospitals and health systems Margin, capacity, and clinical risk

Denial prediction

Revenue cycle management (RCM) scoring in the pre-submission window, so claims likely to be rejected get corrected before they leave. RCM analytics Florida engagements are judged on days in accounts receivable, not dashboard adoption.

Coding validation

Assisted review against clinical documentation to catch specificity errors and mismatches that create audit exposure and slow reimbursement.

Chronic condition risk trajectories

Models that flag escalation early enough for intervention to change an outcome, with diabetes and cardiovascular cohorts dominating in this region.

Unified clinical view

Intuceo-Ix™ – part of Intuceo’s Modular AI accelerator suite – supports retrieval across electronic health records, home care documentation, and social determinants of health data, so a clinician view is assembled rather than rebuilt by hand.

Administrative workload reduction

Eligibility verification, authorization packet assembly from the record, and coding queries routed only where documentation is genuinely ambiguous.

What Is the Data Engineering Foundation for Healthcare Analytics?

Most analytics failures in this sector are ingestion and identity failures wearing a different label, which is why healthcare data engineering in Jacksonville work usually precedes any modelling. FHIR alignment carries more weight now that the HEDIS specification format has moved toward the same standard.

Real-time clinical pipelines

Ingestion of Health Level Seven (HL7) and FHIR claims and clinical streams as they arrive.

Identity resolution

Member and patient matching across claims, clinical, pharmacy, and eligibility sources.

Master data management

A consolidated record that quality reporting and revenue cycle models both draw from.

Regional crosswalks

County-level mapping between the eleven-region and nine-region structures so trend history reconciles.

How Intuceo Applies HIPAA, FISMA, and NIST 800-53 to Healthcare Engagements

Intuceo delivers HIPAA-compliant healthcare analytics to health plans and health systems under HIPAA, HITECH, FISMA, and NIST 800-53 requirements, with federal health work handled under the same security controls.
HIPAA | HITECH | FISMA | NIST 800-53 | SOC 2 TYPE II | ISO 9001:2015 | 21 CFR PART 11

What the controls look like in practice

Encrypted cloud and on-premise environments, role-based access control, automated audit logging, virtual private cloud flow logging, encryption at rest and in transit, and business associate agreements executed before Protected Health Information moves.

Questions worth asking your vendor

Who holds production access, how model inputs are logged, and what happens to Protected Health Information in a development environment. The answers separate delivery discipline from a page on a website.

Why Florida Health Plans and Health Systems Choose Intuceo for Analytics Consulting

A services firm, based in Jacksonville

Delivered from Jacksonville

Headquartered locally, with healthcare work delivered for Florida Blue, GuideWell Health, UF Health, and Mission Health.

PhD-led delivery teams

Delivery led by PhD-qualified data scientists, which is why teams get pulled into measure validation and model explainability questions.

Accelerators configured to your data

Intuceo-Ax™, Intuceo-Ix™, and Intuceo-Dx™ are configured against an organization’s own data to shorten deployment.

A governed delivery lifecycle

The iPDLC™ lifecycle framework governs how each engagement is scoped, delivered, and handed over to internal teams. Engagements are led by PhD-qualified data scientists with direct delivery history in Florida’s payer and provider markets, not advisory-layer consultants handing off to junior teams.

Four common starting points for a first engagement

The first deliverable in every engagement is a structured assessment rather than an installation. Solutions carried across from prior regulated engagements are adapted to the organization that is buying them.
Starting pointFirst phaseWhat changes
HEDIS MY 2026 readinessMeasure logic and value set review against the reissued specificationsRe-validated measure production with an audit trail before the reporting window
Broken regional reportingCounty-level crosswalk across the region restructureTrend reporting that survives comparisons spanning February 2025
Denial and A/R pressureDenial history consolidation and pre-submission scoring on the highest-volume payerCorrections made before submission instead of appeals afterward
Fragmented recordsIdentity resolution and consolidated record buildOne record that quality and revenue cycle work can both rely on

Find out what your data will support before you commit a budget

Most engagements begin with a problem an internal team has already tried to solve twice: a measure that will not reconcile, a denial rate that has not moved, or a regional trend line that broke in February 2025. Intuceo’s healthcare team will assess what your data can actually support, and say plainly where it falls short, before proposing any scope of work. Read how we approach healthcare analytics consulting.

Frequently Asked Questions

Yes. Engagements span health plans, managed funds, and self-funded employers on the payer side, and hospitals and health systems on the provider side, including Florida Blue, GuideWell Health, UF Health, Mission Health, and d2i. The two are scoped separately because they ask different questions of different data.
The Healthcare Effectiveness Data and Information Set is a standardized set of performance measures maintained by the National Committee for Quality Assurance, specifying exactly how a plan collects, audits, and reports clinical quality and member experience results. Identical specifications across plans are what make comparison possible. It matters commercially because results feed accreditation, Star Ratings, and quality-based incentives, and operationally because a measure calculated from an undocumented extract will not survive an audit regardless of how good the underlying care was.
Through delivery controls rather than a certification alone: encrypted environments, role-based access control, automated audit logging, encryption at rest and in transit, and multi-factor authentication. Business associate agreements are executed before any Protected Health Information is accessed, development work uses de-identified or synthetic data where the task allows it, and access is scoped to named individuals for the engagement duration.
Yes. Florida Blue and its parent organization GuideWell Health are both named among Intuceo’s healthcare clients. Florida Blue is the Blue Cross and Blue Shield licensee for Florida, so it is the same organization referred to as BCBS Florida. Engagement specifics are covered by client confidentiality and discussed under a non-disclosure agreement.
Payer analytics focuses on health plan performance: HEDIS measure production, Star Ratings optimization, member risk stratification using Clinical Risk Group (CRG) classification, and cost containment through Potentially Preventable Event (PPE) tracking. Provider analytics focuses on hospital and health system performance: revenue cycle management, denial prediction, clinical coding validation, and chronic condition risk trajectories. Both require a shared data engineering foundation, including HL7 and FHIR ingestion, identity resolution, and master data management, but each asks different questions of different data.

AI Consulting Services in Florida: Enterprise Buyer’s Guide

AI consulting services in Florida are professional services that help enterprises design, build, and operate artificial intelligence systems. A qualified Florida AI consulting partner covers strategy, data engineering, machine learning model development, MLOps, and regulatory compliance – with deep knowledge of Florida-specific data privacy law and government procurement requirements.
Florida has become one of the most active technology markets in the country, and choosing the right AI consulting services in Florida is no longer just a technical decision. It is a jurisdictional one. When an organization evaluates enterprise AI partners in the state, it is really weighing three things at once:
This guide covers the full picture. It walks through the state of the Florida market, the services that sit under the label of enterprise AI, how to separate a capable AI consulting company in Florida from a generalist, the government contract vehicles that matter for public-sector work, and the security and regulatory conditions specific to Florida.

Key Takeaways

Why AI Consulting Services in Florida Demand a Local, Compliant Partner

Florida is no longer a secondary technology market. It sits among the largest states for tech employment in the country and was among those projected for the biggest absolute gains heading into 2026, according to CompTIA’s State of the Tech Workforce analysis.
The concentration is not only in headcount. The Florida Council on Artificial Intelligence reports that 33 percent of funded Florida companies identified artificial intelligence as a primary business function in the first half of 2025, that the state ranks sixth nationally in venture capital deal value, and that more than 30 firms relocated or expanded into South Florida across 2024 and 2025. That density means Florida enterprises can now choose partners who work in their own time zone, in their own regulatory environment, and often in their own city.
The pull is partly economic. Technology wages in Florida run well above the state’s overall median, which has drawn both talent and corporate headquarters into the market. For an enterprise, that concentration means an AI partner in the state can staff a project with local specialists who already understand its healthcare payers, defense contractors, and logistics operators, instead of a remote team that has to learn the context first. Proximity shortens discovery, and shorter discovery lowers cost.
The term ‘AI Consulting Services in Florida’ now serves as a marker for vendors who understand local compliance, economic context, and hiring markets. A firm rooted in the state understands local hiring markets, the mix of healthcare, defense, logistics, and public-sector work that defines Florida’s economy, and the compliance obligations that a national vendor may treat as an afterthought. For buyers asking which AI consulting firms operate in Florida, the practical answer is a growing field, which makes knowing how to evaluate them more important than knowing that they exist.

What Enterprise AI Consulting Services in Florida Actually Include

Enterprise AI consulting is a set of connected disciplines, not a single deliverable. A capable practice moves an organization from an unstructured question – “where could AI help us?” – to a running system that the business relies on. The work falls into five areas, and a serious provider of AI consulting services in Florida operates across all of them rather than selling one slice.

AI strategy and advisory

This is the discovery layer. It aligns business objectives with technical feasibility, ranks candidate use cases by value and effort, and produces a roadmap the leadership team can fund. Done well, it kills weak ideas early and protects the budget for the two or three initiatives that will actually reach production.

Data engineering

Most AI programs stall on data, not algorithms. A data engineering consultant in Florida builds the pipelines, warehouses, and governance that make analytics and machine learning possible in the first place. This includes ingestion from legacy systems, cleaning and standardizing records, and modernizing the enterprise core so that models have reliable inputs. For organizations running SAP, Oracle ERP, or PeopleSoft, this often means bridging older systems to modern data layers before any model is trained.

AI analytics and augmented insight

Strong AI analytics services in Florida turn raw operational data into decisions. This covers descriptive dashboards, predictive models that forecast demand or risk, and augmented business intelligence that surfaces patterns a human analyst would miss. The point is not the chart. The point is that a manager can act on it with confidence, because the underlying method is sound and explainable.

Machine learning engineering and MLOps

Building a model is the easy part. Keeping it accurate, monitored, and compliant in production is where most projects fail. This discipline covers model development, deployment across cloud or on-premises environments, and the monitoring that catches drift before it reaches a customer or an auditor. It is the difference between a pilot that impresses in a demo and a system that survives its second year.

Accelerated delivery

The best firms do not rebuild everything by hand. They apply accelerators, which are reusable frameworks and methods refined across earlier engagements, to compress timelines. An accelerator is not a shortcut around rigor. It is prior experience, packaged so the same problem is not solved twice.

How to Choose an AI Consulting Company in Florida: Key Selection Criteria

Once a shortlist exists, the evaluation becomes a question of fit and evidence. A polished website tells you little. The signals below separate a dependable AI consulting company in Florida, the kind you can build a multi-year relationship with, from a vendor that will disappear after the pilot.
By leveraging reusable frameworks, firms can significantly compress project timelines compared to building from scratch.
What to check Why it matters
Domain depth in your sector An AI team that already understands healthcare data, regulated life sciences, or public-sector procurement moves faster and avoids costly rework. Ask for engagements in your specific industry, not adjacent ones.
Delivery beyond the pilot Many programs stall after a promising proof of concept. Confirm the partner has moved systems into full production and supported them afterward, not just delivered a prototype.
Reusable accelerators Firms that carry frameworks and prior solutions into a project compress timelines and reduce cost. Starting from zero every time is slower and more expensive.
Data governance discipline Under Florida law, how a partner handles personal and sensitive data is a liability question, not a technical detail. Governance maturity is now a selection criterion.
Contract vehicles For public-sector or federal work, GSA and State of Florida vehicles determine whether an agency can even buy from the firm. This is covered in detail below.
Flexible engagement models The ability to scale a team up or down, or to commit to a fixed-outcome deliverable, gives you control over risk and budget as scope changes.

Weigh total cost, not the day rate

The headline rate rarely predicts the total cost of an AI program. A cheaper team that starts every component from scratch, misreads the data early, and cannot support the system post-launch will usually cost more across the life of the work than a partner with accelerators and a track record. Ask how a firm blends onshore and offshore capacity, and how it prices a fixed-outcome deliverable versus an open-ended engagement. Transparent trade-offs are the sign of a mature firm you can plan a budget around.

Test the accelerators, do not just accept them

Accelerators are only an advantage if they are real and explainable. A reusable framework should come with a clear account of what it automates, where a human still makes the call, and how it was validated on prior work. Be wary of any method presented as a closed box that cannot be inspected, because that is precisely the kind of opacity Florida’s proposed AI rules are written to discourage. A good partner will walk you through the mechanics without hesitation.
A useful test is to ask the vendor about its staffing approach and how it priced the last three engagements. Firms that offer flexible arrangements, such as team augmentation, fixed-outcome projects, and managed service agreements, tend to be honest about trade-offs because they have structured for them. The right provider of AI consulting services in Florida treats every engagement as a long-term relationship built on delivered outcomes, not a single transaction.

Why Enterprise AI Programs Stall - and How a Florida AI Partner Prevents It

Most enterprise AI failures are not caused by the model. They are caused by predictable organizational gaps, and a partner that has seen them before is worth more than one selling the newest technique. Three patterns account for the majority of stalled programs.
The first is the pilot trap. A proof of concept impresses in a demo, then fails when it meets real data volumes, integration constraints, or user behavior at scale. The fix is straightforward: plan for production from week one. That means settling the data pipeline, monitoring setup, and system ownership before a model is trained – not after the pilot report is delivered.
The second is the data gap. Teams underestimate how much cleaning, standardizing, and governance the underlying data needs, so the project runs out of budget before it reaches value. This is where seasoned data engineering, brought in early, earns its fee by fixing the foundation instead of building on sand.
The third is the compliance surprise. A system is built for accuracy alone, then has to be rearchitected when a regulator expects human oversight of decisions that affect a person’s care, coverage, or livelihood. Designing that oversight from the start is far cheaper than retrofitting it. A Florida partner that treats the state’s rules as a design input, rather than a late obstacle, removes all three risks at once.

Florida AI Regulatory Compliance: Data Privacy, Oversight, and Contract Requirements

Florida has enacted specific rules governing data privacy and AI. Organizations procuring AI consulting services in Florida must understand three compliance layers: the Florida Digital Bill of Rights (Senate Bill 262), the proposed AI Bill of Rights (Senate Bill 482), and sector-specific healthcare and insurance restrictions.

Data privacy: the Florida Digital Bill of Rights

The Florida Digital Bill of Rights, enacted as Senate Bill 262, took effect on July 1, 2024, and gives Florida residents rights over how their personal data is collected and used. Enforcement sits with the Florida Attorney General, with civil penalties reaching up to 50,000 dollars per violation, and higher in defined circumstances. Separately, the Florida Information Protection Act already requires any commercial entity holding electronic data on Floridians to take reasonable measures to secure it and to follow breach-notification rules. An AI partner that ignores these obligations is transferring risk directly onto your organization.

Artificial intelligence: the proposed AI Bill of Rights

In December 2025, Governor Ron DeSantis proposed a Citizen Bill of Rights for Artificial Intelligence, filed as Senate Bill 482 for the 2026 legislative session. The proposal would require transparency when AI is used, restrict certain foreign-developed AI tools, limit the unconsented use of personal data, and set boundaries for AI in healthcare, insurance, and mental health services. Buyers should treat these directions as the near-term baseline even before final passage, because they signal where enforcement is heading.

Healthcare and insurance limits

The healthcare provisions are strict and specific. Under the proposal, AI could not serve as the sole basis for adjusting or denying an insurance claim, which reinforces a requirement for documented human review, and behavioral health AI tools would be barred from delivering licensed therapy or simulating a licensed professional. For Florida healthcare and life-sciences organizations, this means an AI partner has to design human oversight into a system from the start, not bolt it on after an audit. This is one reason buyers searching for the best data engineering company in Florida for healthcare should weigh regulatory fluency as heavily as technical skill.

The practical takeaway

Florida’s direction of travel favors partners that keep data inside controlled environments, document human oversight, and can attest to their ownership and provenance. A Florida-based partner with local operations and mature governance policies is easier to defend to a regulator than an opaque or offshore-only vendor.

What to require in the contract

Regulatory intent only protects an organization if it appears in the agreement. When contracting for AI Consulting Services in Florida, buyers should insist on a few specifics: written data-handling terms that state where personal data is stored and processed, documented human review for any decision that affects a person’s care, coverage, or employment, breach-notification commitments consistent with the Florida Information Protection Act, and a right to audit the models and data flows the partner builds. These clauses cost nothing to add and save a great deal if a regulator ever asks.

Florida Government AI Contracts: GSA Schedules and State Contract Vehicles

Public-sector AI work runs on a different track from commercial work, and the gate is procurement. Two questions dominate: are there AI vendors with GSA Schedule contracts based in Florida, and which companies hold State of Florida contract vehicles. Both determine whether an agency can buy at all.
A GSA Schedule, formally the Multiple Award Schedule, is a pre-negotiated federal contract that lets United States government agencies purchase vetted services without running a full procurement from scratch. It signals that a firm’s rates, terms, and past performance have already cleared federal review. State of Florida contract vehicles serve the same function at the state and local level, giving Florida agencies a faster, compliant path to engage an approved provider.
This matters more now because of a new contracting rule. Beginning July 1, 2026, Florida government entities would be barred from entering any contract with an AI provider unless the company signs an affidavit affirming it is not owned by a foreign country of concern. Public-sector buyers should confirm that a provider can execute that affidavit before award rather than after. A firm that is United States-domiciled, holds active government vehicles, and can sign it clears a bar that others will not, which narrows the field considerably. Intuceo, for instance, delivers data and AI engineering for federal and state agencies and academic institutions through its GSA and State of Florida contract vehicles, which places it inside this qualified group.

Where Florida AI Consulting Work Concentrates: Healthcare, Public Sector, and Manufacturing

Enterprise AI in Florida clusters around the sectors that define the state’s economy. The strongest providers of AI analytics services in Florida tend to specialize rather than spread thin.

Healthcare and life sciences

Florida’s large healthcare and payer market is both a major opportunity and the most regulated environment for AI in the state. Work here centers on clinical and operational analytics, patient data visualization, and models that keep a human in the loop by design. Intuceo has worked with the University of Florida Institute for Child Health Policy for more than two years on portals for visualizing healthcare data – an example of the sector-specific delivery healthcare organizations should expect from a qualified Florida AI consulting partner.
Organizations in the life sciences sector can review Intuceo’s life sciences AI and analytics capabilities for a detailed account of the regulatory and delivery approach.

Public sector and defense

Florida hosts a defense sector generating more than 100 billion dollars in annual economic activity and 20 military installations, according to the Florida Council on Artificial Intelligence. That scale drives demand for secure, contract-vehicle-eligible AI and data work, where provenance and compliance are non-negotiable.

Engineering, manufacturing, and supply chain

Optimization is the theme here : design optimization, predictive maintenance, and analytics that tighten logistics and transportation networks. These are areas where accelerators pay off quickly, because the underlying problems repeat across clients and a firm can carry proven methods from one engagement to the next.

Where Intuceo fits

Intuceo is an AI and analytics services firm headquartered in Jacksonville, Florida, operating under the iCube Consulting Services brand. It has delivered data and AI work for two decades, and reports more than 250 AI and data solutions delivered to Fortune 1000 enterprises, government bodies, and mid-market organizations across healthcare, life sciences, manufacturing, engineering, and the public sector. Its recognition includes multiple appearances on the Inc. 5000 list of fast-growing United States companies.
Three attributes line up with what the sections above describe as the markers of a dependable partner. First, its delivery is built on accelerators such as the iPDLC framework and AutoML methods, which the firm reports can cut delivery timelines by as much as 40 percent compared with building from scratch. Second, its engagement options, spanning team augmentation, fixed-outcome projects, and managed service agreements, give buyers control over cost and risk. Third, it is United States-headquartered and already cleared to sell to federal and state agencies, which matters directly under Florida’s tightening procurement rules.
For an organization evaluating AI Consulting Services in Florida, that combination of local presence, sector depth, reusable delivery methods, and government eligibility is exactly the profile the state’s market and regulations now reward. You can review the firm’s work and reach its solutions architects through the Intuceo website.

Planning an AI initiative in Florida?

For a side-by-side comparison of AI consulting firms operating in the state, see the Top AI Consulting Companies in Florida: How to Evaluate and Choose guide.
Whether the goal is a first data-engineering foundation, a production analytics system, or a public-sector engagement that has to clear procurement, a Florida-based partner shortens the path.
Organizations that prefer a structured first conversation can book an AI Dream Session – a focused strategy briefing with Intuceo’s solutions architects.

Frequently Asked Questions

Intuceo is headquartered in Jacksonville, Florida, but serves clients across the state and beyond. Its delivery model supports onsite and remote engagement, so organizations in any Florida metro can work with the firm without needing a local office nearby.
Yes. Intuceo delivers data and AI engineering for federal and state agencies and academic institutions using its GSA and State of Florida contract vehicles, which give government buyers a pre-vetted, compliant path to engage the firm.
The firm concentrates on healthcare, life sciences, manufacturing, engineering and automotive, supply chain and transportation, and the public sector, matching the industries that anchor Florida’s economy and its most regulated AI use cases.
Yes. Intuceo works with clients onsite and remotely, and its team operates from Florida, the Washington, D.C. area, and additional locations. Organizations in Tampa, Orlando, Miami, or elsewhere in the state can run a full engagement remotely.
Intuceo reports more than 250 AI and data solutions delivered over two decades and multiple Inc. 5000 listings. A documented Florida example is its multi-year work with the University of Florida Institute for Child Health Policy on portals for visualizing healthcare data.

What Are the Best AI Development Lifecycle Frameworks for Regulated Analytics?

An estimated 80% of enterprise AI projects fail to deliver their intended business value, according to RAND Corporation’s 2025 analysis. In regulated industries like life sciences and healthcare, the stakes are even higher. A flawed model does not just waste budget; it can trigger compliance violations, endanger patient safety, or invalidate years of clinical research.
The core issue goes beyond the algorithm; it is the absence of a structured AI development lifecycle framework that governs how models are built, validated, monitored, and retired. Traditional SDLC processes assume deterministic outputs. AI systems produce probabilistic results that require fundamentally different governance, from data provenance to drift detection to explainability. For life sciences organizations operating under FDA 21 CFR Part 11, HIPAA, and GxP, choosing the right AI lifecycle framework is foundational.

Key Requirements When Evaluating an AI Development Lifecycle Framework for Regulated Analytics

Before comparing specific frameworks, it helps to define what “regulated-ready” demands. These are the non-negotiable considerations for any AI lifecycle framework used in life sciences or healthcare analytics.
Requirement Why It Matters in Regulated Analytics
Audit-ready documentation FDA and GxP audits require immutable records of data lineage, model decisions, and validation steps at every stage.
Explainability (XAI) Regulators and clinicians need to understand why a model made a specific prediction, particularly in pharmacovigilance and clinical trial matching.
Hallucination and drift detection LLM outputs and ML predictions degrade over time. Production AI monitoring must detect statistical drift, output toxicity, and hallucination before they affect decisions.
Model version control Every model iteration, training dataset, and hyperparameter change must be versioned and traceable for 21 CFR Part 11 compliance.
Human-in-the-loop validation Non-deterministic AI outputs require expert review gates, especially where patient safety or regulatory submissions are involved.
Cross-regulation alignment A single framework should map to multiple mandates: HIPAA, FISMA, NIST 800-53, GxP, and GDPR simultaneously.
With these criteria established, which AI development lifecycle frameworks meet these standards?

Top AI Development Lifecycle Frameworks for Regulated Analytics: A Comparative View

1. NIST AI Risk Management Framework (AI RMF 1.0)

Released in January 2023, the NIST AI RMF has become the de facto AI governance standard in the United States, organized around four functions: Govern, Map, Measure, and Manage. NIST expanded it in July 2024 with a Generative AI Profile (AI 600-1) adding over 200 actions for LLM-specific risks.FDA and other sector regulators increasingly reference its principles.
Strengths
Limitations
Best for: Enterprises needing regulatory alignment across multiple mandates (HIPAA, FISMA, GxP) without being locked into a single vendor ecosystem.

2. CRISP-DM (Cross Industry Standard Process for Data Mining)

CRISP-DM has been the most widely adopted data science methodology since 1999. Its six-phase cycle (Business Understanding, Data Understanding, Data Preparation, Modeling, Evaluation, Deployment) provides a structured, iterative approach. Comparative research found CRISP-DM showed the highest alignment with ISO/IEC 29110 standards among the frameworks analyzed.
Strengths
Limitations
Best for: Teams needing a proven analytical workflow structure, supplemented with separate governance and MLOps layers for regulated environments.

3. Microsoft TDSP (Team Data Science Process)

TDSP extends CRISP-DM with a five-stage lifecycle and adds standardized deliverables, role definitions, and collaboration templates. Its customer acceptance phase and prescribed documentation make it more enterprise-ready than CRISP-DM.
Strengths
Limitations
Best for: Organizations already operating within the Azure/Microsoft ecosystem that need standardized data science workflows across large teams.

4. MLOps (ML Operations Lifecycle)

MLOps applies DevOps principles (CI/CD, infrastructure-as-code, automated testing) to machine learning. It emphasizes continuous integration, delivery, and monitoring of ML models in production, extending traditional frameworks with automated testing, version control, and drift detection.
Strengths
Limitations
Best for: Technically mature organizations that need to scale production AI monitoring and model governance across multiple deployed models.

5. iPDLC™ (Intelligent Product Development Lifecycle) by Intuceo

Where the frameworks above address parts of the AI lifecycle, Intuceo’s proprietary iPDLC™ was purpose-built for regulated, high-stakes environments. It integrates AI-augmented engineering with PhD-led quality gates at every milestone, governing the full lifecycle from intelligent discovery through hardened production to continuous governance.
iPDLC operates across five pillars: Intelligent Discovery and Requirement Synthesis, Architectural Blueprinting, Logic-Driven Test Engineering, Hardened Production Engineering, and Observability with Continuous Governance. Each pillar includes a mandatory Human-in-the-Loop checkpoint validated by Intuceo’s Board of Science, ensuring mathematical soundness and audit readiness.
Strengths
Limitations
Best for: Life sciences, healthcare, and public sector organizations that need a compliance-first AI lifecycle framework with built-in scientific oversight and production-grade reliability.

Framework Comparison at a Glance

Capability NIST AI RMF CRISP-DM TDSP MLOps iPDLC™
Regulatory compliance (native) Partial No No No Yes
Audit-ready documentation Guidance only No Templates Tool-dependent Automated
Explainability / XAI Recommended No No Add-on Built-in (PhD-led)
Drift detection & monitoring Recommended No No Yes Yes (self-healing)
LLM / GenAI evaluation Yes (AI 600-1) No No Emerging Yes
Human-in-the-loop gates Recommended Informal Customer acceptance Optional Mandatory (every pillar)
Vendor lock-in None None Microsoft Tool-dependent Cloud-agnostic

Need a Compliance-First AI Lifecycle for Life Sciences?

Intuceo’s iPDLC™ framework delivers production-grade AI with PhD-led oversight, automated audit trails, and native compliance for 21 CFR Part 11, HIPAA, and GxP environments. Reduce implementation timelines by up to 40% without compromising scientific rigor.

Frequently Asked Questions

A traditional SDLC assumes deterministic software outputs: identical inputs produce identical results. An AI development lifecycle must account for probabilistic outputs, continuous model retraining, data drift, and ongoing validation after deployment. Regulated environments add further layers of documentation, explainability, and version control that standard SDLC processes do not address.
Primary challenges include maintaining audit-ready documentation across model iterations, ensuring explainability for clinical reviewers, detecting drift and hallucinations in production, and aligning a single AI governance framework with overlapping mandates (HIPAA, GxP, 21 CFR Part 11, GDPR). Gartner predicts 60% of AI projects lacking AI-ready data will be abandoned through 2026.
Validation requires statistical testing, human-in-the-loop expert review, automated regression benchmarks, and continuous drift monitoring. In regulated analytics, every validation step must produce an immutable record. NIST AI RMF recommends ongoing measurement across trustworthiness attributes including reliability, safety, fairness, and explainability.
Evaluation starts with baseline benchmarks during development, followed by automated production monitoring. Drift detection compares statistical distributions of inputs and outputs over time. Hallucination evaluation uses ground-truth comparison and retrieval-augmented verification. Toxicity is measured through classifier-based filters and human review. NIST’s Generative AI Profile (AI 600-1) provides over 200 specific actions for managing these LLM risks.
For life sciences, a combination approach works well: NIST AI RMF for governance structure, MLOps tooling for production monitoring, and a compliance-native methodology like iPDLC™ that embeds regulatory checkpoints into every stage. No single open framework currently covers the full spectrum from discovery through governed production in regulated environments.