Enterprise data teams are being asked to deliver two things from one stack: trusted business intelligence for finance and operations, and reliable training data, features, and retrieval context for machine learning and generative AI. The warehouse-plus-lake split that most organizations inherited was never designed to carry both. In practice, that shows up as duplicated data across systems, governance scattered across tools, and compute spend climbing faster than the model teams it is supposed to serve.
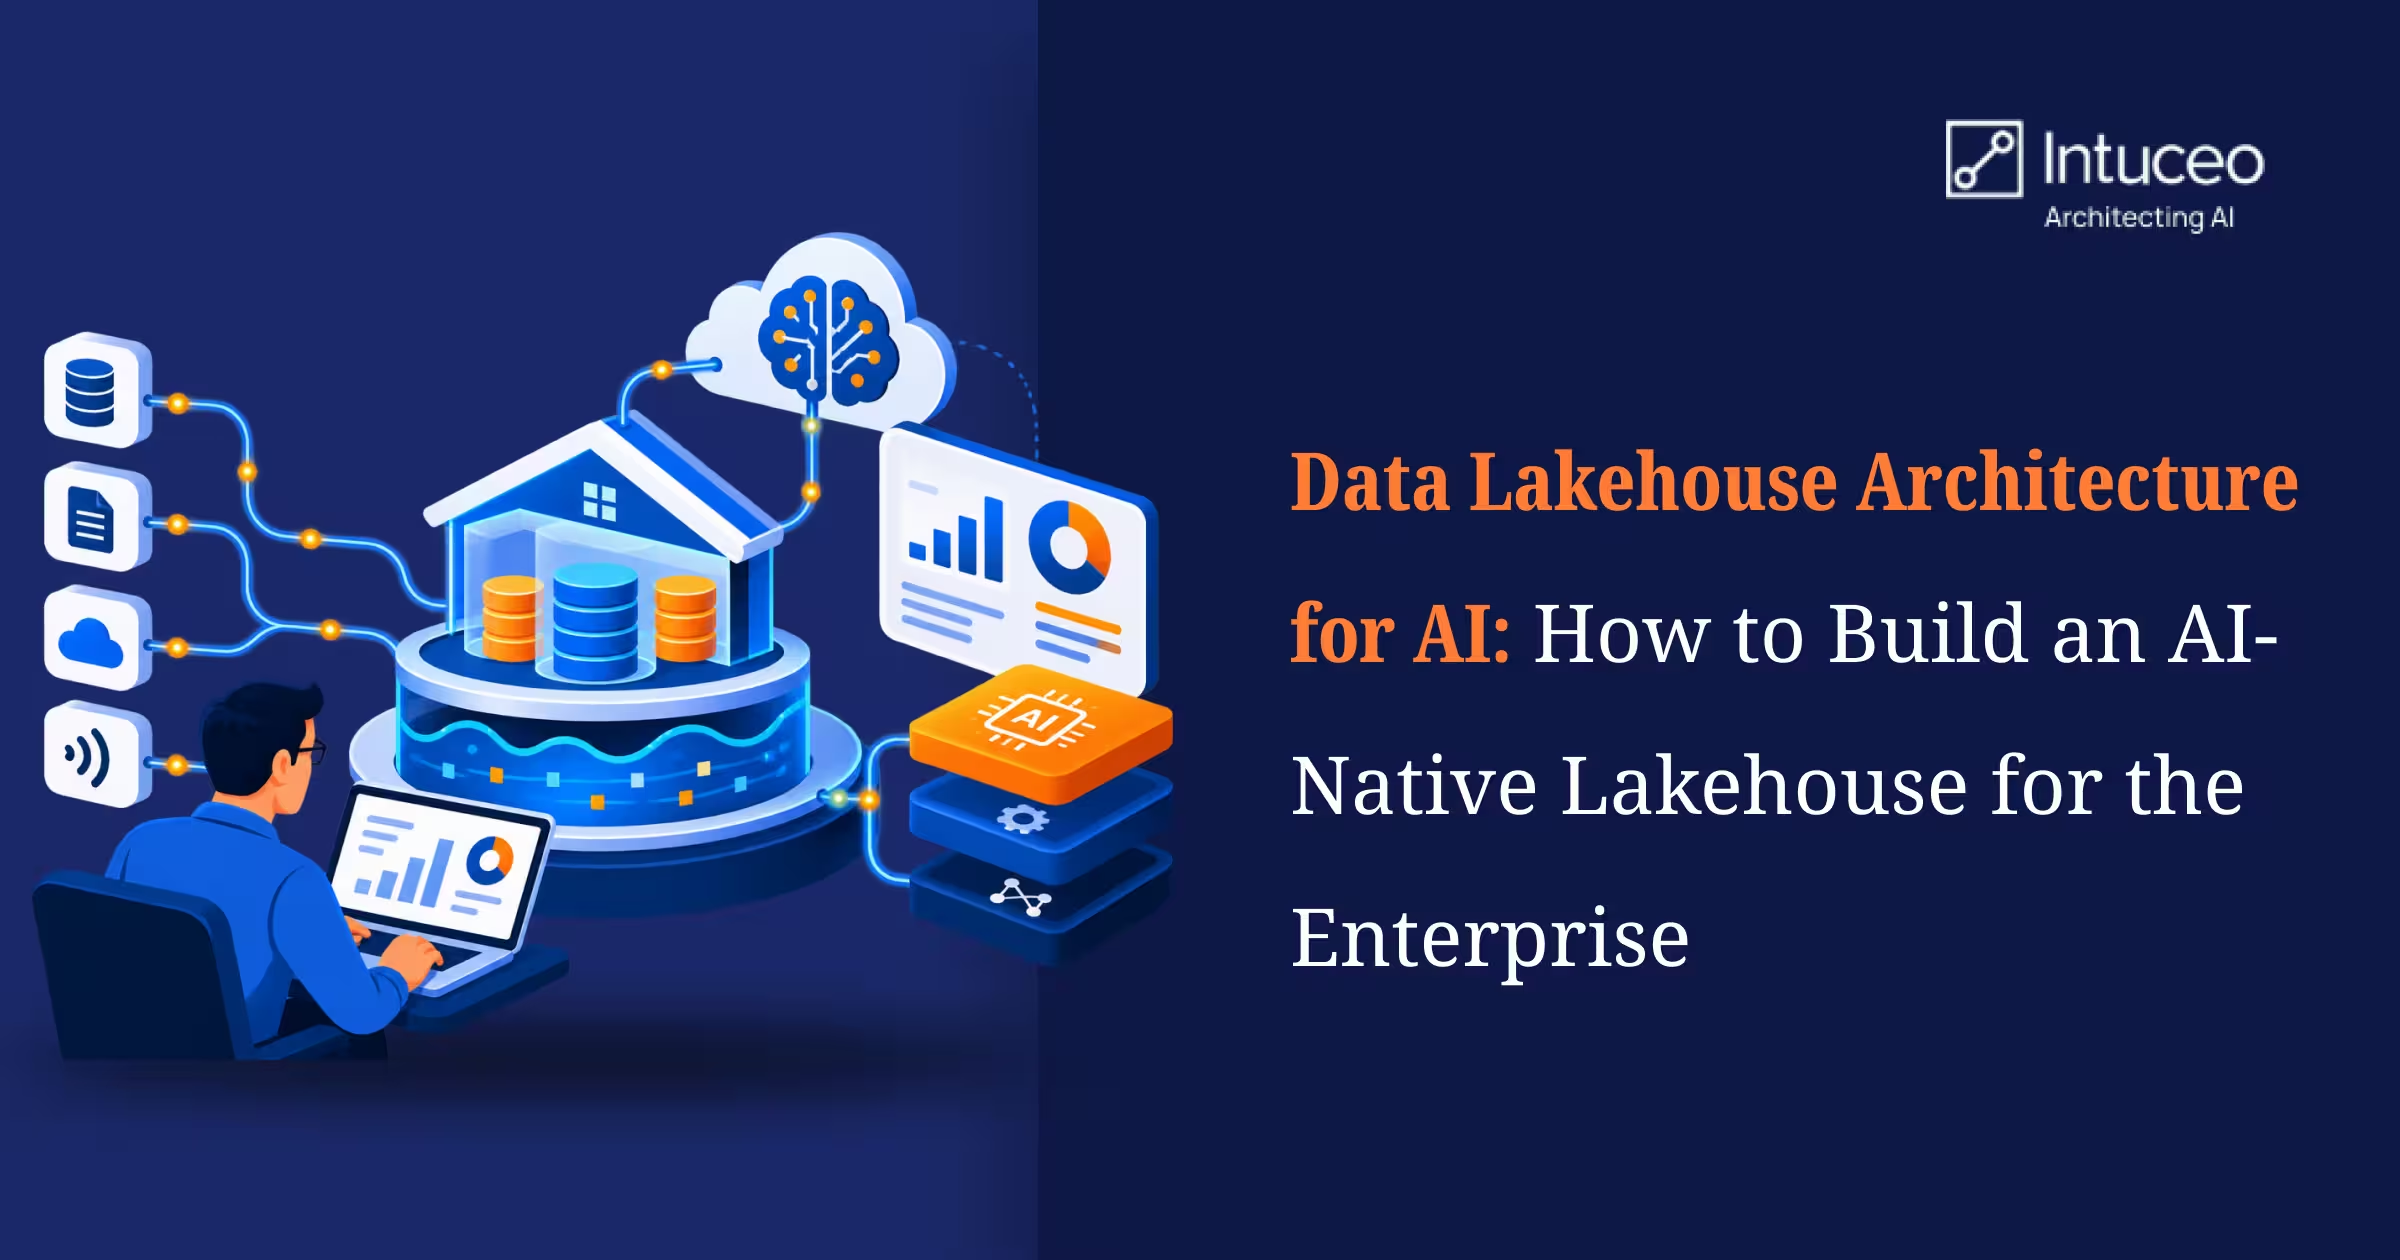
An AI-native lakehouse is a data lakehouse architecture for AI that treats machine learning (ML), feature engineering, and large language model (LLM) retrieval as first-class workloads from day one, built on the same storage, catalog, and lineage that serve traditional analytics.
This guide walks through what makes an enterprise data lakehouse architecture AI-native, a reference layering model, the choice between Databricks and Snowflake for enterprise AI, how MLOps on a lakehouse works, and how to migrate without stalling existing reporting.
Key Takeaways
- An AI-native lakehouse runs BI, model training, feature serving, and LLM retrieval on one governed copy of data.
- Six layers matter: storage, catalog, transformation, features and models, serving, and observability.
- Databricks fits engineering-heavy AI teams. Snowflake fits SQL- and BI-heavy teams adding AI.
- Migrate workload by workload, starting where the warehouse is weakest.
What Is an AI-Native Data Lakehouse?
An AI-native data lakehouse, sometimes called an AI-ready data lakehouse, is a lakehouse built so analytics, model training, feature serving, and LLM retrieval run on one governed copy of data. It stores open table formats such as Delta Lake or Apache Iceberg on object storage and adds vector search, a feature store, and unified catalog governance.
Data Lakehouse vs Data Warehouse: What Makes a Lakehouse AI-Native?
The data lakehouse vs data warehouse comparison usually gets reduced to a cost argument. The bigger difference matters more for AI. A warehouse is built for curated, structured data queried through SQL. A lake accepts everything, but without transactional guarantees or consistent schema, it rarely produces training sets a data scientist could trust twice in a row.
The lakehouse pattern consolidates both using an open table format, Delta Lake, Apache Iceberg, or Apache Hudi, on top of cheap object storage. That gives data teams ACID (atomicity, consistency, isolation, durability) transactions, schema evolution, and time travel against the same files that feed Python notebooks, SQL dashboards, and Spark jobs.
Calling it AI-native adds four things to that foundation:
- Native vector support: embeddings for retrieval-augmented generation sit beside the structured tables they describe, not in a separate database.
- Integrated feature store: features are versioned against the source tables that produced them, so training data can be reproduced on any date.
- Unified governance: one catalog governs tables, features, models, prompts, and the agents that consume them.
- Elastic compute: training, batch inference, streaming, and real-time serving share storage but scale compute independently.
The table below summarizes how the three architectures compare for AI workloads.
| Capability | Data warehouse | Data lake | AI-native lakehouse |
|---|---|---|---|
| Data types | Structured | All types | All types |
| Transactions | ACID | None by default | ACID through open table formats |
| ML and GenAI readiness | Requires export | Raw, often unreliable | Native features, vectors, and models |
| Governance | Strong, warehouse-only | Fragmented | One catalog for data and AI assets |
| Reproducibility | Limited | Weak | Time travel on training data |
Gartner analyst Prasad Pore reports 65% lakehouse adoption among Gartner’s client base, which positions the pattern as the default substrate for new AI workloads rather than a parallel experiment.[1]
Data Lakehouse Architecture for AI: A Six-Layer Reference Model
A workable reference design has six layers. Each has its own failure modes, so each needs its own ownership and controls.
1. Storage Layer: Open Table Formats on Object Storage
Object storage, Amazon S3, Azure Data Lake Storage, or Google Cloud Storage, holding Parquet files under an open table format. Delta Lake and Iceberg are the two formats most enterprise teams converge on. Both give ACID semantics; the choice usually comes down to the compute engine already in play.
2. Catalog and Governance Layer: One Control Plane for Data and AI
Unity Catalog (Databricks’ governance layer), Snowflake Horizon (Snowflake’s governance layer), or an open equivalent such as Apache Polaris (an open Iceberg catalog). This layer carries access control, lineage, and audit for every object the AI stack will touch. Data lakehouse governance decisions made here propagate to features, models, and prompts without re-implementation.
3. Transformation and Quality Layer: The Medallion Pattern
A medallion pattern of Bronze (raw ingest), Silver (cleaned and conformed), and Gold (business-ready) tables, built with Spark, dbt, or SQL. Data quality checks run as pipeline tests, not as a downstream dashboard.
4. Feature and Model Layer: Reproducible Training Data
Feature store, model registry, and experiment tracking. MLflow is the open reference. Features reference the Silver and Gold tables by version, so a training set from last quarter can be rebuilt exactly.
5. Serving and Retrieval Layer: RAG, Features, and Agents
Vector indexes for retrieval-augmented generation (RAG), online feature serving for low-latency inference, and model endpoints for both batch and real-time. For agentic AI workloads, this layer also exposes governed data to the Model Context Protocol or equivalent connectors.
6. Observability Layer: Drift, Health, and Cost
Pipeline health, data drift, model performance, and cost telemetry in one view. Without it, the lakehouse quietly degrades into another cost center.
How Do You Build a Data Lakehouse for AI Workloads?
The answer resolves at the catalog and feature layers. Those two carry the governance and reproducibility that separate production AI from disposable prototypes.
When Should You Choose a Big 4 Firm or Large Integrator for AI?
Databricks vs Snowflake for enterprise AI comes down to starting point: Databricks fits engineering- and ML-heavy teams building models and agents on open formats, while Snowflake fits SQL- and BI-heavy teams adding AI to governed analytics.
Databricks is a Spark-native environment with Delta Lake and Unity Catalog at its core. It appeals to organizations with heavy data engineering and ML workloads, deep Python usage, and a preference for notebook-driven development. MLflow, Model Serving, Vector Search, and Agent Bricks sit on the same catalog as the raw tables. For teams building retrieval pipelines, fine-tuned models, or multi-agent systems against proprietary data, this consolidation is the main argument.
Snowflake began as a SQL-first warehouse and extended into the lakehouse pattern through Iceberg table support, Snowpark for Python and ML, Cortex for LLM features, and Horizon for governance. It suits organizations with substantial SQL and BI investment that want to add AI workloads without rebuilding the analytics layer.
| Factor | Databricks | Snowflake |
|---|---|---|
| Origin | Spark-native lakehouse | SQL-first warehouse |
| Default table format | Delta Lake | Native tables plus Iceberg |
| Governance | Unity Catalog | Horizon |
| ML and GenAI tooling | MLflow, Model Serving, Vector Search, Agent Bricks | Snowpark, Cortex |
| Best fit | Heavy data engineering, Python, custom models, agents | Heavy SQL and BI investment, AI added to analytics |
Delta Lake deserves a note of its own for enterprise AI. As an open table format, Delta Lake runs under both Databricks and increasingly outside it, including through Iceberg interoperability. Time travel, schema enforcement, and change data feed are the properties that make reproducible training sets and auditable model lineage practical rather than aspirational.
The best data lakehouse architecture for AI, in practice, is the one aligned with the organization’s existing skills, cloud footprint, and governance maturity. The decision rarely turns on a feature matrix. It turns on how much of the current stack can carry forward, which is the first thing an Intuceo lakehouse readiness assessment maps.
How Does MLOps Work on a Data Lakehouse?
MLOps on a lakehouse keeps features, training sets, models, and serving endpoints under the same catalog as the source tables that produced them. That matters for three reasons.
First, reproducibility. Time travel on the underlying Delta or Iceberg tables lets a team retrain a model on the exact data version it was first trained on, which is often what regulators and internal audit actually ask for.
Second, lineage. When a model drifts, the engineering team can trace from the serving endpoint back through the feature, the Gold table, the Silver transformation, and the raw Bronze ingest, inside one lineage graph.
Third, governance. Databricks’ 2026 State of AI Agents report, based on telemetry from more than 20,000 organizations, found that companies using AI governance tools put 12 times more AI projects into production than those without.[2] On a lakehouse, that governance is applied once at the catalog layer and inherited by every downstream model, feature, and agent, the principle behind Intuceo’s DARWIN AI governance approach.
For generative AI specifically, the lakehouse also serves as the retrieval substrate for enterprise LLM infrastructure. Vector indexes sit alongside structured tables, so RAG pipelines and agents can combine semantic search with precise filters against the same governed data without copying it into a separate store.
How to Migrate From a Data Warehouse to a Lakehouse Without Breaking Reporting
A full lift-and-shift data warehouse to lakehouse migration rarely succeeds and rarely pays back inside a budget cycle. A workload-first migration does: move the jobs the warehouse handles poorly first, dual-run reporting during cutover, and retire warehouse workloads only once their replacements are proven.
- Start with workloads the warehouse serves poorly: large unstructured datasets, ML feature engineering, and streaming ingest are usually the first candidates.
- Build the Bronze/Silver/Gold layering first: get the medallion pattern working on a narrow domain before expanding.
- Dual-run reporting during cutover: keep the warehouse serving existing dashboards until the lakehouse version is verified against known numbers.
- Govern through one catalog from day one: fragmented permissions during a migration create the exact security exposure the project was meant to reduce.
- Decommission on evidence, not on schedule: a warehouse workload moves off only after its lakehouse replacement meets the same service-level objective at acceptable cost.
Migrations that follow this pattern deliver AI workloads first, which is what justified the move in the first place, and let BI follow once the lakehouse has proven itself on harder problems.
How Intuceo Builds AI-Native Lakehouses for Regulated Industries
Intuceo designs and builds AI-native lakehouses on Databricks and Snowflake for regulated industries, including healthcare, life sciences, and the federal space, with Unity Catalog or Horizon governance applied from day one and MLflow-based model lineage tied to the underlying Delta or Iceberg tables.
Where Intuceo’s delivery differs from a generic data engineering engagement: a reference medallion design hardened across prior client engagements including Florida Blue, GuideWell Health, UF Health, Janssen Pharma, and Bausch & Lomb; accelerators such as Intuceo-Ax™ for explainable classification workloads and iPDLC™ for faster AI delivery; and a 20-year track record engineering compliant data environments for Fortune 1000 and federal clients.
Get a lakehouse readiness assessment of your current stack and a 90-day plan to serve your highest-value AI workload from a governed foundation.
Frequently Asked Questions
1.How do we handle governance and regulatory compliance (HIPAA, SOC 2, GDPR) on an AI-native lakehouse?
Compliance belongs in the catalog and storage layers, not in each downstream tool. Unity Catalog or Horizon enforces access control, row and column masking, audit logging, and lineage once, and every feature, model, and agent that reads governed tables inherits those controls. For regulated workloads such as HIPAA-compliant healthcare analytics, pair that with pipeline-level de-identification and tokenization of personally identifiable information (PII) and protected health information (PHI) so sensitive fields never reach training sets or vector stores unless an approved use case explicitly requires them. Audit evidence then flows from the catalog itself rather than from a parallel compliance report.
2.When should we choose Apache Iceberg over Delta Lake?
Both open table formats offer ACID guarantees, schema evolution, and time travel on object storage. Iceberg has broader cross-engine support across Snowflake, Trino, Spark, Flink, and DuckDB, which makes it the stronger choice when the compute strategy is multi-vendor or likely to shift. Delta Lake has deeper feature maturity on Databricks-centric stacks, including Change Data Feed, Deletion Vectors, and tighter integration with MLflow and Unity Catalog. Interoperability layers such as Delta UniForm now let teams write in one format and read through the other, which reduces the need to pick permanently on day one.
3.How do we avoid vendor lock-in on a lakehouse decision?
Lock-in exposure on a lakehouse is lower than on a warehouse because the data sits in open file and table formats on commodity object storage. Keep the storage layer and the chosen table format decoupled from the compute engine, treat the catalog as a governed abstraction rather than a vendor contract, and avoid encoding critical business logic in proprietary stored procedures or notebook-specific features. Portability becomes a design choice rather than a vendor feature. A lakehouse built this way can be read by multiple engines concurrently and migrated to a different compute vendor without moving the underlying data.
4.How should we govern AI agents that access lakehouse data autonomously?
Agents need their own identities, scoped credentials, and audit trails distinct from the human users who deploy them. Grant least-privilege access through the catalog so an agent sees only the tables, columns, or rows its task actually requires, and route inference traffic through a gateway that enforces rate limits, prompt filtering, and output guardrails. For sensitive data, prefer a retrieval interface over direct table access: the agent requests information through a governed endpoint and never reads raw rows it has no business touching.
5.Is a data lakehouse better than a data warehouse for AI?
For most AI workloads, yes. A lakehouse stores structured and unstructured data together, adds ACID transactions through open table formats, and lets features, models, and vector indexes share one catalog with the source tables. A warehouse still suits curated SQL reporting, which is why many enterprises dual-run both during migration.
6.What are the layers of a data lakehouse architecture for AI?
Six layers: object storage with an open table format, a catalog for governance and lineage, a transformation layer using the Bronze/Silver/Gold medallion pattern, a feature and model layer, a serving and retrieval layer for RAG and agents, and an observability layer for drift, pipeline health, and cost.